# Quick Start
URL: http://www.claudeskills.org/docs
Description: Getting Started with Fumadocs
## Introduction
Fumadocs (Foo-ma docs) is a **documentation framework** based on Next.js, designed to be fast, flexible,
and composes seamlessly into Next.js App Router.
Fumadocs has different parts:
} title='Fumadocs Core'>
Handles most of the logic, including document search, content source adapters, and Markdown extensions.
} title='Fumadocs UI'>
The default theme of Fumadocs offers a beautiful look for documentation sites and interactive components.
} title='Content Source'>
The source of your content, can be a CMS or local data layers like [Content Collections](https://www.content-collections.dev) and [Fumadocs MDX](/docs/mdx), the official content source.
} title='Fumadocs CLI'>
A command line tool to install UI components and automate things, useful for customizing layouts.
Read our in-depth [What is Fumadocs](/docs/what-is-fumadocs) introduction.
### Terminology
**Markdown/MDX:** Markdown is a markup language for creating formatted text. Fumadocs supports Markdown and MDX (superset of Markdown) out-of-the-box.
Although not required, some basic knowledge of Next.js App Router would be useful for further customisations.
## Automatic Installation
A minimum version of Node.js 18 required, note that Node.js 23.1 might have problems with Next.js production build.
```bash tab="npm"
npm create fumadocs-app
```
```bash tab="pnpm"
pnpm create fumadocs-app
```
```bash tab="yarn"
yarn create fumadocs-app
```
```bash tab="bun"
bun create fumadocs-app
```
It will ask you the framework and content source to use, a new fumadocs app should be initialized. Now you can start hacking!
You can follow the [Manual Installation](/docs/manual-installation) guide to get started.
### Enjoy!
Create your first MDX file in the docs folder.
```mdx title="content/docs/index.mdx"
---
title: Hello World
---
## Yo what's up
```
Run the app in development mode and see http://localhost:3000/docs.
```mdx
npm run dev
```
## Explore
In the project, you can see:
- `lib/source.ts`: Code for content source adapter, [`loader()`](/docs/headless/source-api) provides an interface to interact with your content source, and assigns URL to your pages.
- `app/layout.config.tsx`: Shared options for layouts, optional but preferred to keep.
| Route | Description |
| ------------------------- | ------------------------------------------------------ |
| `app/(home)` | The route group for your landing page and other pages. |
| `app/docs` | The documentation layout and pages. |
| `app/api/search/route.ts` | The Route Handler for search. |
### Writing Content
For authoring docs, make sure to read:
Fumadocs has some additional features for authoring content too.
Learn how to customise navigation links/sidebar items.
### Content Source
Content source handles all your content, like compiling Markdown files and validating frontmatter.
Read the [Introduction](/docs/mdx) to learn how it handles your content.
A `source.config.ts` config file has been included, you can customise different options like frontmatter schema.
Fumadocs is not Markdown-exclusive. For other sources like Sanity, you can build a [custom content source](/docs/headless/custom-source).
### Customise UI
See [Customisation Guide](/docs/customisation).
## FAQ
Some common questions you may encounter.
Sometimes, `fumadocs-ui` is not installed in the workspace of your Tailwind CSS configuration file. (e.g. a monorepo setup).
You have to ensure the `fumadocs-ui` package is scanned by Tailwind CSS, and give a correct relative path to `@source`.
For example, add `../../` to point to the `node_modules` folder in root workspace.
```css
@import 'tailwindcss';
@import 'fumadocs-ui/css/neutral.css';
@import 'fumadocs-ui/css/preset.css';
/* [!code --] */
@source '../node_modules/fumadocs-ui/dist/**/*.js';
/* [!code ++] */
@source '../../../node_modules/fumadocs-ui/dist/**/*.js';
```
You can change the base route of docs (e.g. from `/docs/page` to `/info/page`).
Since Fumadocs uses Next.js App Router, you can simply rename the route:
And tell Fumadocs to use the new route in `source.ts`:
```ts title="lib/source.ts"
import { loader } from 'fumadocs-core/source';
export const source = loader({
baseUrl: '/info',
// other options
});
```
Next.js turns dynamic route into static routes when `generateStaticParams` is configured.
Hence, it is as fast as static pages.
You can enable Static Exports on Next.js to get a static build output. (Notice that Route Handler doesn't work with static export, you have to configure static search)
Same as managing layouts in Next.js App Router, remove the original MDX file from content directory (`/content/docs`).
This ensures duplicated pages will not cause errors.
Now, You can add the page to another route group, which isn't a descendant of docs layout.
For example, under your `app` folder:
will replace the `/docs` page with your `page.tsx`.
Use a separate deployment for each version.
On Vercel, this can be done by creating another branch for a specific version on your GitHub repository.
To link to the sites of other versions, use the Links API or a custom navigation component.
We recommend to use [Sidebar Tabs](/docs/navigation/sidebar#sidebar-tabs).
## Video Tutorials
## Learn More
New to here? Don't worry, we are welcome for your questions.
If you find anything confusing, please give your feedback on [Github Discussion](https://github.com/fuma-nama/fumadocs/discussions)!
---
# Best practices
URL: http://www.claudeskills.org/docs/agent-skills/best-practices
Description: Write concise, reliable Agent Skills for Claude.
> Learn how to write effective Skills that Claude can discover and use successfully.
Good Skills are concise, well-structured, and tested with real usage. This guide provides practical authoring decisions to help you write Skills that Claude can discover and use effectively.
For conceptual background on how Skills work, see the [Skills overview](/docs/agent-skills/overview).
## Core principles
### Concise is key
The [context window](/en/docs/build-with-claude/context-windows) is a public good. Your Skill shares the context window with everything else Claude needs to know, including:
* The system prompt
* Conversation history
* Other Skills' metadata
* Your actual request
Not every token in your Skill has an immediate cost. At startup, only the metadata (name and description) from all Skills is pre-loaded. Claude reads SKILL.md only when the Skill becomes relevant, and reads additional files only as needed. However, being concise in SKILL.md still matters: once Claude loads it, every token competes with conversation history and other context.
**Default assumption**: Claude is already very smart
Only add context Claude doesn't already have. Challenge each piece of information:
* "Does Claude really need this explanation?"
* "Can I assume Claude knows this?"
* "Does this paragraph justify its token cost?"
**Good example: Concise** (approximately 50 tokens):
````markdown
## Extract PDF text
Use pdfplumber for text extraction:
```python
import pdfplumber
with pdfplumber.open("file.pdf") as pdf:
text = pdf.pages[0].extract_text()
```
````
**Bad example: Too verbose** (approximately 150 tokens):
```markdown
## Extract PDF text
PDF (Portable Document Format) files are a common file format that contains
text, images, and other content. To extract text from a PDF, you'll need to
use a library. There are many libraries available for PDF processing, but we
recommend pdfplumber because it's easy to use and handles most cases well.
First, you'll need to install it using pip. Then you can use the code below...
```
The concise version assumes Claude knows what PDFs are and how libraries work.
### Set appropriate degrees of freedom
Match the level of specificity to the task's fragility and variability.
**High freedom** (text-based instructions):
Use when:
* Multiple approaches are valid
* Decisions depend on context
* Heuristics guide the approach
Example:
```markdown
## Code review process
1. Analyze the code structure and organization
2. Check for potential bugs or edge cases
3. Suggest improvements for readability and maintainability
4. Verify adherence to project conventions
```
**Medium freedom** (pseudocode or scripts with parameters):
Use when:
* A preferred pattern exists
* Some variation is acceptable
* Configuration affects behavior
Example:
````markdown
## Generate report
Use this template and customize as needed:
```python
def generate_report(data, format="markdown", include_charts=True):
# Process data
# Generate output in specified format
# Optionally include visualizations
```
````
**Low freedom** (specific scripts, few or no parameters):
Use when:
* Operations are fragile and error-prone
* Consistency is critical
* A specific sequence must be followed
Example:
````markdown
## Database migration
Run exactly this script:
```bash
python scripts/migrate.py --verify --backup
```
Do not modify the command or add additional flags.
````
**Analogy**: Think of Claude as a robot exploring a path:
* **Narrow bridge with cliffs on both sides**: There's only one safe way forward. Provide specific guardrails and exact instructions (low freedom). Example: database migrations that must run in exact sequence.
* **Open field with no hazards**: Many paths lead to success. Give general direction and trust Claude to find the best route (high freedom). Example: code reviews where context determines the best approach.
### Test with all models you plan to use
Skills act as additions to models, so effectiveness depends on the underlying model. Test your Skill with all the models you plan to use it with.
**Testing considerations by model**:
* **Claude Haiku** (fast, economical): Does the Skill provide enough guidance?
* **Claude Sonnet** (balanced): Is the Skill clear and efficient?
* **Claude Opus** (powerful reasoning): Does the Skill avoid over-explaining?
What works perfectly for Opus might need more detail for Haiku. If you plan to use your Skill across multiple models, aim for instructions that work well with all of them.
## Skill structure
**YAML Frontmatter**: The SKILL.md frontmatter supports two fields:
* `name` - Human-readable name of the Skill (64 characters maximum)
* `description` - One-line description of what the Skill does and when to use it (1024 characters maximum)
For complete Skill structure details, see the [Skills overview](/docs/agent-skills/overview#skill-structure).
### Naming conventions
Use consistent naming patterns to make Skills easier to reference and discuss. We recommend using **gerund form** (verb + -ing) for Skill names, as this clearly describes the activity or capability the Skill provides.
**Good naming examples (gerund form)**:
* "Processing PDFs"
* "Analyzing spreadsheets"
* "Managing databases"
* "Testing code"
* "Writing documentation"
**Acceptable alternatives**:
* Noun phrases: "PDF Processing", "Spreadsheet Analysis"
* Action-oriented: "Process PDFs", "Analyze Spreadsheets"
**Avoid**:
* Vague names: "Helper", "Utils", "Tools"
* Overly generic: "Documents", "Data", "Files"
* Inconsistent patterns within your skill collection
Consistent naming makes it easier to:
* Reference Skills in documentation and conversations
* Understand what a Skill does at a glance
* Organize and search through multiple Skills
* Maintain a professional, cohesive skill library
### Writing effective descriptions
The `description` field enables Skill discovery and should include both what the Skill does and when to use it.
**Always write in third person**. The description is injected into the system prompt, and inconsistent point-of-view can cause discovery problems.
* **Good:** "Processes Excel files and generates reports"
* **Avoid:** "I can help you process Excel files"
* **Avoid:** "You can use this to process Excel files"
**Be specific and include key terms**. Include both what the Skill does and specific triggers/contexts for when to use it.
Each Skill has exactly one description field. The description is critical for skill selection: Claude uses it to choose the right Skill from potentially 100+ available Skills. Your description must provide enough detail for Claude to know when to select this Skill, while the rest of SKILL.md provides the implementation details.
Effective examples:
**PDF Processing skill:**
```yaml
description: Extract text and tables from PDF files, fill forms, merge documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
```
**Excel Analysis skill:**
```yaml
description: Analyze Excel spreadsheets, create pivot tables, generate charts. Use when analyzing Excel files, spreadsheets, tabular data, or .xlsx files.
```
**Git Commit Helper skill:**
```yaml
description: Generate descriptive commit messages by analyzing git diffs. Use when the user asks for help writing commit messages or reviewing staged changes.
```
Avoid vague descriptions like these:
```yaml
description: Helps with documents
```
```yaml
description: Processes data
```
```yaml
description: Does stuff with files
```
### Progressive disclosure patterns
SKILL.md serves as an overview that points Claude to detailed materials as needed, like a table of contents in an onboarding guide. For an explanation of how progressive disclosure works, see [How Skills work](/docs/agent-skills/overview#how-skills-work) in the overview.
**Practical guidance:**
* Keep SKILL.md body under 500 lines for optimal performance
* Split content into separate files when approaching this limit
* Use the patterns below to organize instructions, code, and resources effectively
#### Visual overview: From simple to complex
A basic Skill starts with just a SKILL.md file containing metadata and instructions:
As your Skill grows, you can bundle additional content that Claude loads only when needed:
The complete Skill directory structure might look like this:
```
pdf/
|-- SKILL.md # Main instructions (loaded when triggered)
|-- FORMS.md # Form-filling guide (loaded as needed)
|-- reference.md # API reference (loaded as needed)
|-- examples.md # Usage examples (loaded as needed)
`-- scripts/
|-- analyze_form.py # Utility script (executed, not loaded)
|-- fill_form.py # Form filling script
`-- validate.py # Validation script
```
#### Pattern 1: High-level guide with references
````markdown
---
name: PDF Processing
description: Extracts text and tables from PDF files, fills forms, and merges documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
---
# PDF Processing
## Quick start
Extract text with pdfplumber:
```python
import pdfplumber
with pdfplumber.open("file.pdf") as pdf:
text = pdf.pages[0].extract_text()
```
## Advanced features
**Form filling**: See [FORMS.md](FORMS.md) for complete guide
**API reference**: See [REFERENCE.md](REFERENCE.md) for all methods
**Examples**: See [EXAMPLES.md](EXAMPLES.md) for common patterns
````
Claude loads FORMS.md, REFERENCE.md, or EXAMPLES.md only when needed.
#### Pattern 2: Domain-specific organization
For Skills with multiple domains, organize content by domain to avoid loading irrelevant context. When a user asks about sales metrics, Claude only needs to read sales-related schemas, not finance or marketing data. This keeps token usage low and context focused.
```
bigquery-skill/
|-- SKILL.md (overview and navigation)
`-- reference/
|-- finance.md (revenue, billing metrics)
|-- sales.md (opportunities, pipeline)
|-- product.md (API usage, features)
`-- marketing.md (campaigns, attribution)
```
````markdown
# BigQuery Data Analysis
## Available datasets
**Finance**: Revenue, ARR, billing -> See [reference/finance.md](reference/finance.md)
**Sales**: Opportunities, pipeline, accounts -> See [reference/sales.md](reference/sales.md)
**Product**: API usage, features, adoption -> See [reference/product.md](reference/product.md)
**Marketing**: Campaigns, attribution, email -> See [reference/marketing.md](reference/marketing.md)
## Quick search
Find specific metrics using grep:
```bash
grep -i "revenue" reference/finance.md
grep -i "pipeline" reference/sales.md
grep -i "api usage" reference/product.md
```
````
#### Pattern 3: Conditional details
Show basic content, link to advanced content:
```markdown
# DOCX Processing
## Creating documents
Use docx-js for new documents. See [DOCX-JS.md](DOCX-JS.md).
## Editing documents
For simple edits, modify the XML directly.
**For tracked changes**: See [REDLINING.md](REDLINING.md)
**For OOXML details**: See [OOXML.md](OOXML.md)
```
Claude reads REDLINING.md or OOXML.md only when the user needs those features.
### Avoid deeply nested references
Claude may partially read files when they're referenced from other referenced files. When encountering nested references, Claude might use commands like `head -100` to preview content rather than reading entire files, resulting in incomplete information.
**Keep references one level deep from SKILL.md**. All reference files should link directly from SKILL.md to ensure Claude reads complete files when needed.
**Bad example: Too deep**:
```markdown
# SKILL.md
See [advanced.md](advanced.md)...
# advanced.md
See [details.md](details.md)...
# details.md
Here's the actual information...
```
**Good example: One level deep**:
```markdown
# SKILL.md
**Basic usage**: [instructions in SKILL.md]
**Advanced features**: See [advanced.md](advanced.md)
**API reference**: See [reference.md](reference.md)
**Examples**: See [examples.md](examples.md)
```
### Structure longer reference files with table of contents
For reference files longer than 100 lines, include a table of contents at the top. This ensures Claude can see the full scope of available information even when previewing with partial reads.
**Example**:
```markdown
# API Reference
## Contents
- Authentication and setup
- Core methods (create, read, update, delete)
- Advanced features (batch operations, webhooks)
- Error handling patterns
- Code examples
## Authentication and setup
...
## Core methods
...
```
Claude can then read the complete file or jump to specific sections as needed.
For details on how this filesystem-based architecture enables progressive disclosure, see the [Runtime environment](#runtime-environment) section in the Advanced section below.
## Workflows and feedback loops
### Use workflows for complex tasks
Break complex operations into clear, sequential steps. For particularly complex workflows, provide a checklist that Claude can copy into its response and check off as it progresses.
**Example 1: Research synthesis workflow** (for Skills without code):
````markdown
## Research synthesis workflow
Copy this checklist and track your progress:
```
Research Progress:
- [ ] Step 1: Read all source documents
- [ ] Step 2: Identify key themes
- [ ] Step 3: Cross-reference claims
- [ ] Step 4: Create structured summary
- [ ] Step 5: Verify citations
```
**Step 1: Read all source documents**
Review each document in the `sources/` directory. Note the main arguments and supporting evidence.
**Step 2: Identify key themes**
Look for patterns across sources. What themes appear repeatedly? Where do sources agree or disagree?
**Step 3: Cross-reference claims**
For each major claim, verify it appears in the source material. Note which source supports each point.
**Step 4: Create structured summary**
Organize findings by theme. Include:
- Main claim
- Supporting evidence from sources
- Conflicting viewpoints (if any)
**Step 5: Verify citations**
Check that every claim references the correct source document. If citations are incomplete, return to Step 3.
````
This example shows how workflows apply to analysis tasks that don't require code. The checklist pattern works for any complex, multi-step process.
**Example 2: PDF form filling workflow** (for Skills with code):
````markdown
## PDF form filling workflow
Copy this checklist and check off items as you complete them:
```
Task Progress:
- [ ] Step 1: Analyze the form (run analyze_form.py)
- [ ] Step 2: Create field mapping (edit fields.json)
- [ ] Step 3: Validate mapping (run validate_fields.py)
- [ ] Step 4: Fill the form (run fill_form.py)
- [ ] Step 5: Verify output (run verify_output.py)
```
**Step 1: Analyze the form**
Run: `python scripts/analyze_form.py input.pdf`
This extracts form fields and their locations, saving to `fields.json`.
**Step 2: Create field mapping**
Edit `fields.json` to add values for each field.
**Step 3: Validate mapping**
Run: `python scripts/validate_fields.py fields.json`
Fix any validation errors before continuing.
**Step 4: Fill the form**
Run: `python scripts/fill_form.py input.pdf fields.json output.pdf`
**Step 5: Verify output**
Run: `python scripts/verify_output.py output.pdf`
If verification fails, return to Step 2.
````
Clear steps prevent Claude from skipping critical validation. The checklist helps both Claude and you track progress through multi-step workflows.
### Implement feedback loops
**Common pattern**: Run validator -> fix errors -> repeat
This pattern greatly improves output quality.
**Example 1: Style guide compliance** (for Skills without code):
```markdown
## Content review process
1. Draft your content following the guidelines in STYLE_GUIDE.md
2. Review against the checklist:
- Check terminology consistency
- Verify examples follow the standard format
- Confirm all required sections are present
3. If issues found:
- Note each issue with specific section reference
- Revise the content
- Review the checklist again
4. Only proceed when all requirements are met
5. Finalize and save the document
```
This shows the validation loop pattern using reference documents instead of scripts. The "validator" is STYLE\_GUIDE.md, and Claude performs the check by reading and comparing.
**Example 2: Document editing process** (for Skills with code):
```markdown
## Document editing process
1. Make your edits to `word/document.xml`
2. **Validate immediately**: `python ooxml/scripts/validate.py unpacked_dir/`
3. If validation fails:
- Review the error message carefully
- Fix the issues in the XML
- Run validation again
4. **Only proceed when validation passes**
5. Rebuild: `python ooxml/scripts/pack.py unpacked_dir/ output.docx`
6. Test the output document
```
The validation loop catches errors early.
## Content guidelines
### Avoid time-sensitive information
Don't include information that will become outdated:
**Bad example: Time-sensitive** (will become wrong):
```markdown
If you're doing this before August 2025, use the old API.
After August 2025, use the new API.
```
**Good example** (use "old patterns" section):
```markdown
## Current method
Use the v2 API endpoint: `api.example.com/v2/messages`
## Old patterns
Legacy v1 API (deprecated 2025-08)
The v1 API used: `api.example.com/v1/messages`
This endpoint is no longer supported.
```
The old patterns section provides historical context without cluttering the main content.
### Use consistent terminology
Choose one term and use it throughout the Skill:
**Good - Consistent**:
* Always "API endpoint"
* Always "field"
* Always "extract"
**Bad - Inconsistent**:
* Mix "API endpoint", "URL", "API route", "path"
* Mix "field", "box", "element", "control"
* Mix "extract", "pull", "get", "retrieve"
Consistency helps Claude understand and follow instructions.
## Common patterns
### Template pattern
Provide templates for output format. Match the level of strictness to your needs.
**For strict requirements** (like API responses or data formats):
````markdown
## Report structure
ALWAYS use this exact template structure:
```markdown
# [Analysis Title]
## Executive summary
[One-paragraph overview of key findings]
## Key findings
- Finding 1 with supporting data
- Finding 2 with supporting data
- Finding 3 with supporting data
## Recommendations
1. Specific actionable recommendation
2. Specific actionable recommendation
```
````
**For flexible guidance** (when adaptation is useful):
````markdown
## Report structure
Here is a sensible default format, but use your best judgment based on the analysis:
```markdown
# [Analysis Title]
## Executive summary
[Overview]
## Key findings
[Adapt sections based on what you discover]
## Recommendations
[Tailor to the specific context]
```
Adjust sections as needed for the specific analysis type.
````
### Examples pattern
For Skills where output quality depends on seeing examples, provide input/output pairs just like in regular prompting:
````markdown
## Commit message format
Generate commit messages following these examples:
**Example 1:**
Input: Added user authentication with JWT tokens
Output:
```
feat(auth): implement JWT-based authentication
Add login endpoint and token validation middleware
```
**Example 2:**
Input: Fixed bug where dates displayed incorrectly in reports
Output:
```
fix(reports): correct date formatting in timezone conversion
Use UTC timestamps consistently across report generation
```
**Example 3:**
Input: Updated dependencies and refactored error handling
Output:
```
chore: update dependencies and refactor error handling
- Upgrade lodash to 4.17.21
- Standardize error response format across endpoints
```
Follow this style: type(scope): brief description, then detailed explanation.
````
Examples help Claude understand the desired style and level of detail more clearly than descriptions alone.
### Conditional workflow pattern
Guide Claude through decision points:
```markdown
## Document modification workflow
1. Determine the modification type:
**Creating new content?** -> Follow "Creation workflow" below
**Editing existing content?** -> Follow "Editing workflow" below
2. Creation workflow:
- Use docx-js library
- Build document from scratch
- Export to .docx format
3. Editing workflow:
- Unpack existing document
- Modify XML directly
- Validate after each change
- Repack when complete
```
If workflows become large or complicated with many steps, consider pushing them into separate files and tell Claude to read the appropriate file based on the task at hand.
## Evaluation and iteration
### Build evaluations first
**Create evaluations BEFORE writing extensive documentation.** This ensures your Skill solves real problems rather than documenting imagined ones.
**Evaluation-driven development:**
1. **Identify gaps**: Run Claude on representative tasks without a Skill. Document specific failures or missing context
2. **Create evaluations**: Build three scenarios that test these gaps
3. **Establish baseline**: Measure Claude's performance without the Skill
4. **Write minimal instructions**: Create just enough content to address the gaps and pass evaluations
5. **Iterate**: Execute evaluations, compare against baseline, and refine
This approach ensures you're solving actual problems rather than anticipating requirements that may never materialize.
**Evaluation structure**:
```json
{
"skills": ["pdf-processing"],
"query": "Extract all text from this PDF file and save it to output.txt",
"files": ["test-files/document.pdf"],
"expected_behavior": [
"Successfully reads the PDF file using an appropriate PDF processing library or command-line tool",
"Extracts text content from all pages in the document without missing any pages",
"Saves the extracted text to a file named output.txt in a clear, readable format"
]
}
```
This example demonstrates a data-driven evaluation with a simple testing rubric. We do not currently provide a built-in way to run these evaluations. Users can create their own evaluation system. Evaluations are your source of truth for measuring Skill effectiveness.
### Develop Skills iteratively with Claude
The most effective Skill development process involves Claude itself. Work with one instance of Claude ("Claude A") to create a Skill that will be used by other instances ("Claude B"). Claude A helps you design and refine instructions, while Claude B tests them in real tasks. This works because Claude models understand both how to write effective agent instructions and what information agents need.
**Creating a new Skill:**
1. **Complete a task without a Skill**: Work through a problem with Claude A using normal prompting. As you work, you'll naturally provide context, explain preferences, and share procedural knowledge. Notice what information you repeatedly provide.
2. **Identify the reusable pattern**: After completing the task, identify what context you provided that would be useful for similar future tasks.
**Example**: If you worked through a BigQuery analysis, you might have provided table names, field definitions, filtering rules (like "always exclude test accounts"), and common query patterns.
3. **Ask Claude A to create a Skill**: "Create a Skill that captures this BigQuery analysis pattern we just used. Include the table schemas, naming conventions, and the rule about filtering test accounts."
Claude models understand the Skill format and structure natively. You don't need special system prompts or a "writing skills" skill to get Claude to help create Skills. Simply ask Claude to create a Skill and it will generate properly structured SKILL.md content with appropriate frontmatter and body content.
4. **Review for conciseness**: Check that Claude A hasn't added unnecessary explanations. Ask: "Remove the explanation about what win rate means - Claude already knows that."
5. **Improve information architecture**: Ask Claude A to organize the content more effectively. For example: "Organize this so the table schema is in a separate reference file. We might add more tables later."
6. **Test on similar tasks**: Use the Skill with Claude B (a fresh instance with the Skill loaded) on related use cases. Observe whether Claude B finds the right information, applies rules correctly, and handles the task successfully.
7. **Iterate based on observation**: If Claude B struggles or misses something, return to Claude A with specifics: "When Claude used this Skill, it forgot to filter by date for Q4. Should we add a section about date filtering patterns?"
**Iterating on existing Skills:**
The same hierarchical pattern continues when improving Skills. You alternate between:
* **Working with Claude A** (the expert who helps refine the Skill)
* **Testing with Claude B** (the agent using the Skill to perform real work)
* **Observing Claude B's behavior** and bringing insights back to Claude A
1. **Use the Skill in real workflows**: Give Claude B (with the Skill loaded) actual tasks, not test scenarios
2. **Observe Claude B's behavior**: Note where it struggles, succeeds, or makes unexpected choices
**Example observation**: "When I asked Claude B for a regional sales report, it wrote the query but forgot to filter out test accounts, even though the Skill mentions this rule."
3. **Return to Claude A for improvements**: Share the current SKILL.md and describe what you observed. Ask: "I noticed Claude B forgot to filter test accounts when I asked for a regional report. The Skill mentions filtering, but maybe it's not prominent enough?"
4. **Review Claude A's suggestions**: Claude A might suggest reorganizing to make rules more prominent, using stronger language like "MUST filter" instead of "always filter", or restructuring the workflow section.
5. **Apply and test changes**: Update the Skill with Claude A's refinements, then test again with Claude B on similar requests
6. **Repeat based on usage**: Continue this observe-refine-test cycle as you encounter new scenarios. Each iteration improves the Skill based on real agent behavior, not assumptions.
**Gathering team feedback:**
1. Share Skills with teammates and observe their usage
2. Ask: Does the Skill activate when expected? Are instructions clear? What's missing?
3. Incorporate feedback to address blind spots in your own usage patterns
**Why this approach works**: Claude A understands agent needs, you provide domain expertise, Claude B reveals gaps through real usage, and iterative refinement improves Skills based on observed behavior rather than assumptions.
### Observe how Claude navigates Skills
As you iterate on Skills, pay attention to how Claude actually uses them in practice. Watch for:
* **Unexpected exploration paths**: Does Claude read files in an order you didn't anticipate? This might indicate your structure isn't as intuitive as you thought
* **Missed connections**: Does Claude fail to follow references to important files? Your links might need to be more explicit or prominent
* **Overreliance on certain sections**: If Claude repeatedly reads the same file, consider whether that content should be in the main SKILL.md instead
* **Ignored content**: If Claude never accesses a bundled file, it might be unnecessary or poorly signaled in the main instructions
Iterate based on these observations rather than assumptions. The 'name' and 'description' in your Skill's metadata are particularly critical. Claude uses these when deciding whether to trigger the Skill in response to the current task. Make sure they clearly describe what the Skill does and when it should be used.
## Anti-patterns to avoid
### Avoid Windows-style paths
Always use forward slashes in file paths, even on Windows:
* **Good**: `scripts/helper.py`, `reference/guide.md`
* **Avoid**: `scripts\helper.py`, `reference\guide.md`
Unix-style paths work across all platforms, while Windows-style paths cause errors on Unix systems.
### Avoid offering too many options
Don't present multiple approaches unless necessary:
````markdown
**Bad example: Too many choices** (confusing):
"You can use pypdf, or pdfplumber, or PyMuPDF, or pdf2image, or..."
**Good example: Provide a default** (with escape hatch):
"Use pdfplumber for text extraction:
```python
import pdfplumber
```
For scanned PDFs requiring OCR, use pdf2image with pytesseract instead."
````
## Advanced: Skills with executable code
The sections below focus on Skills that include executable scripts. If your Skill uses only markdown instructions, skip to [Checklist for effective Skills](#checklist-for-effective-skills).
### Solve, don't punt
When writing scripts for Skills, handle error conditions rather than punting to Claude.
**Good example: Handle errors explicitly**:
```python
def process_file(path):
"""Process a file, creating it if it doesn't exist."""
try:
with open(path) as f:
return f.read()
except FileNotFoundError:
# Create file with default content instead of failing
print(f"File {path} not found, creating default")
with open(path, 'w') as f:
f.write('')
return ''
except PermissionError:
# Provide alternative instead of failing
print(f"Cannot access {path}, using default")
return ''
```
**Bad example: Punt to Claude**:
```python
def process_file(path):
# Just fail and let Claude figure it out
return open(path).read()
```
Configuration parameters should also be justified and documented to avoid "voodoo constants" (Ousterhout's law). If you don't know the right value, how will Claude determine it?
**Good example: Self-documenting**:
```python
# HTTP requests typically complete within 30 seconds
# Longer timeout accounts for slow connections
REQUEST_TIMEOUT = 30
# Three retries balances reliability vs speed
# Most intermittent failures resolve by the second retry
MAX_RETRIES = 3
```
**Bad example: Magic numbers**:
```python
TIMEOUT = 47 # Why 47?
RETRIES = 5 # Why 5?
```
### Provide utility scripts
Even if Claude could write a script, pre-made scripts offer advantages:
**Benefits of utility scripts**:
* More reliable than generated code
* Save tokens (no need to include code in context)
* Save time (no code generation required)
* Ensure consistency across uses
The diagram above shows how executable scripts work alongside instruction files. The instruction file (forms.md) references the script, and Claude can execute it without loading its contents into context.
**Important distinction**: Make clear in your instructions whether Claude should:
* **Execute the script** (most common): "Run `analyze_form.py` to extract fields"
* **Read it as reference** (for complex logic): "See `analyze_form.py` for the field extraction algorithm"
For most utility scripts, execution is preferred because it's more reliable and efficient. See the [Runtime environment](#runtime-environment) section below for details on how script execution works.
**Example**:
````markdown
## Utility scripts
**analyze_form.py**: Extract all form fields from PDF
```bash
python scripts/analyze_form.py input.pdf > fields.json
```
Output format:
```json
{
"field_name": {"type": "text", "x": 100, "y": 200},
"signature": {"type": "sig", "x": 150, "y": 500}
}
```
**validate_boxes.py**: Check for overlapping bounding boxes
```bash
python scripts/validate_boxes.py fields.json
# Returns: "OK" or lists conflicts
```
**fill_form.py**: Apply field values to PDF
```bash
python scripts/fill_form.py input.pdf fields.json output.pdf
```
````
### Use visual analysis
When inputs can be rendered as images, have Claude analyze them:
````markdown
## Form layout analysis
1. Convert PDF to images:
```bash
python scripts/pdf_to_images.py form.pdf
```
2. Analyze each page image to identify form fields
3. Claude can see field locations and types visually
````
In this example, you'd need to write the `pdf_to_images.py` script.
Claude's vision capabilities help understand layouts and structures.
### Create verifiable intermediate outputs
When Claude performs complex, open-ended tasks, it can make mistakes. The "plan-validate-execute" pattern catches errors early by having Claude first create a plan in a structured format, then validate that plan with a script before executing it.
**Example**: Imagine asking Claude to update 50 form fields in a PDF based on a spreadsheet. Without validation, Claude might reference non-existent fields, create conflicting values, miss required fields, or apply updates incorrectly.
**Solution**: Use the workflow pattern shown above (PDF form filling), but add an intermediate `changes.json` file that gets validated before applying changes. The workflow becomes: analyze -> **create plan file** -> **validate plan** -> execute -> verify.
**Why this pattern works:**
* **Catches errors early**: Validation finds problems before changes are applied
* **Machine-verifiable**: Scripts provide objective verification
* **Reversible planning**: Claude can iterate on the plan without touching originals
* **Clear debugging**: Error messages point to specific problems
**When to use**: Batch operations, destructive changes, complex validation rules, high-stakes operations.
**Implementation tip**: Make validation scripts verbose with specific error messages like "Field 'signature\_date' not found. Available fields: customer\_name, order\_total, signature\_date\_signed" to help Claude fix issues.
### Package dependencies
Skills run in the code execution environment with platform-specific limitations:
* **claude.ai**: Can install packages from npm and PyPI and pull from GitHub repositories
* **Anthropic API**: Has no network access and no runtime package installation
List required packages in your SKILL.md and verify they're available in the [code execution tool documentation](/en/docs/agents-and-tools/tool-use/code-execution-tool).
### Runtime environment
Skills run in a code execution environment with filesystem access, bash commands, and code execution capabilities. For the conceptual explanation of this architecture, see [The Skills architecture](/docs/agent-skills/overview#the-skills-architecture) in the overview.
**How this affects your authoring:**
**How Claude accesses Skills:**
1. **Metadata pre-loaded**: At startup, the name and description from all Skills' YAML frontmatter are loaded into the system prompt
2. **Files read on-demand**: Claude uses bash Read tools to access SKILL.md and other files from the filesystem when needed
3. **Scripts executed efficiently**: Utility scripts can be executed via bash without loading their full contents into context. Only the script's output consumes tokens
4. **No context penalty for large files**: Reference files, data, or documentation don't consume context tokens until actually read
* **File paths matter**: Claude navigates your skill directory like a filesystem. Use forward slashes (`reference/guide.md`), not backslashes
* **Name files descriptively**: Use names that indicate content: `form_validation_rules.md`, not `doc2.md`
* **Organize for discovery**: Structure directories by domain or feature
* Good: `reference/finance.md`, `reference/sales.md`
* Bad: `docs/file1.md`, `docs/file2.md`
* **Bundle comprehensive resources**: Include complete API docs, extensive examples, large datasets; no context penalty until accessed
* **Prefer scripts for deterministic operations**: Write `validate_form.py` rather than asking Claude to generate validation code
* **Make execution intent clear**:
* "Run `analyze_form.py` to extract fields" (execute)
* "See `analyze_form.py` for the extraction algorithm" (read as reference)
* **Test file access patterns**: Verify Claude can navigate your directory structure by testing with real requests
**Example:**
```
bigquery-skill/
|-- SKILL.md (overview, points to reference files)
`-- reference/
|-- finance.md (revenue metrics)
|-- sales.md (pipeline data)
`-- product.md (usage analytics)
```
When the user asks about revenue, Claude reads SKILL.md, sees the reference to `reference/finance.md`, and invokes bash to read just that file. The sales.md and product.md files remain on the filesystem, consuming zero context tokens until needed. This filesystem-based model is what enables progressive disclosure. Claude can navigate and selectively load exactly what each task requires.
For complete details on the technical architecture, see [How Skills work](/docs/agent-skills/overview#how-skills-work) in the Skills overview.
### MCP tool references
If your Skill uses MCP (Model Context Protocol) tools, always use fully qualified tool names to avoid "tool not found" errors.
**Format**: `ServerName:tool_name`
**Example**:
```markdown
Use the BigQuery:bigquery_schema tool to retrieve table schemas.
Use the GitHub:create_issue tool to create issues.
```
Where:
* `BigQuery` and `GitHub` are MCP server names
* `bigquery_schema` and `create_issue` are the tool names within those servers
Without the server prefix, Claude may fail to locate the tool, especially when multiple MCP servers are available.
### Avoid assuming tools are installed
Don't assume packages are available:
````markdown
**Bad example: Assumes installation**:
"Use the pdf library to process the file."
**Good example: Explicit about dependencies**:
"Install required package: `pip install pypdf`
Then use it:
```python
from pypdf import PdfReader
reader = PdfReader("file.pdf")
```
````
## Technical notes
### YAML frontmatter requirements
The SKILL.md frontmatter includes only `name` (64 characters max) and `description` (1024 characters max) fields. See the [Skills overview](/docs/agent-skills/overview#skill-structure) for complete structure details.
### Token budgets
Keep SKILL.md body under 500 lines for optimal performance. If your content exceeds this, split it into separate files using the progressive disclosure patterns described earlier. For architectural details, see the [Skills overview](/docs/agent-skills/overview#how-skills-work).
## Checklist for effective Skills
Before sharing a Skill, verify:
### Core quality
* [ ] Description is specific and includes key terms
* [ ] Description includes both what the Skill does and when to use it
* [ ] SKILL.md body is under 500 lines
* [ ] Additional details are in separate files (if needed)
* [ ] No time-sensitive information (or in "old patterns" section)
* [ ] Consistent terminology throughout
* [ ] Examples are concrete, not abstract
* [ ] File references are one level deep
* [ ] Progressive disclosure used appropriately
* [ ] Workflows have clear steps
### Code and scripts
* [ ] Scripts solve problems rather than punt to Claude
* [ ] Error handling is explicit and helpful
* [ ] No "voodoo constants" (all values justified)
* [ ] Required packages listed in instructions and verified as available
* [ ] Scripts have clear documentation
* [ ] No Windows-style paths (all forward slashes)
* [ ] Validation/verification steps for critical operations
* [ ] Feedback loops included for quality-critical tasks
### Testing
* [ ] At least three evaluations created
* [ ] Tested with Haiku, Sonnet, and Opus
* [ ] Tested with real usage scenarios
* [ ] Team feedback incorporated (if applicable)
## Next steps
Create your first Skill
Create and manage Skills in Claude Code
Upload and use Skills programmatically
---
# Overview
URL: http://www.claudeskills.org/docs/agent-skills/overview
Description: Understand Claude's Agent Skills architecture and benefits.
> Agent Skills are modular capabilities that extend Claude's functionality. Each Skill packages instructions, metadata, and optional resources (scripts, templates) that Claude uses automatically when relevant.
## Why use Skills
Skills are reusable, filesystem-based resources that provide Claude with domain-specific expertise: workflows, context, and best practices that transform general-purpose agents into specialists. Unlike prompts (conversation-level instructions for one-off tasks), Skills load on-demand and eliminate the need to repeatedly provide the same guidance across multiple conversations.
**Key benefits**:
* **Specialize Claude**: Tailor capabilities for domain-specific tasks
* **Reduce repetition**: Create once, use automatically
* **Compose capabilities**: Combine Skills to build complex workflows
For a deep dive into the architecture and real-world applications of Agent Skills, read our engineering blog: [Equipping agents for the real world with Agent Skills](https://www.anthropic.com/engineering/equipping-agents-for-the-real-world-with-agent-skills).
## Using Skills
Anthropic provides pre-built Agent Skills for common document tasks (PowerPoint, Excel, Word, PDF), and you can create your own custom Skills. Both work the same way. Claude automatically uses them when relevant to your request.
**Pre-built Agent Skills** are available to all users on claude.ai and via the Claude API. See the [Available Skills](#available-skills) section below for the complete list.
**Custom Skills** let you package domain expertise and organizational knowledge. They're available across Claude's products: create them in Claude Code, upload them via the API, or add them in claude.ai settings.
**Get started:**
* For pre-built Agent Skills: See the [quickstart tutorial](/docs/agent-skills/quickstart) to start using PowerPoint, Excel, Word, and PDF skills in the API
* For custom Skills: See the [Agent Skills Cookbook](https://github.com/anthropics/claude-cookbooks/tree/main/skills) to learn how to create your own Skills
## How Skills work
Skills leverage Claude's VM environment to provide capabilities beyond what's possible with prompts alone. Claude operates in a virtual machine with filesystem access, allowing Skills to exist as directories containing instructions, executable code, and reference materials, organized like an onboarding guide you'd create for a new team member.
This filesystem-based architecture enables **progressive disclosure**: Claude loads information in stages as needed, rather than consuming context upfront.
### Three types of Skill content, three levels of loading
Skills can contain three types of content, each loaded at different times:
### Level 1: Metadata (always loaded)
**Content type: Instructions**. The Skill's YAML frontmatter provides discovery information:
```yaml
---
name: PDF Processing
description: Extract text and tables from PDF files, fill forms, merge documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
---
```
Claude loads this metadata at startup and includes it in the system prompt. This lightweight approach means you can install many Skills without context penalty; Claude only knows each Skill exists and when to use it.
### Level 2: Instructions (loaded when triggered)
**Content type: Instructions**. The main body of SKILL.md contains procedural knowledge: workflows, best practices, and guidance:
````markdown
# PDF Processing
## Quick start
Use pdfplumber to extract text from PDFs:
```python
import pdfplumber
with pdfplumber.open("document.pdf") as pdf:
text = pdf.pages[0].extract_text()
```
For advanced form filling, see [FORMS.md](FORMS.md).
````
When you request something that matches a Skill's description, Claude reads SKILL.md from the filesystem via bash. Only then does this content enter the context window.
### Level 3: Resources and code (loaded as needed)
**Content types: Instructions, code, and resources**. Skills can bundle additional materials:
```
pdf-skill/
|-- SKILL.md (main instructions)
|-- FORMS.md (form-filling guide)
|-- REFERENCE.md (detailed API reference)
`-- scripts/
`-- fill_form.py (utility script)
```
**Instructions**: Additional markdown files (FORMS.md, REFERENCE.md) containing specialized guidance and workflows
**Code**: Executable scripts (fill\_form.py, validate.py) that Claude runs via bash; scripts provide deterministic operations without consuming context
**Resources**: Reference materials like database schemas, API documentation, templates, or examples
Claude accesses these files only when referenced. The filesystem model means each content type has different strengths: instructions for flexible guidance, code for reliability, resources for factual lookup.
| Level | When Loaded | Token Cost | Content |
| ------------------------- | ----------------------- | ---------------------- | --------------------------------------------------------------------- |
| **Level 1: Metadata** | Always (at startup) | \~100 tokens per Skill | `name` and `description` from YAML frontmatter |
| **Level 2: Instructions** | When Skill is triggered | Under 5k tokens | SKILL.md body with instructions and guidance |
| **Level 3+: Resources** | As needed | Effectively unlimited | Bundled files executed via bash without loading contents into context |
Progressive disclosure ensures only relevant content occupies the context window at any given time.
### The Skills architecture
Skills run in a code execution environment where Claude has filesystem access, bash commands, and code execution capabilities. Think of it like this: Skills exist as directories on a virtual machine, and Claude interacts with them using the same bash commands you'd use to navigate files on your computer.
**How Claude accesses Skill content:**
When a Skill is triggered, Claude uses bash to read SKILL.md from the filesystem, bringing its instructions into the context window. If those instructions reference other files (like FORMS.md or a database schema), Claude reads those files too using additional bash commands. When instructions mention executable scripts, Claude runs them via bash and receives only the output (the script code itself never enters context).
**What this architecture enables:**
**On-demand file access**: Claude reads only the files needed for each specific task. A Skill can include dozens of reference files, but if your task only needs the sales schema, Claude loads just that one file. The rest remain on the filesystem consuming zero tokens.
**Efficient script execution**: When Claude runs `validate_form.py`, the script's code never loads into the context window. Only the script's output (like "Validation passed" or specific error messages) consumes tokens. This makes scripts far more efficient than having Claude generate equivalent code on the fly.
**No practical limit on bundled content**: Because files don't consume context until accessed, Skills can include comprehensive API documentation, large datasets, extensive examples, or any reference materials you need. There's no context penalty for bundled content that isn't used.
This filesystem-based model is what makes progressive disclosure work. Claude navigates your Skill like you'd reference specific sections of an onboarding guide, accessing exactly what each task requires.
### Example: Loading a PDF processing skill
Here's how Claude loads and uses a PDF processing skill:
1. **Startup**: System prompt includes: `PDF Processing - Extract text and tables from PDF files, fill forms, merge documents`
2. **User request**: "Extract the text from this PDF and summarize it"
3. **Claude invokes**: `bash: read pdf-skill/SKILL.md` -> Instructions loaded into context
4. **Claude determines**: Form filling is not needed, so FORMS.md is not read
5. **Claude executes**: Uses instructions from SKILL.md to complete the task
The diagram shows:
1. Default state with system prompt and skill metadata pre-loaded
2. Claude triggers the skill by reading SKILL.md via bash
3. Claude optionally reads additional bundled files like FORMS.md as needed
4. Claude proceeds with the task
This dynamic loading ensures only relevant skill content occupies the context window.
## Where Skills work
Skills are available across Claude's agent products:
### Claude API
The Claude API supports both pre-built Agent Skills and custom Skills. Both work identically: specify the relevant `skill_id` in the `container` parameter along with the code execution tool.
**Prerequisites**: Using Skills via the API requires three beta headers:
* `code-execution-2025-08-25` - Skills run in the code execution container
* `skills-2025-10-02` - Enables Skills functionality
* `files-api-2025-04-14` - Required for uploading/downloading files to/from the container
Use pre-built Agent Skills by referencing their `skill_id` (e.g., `pptx`, `xlsx`), or create and upload your own via the Skills API (`/v1/skills` endpoints). Custom Skills are shared organization-wide.
To learn more, see [Use Skills with the Claude API](/en/api/skills-guide).
### Claude Code
[Claude Code](/en/docs/claude-code/overview) supports only Custom Skills.
**Custom Skills**: Create Skills as directories with SKILL.md files. Claude discovers and uses them automatically.
Custom Skills in Claude Code are filesystem-based and don't require API uploads.
To learn more, see [Use Skills in Claude Code](/en/docs/claude-code/skills).
### Claude.ai
[Claude.ai](https://claude.ai) supports both pre-built Agent Skills and custom Skills.
**Pre-built Agent Skills**: These Skills are already working behind the scenes when you create documents. Claude uses them without requiring any setup.
**Custom Skills**: Upload your own Skills as zip files through Settings > Features. Available on Pro, Max, Team, and Enterprise plans with code execution enabled. Custom Skills are individual to each user; they are not shared organization-wide and cannot be centrally managed by admins.
To learn more about using Skills in Claude.ai, see the following resources in the Claude Help Center:
* [What are Skills?](https://support.claude.com/en/articles/12512176-what-are-skills)
* [Using Skills in Claude](https://support.claude.com/en/articles/12512180-using-skills-in-claude)
* [How to create custom Skills](https://support.claude.com/en/articles/12512198-creating-custom-skills)
* [Tech Claude your way of working using Skills](https://support.claude.com/en/articles/12580051-teach-claude-your-way-of-working-using-skills)
## Skill structure
Every Skill requires a `SKILL.md` file with YAML frontmatter:
```yaml
---
name: Your Skill Name
description: Brief description of what this Skill does and when to use it
---
# Your Skill Name
## Instructions
[Clear, step-by-step guidance for Claude to follow]
## Examples
[Concrete examples of using this Skill]
```
**Required fields**: `name` and `description`
These are the only two fields supported in YAML frontmatter.
**Frontmatter limits**:
* `name`: 64 characters maximum
* `description`: 1024 characters maximum
The `description` should include both what the Skill does and when Claude should use it. For complete authoring guidance, see the [best practices guide](/docs/agent-skills/best-practices).
## Security considerations
We strongly recommend using Skills only from trusted sources: those you created yourself or obtained from Anthropic. Skills provide Claude with new capabilities through instructions and code, and while this makes them powerful, it also means a malicious Skill can direct Claude to invoke tools or execute code in ways that don't match the Skill's stated purpose.
If you must use a Skill from an untrusted or unknown source, exercise extreme caution and thoroughly audit it before use. Depending on what access Claude has when executing the Skill, malicious Skills could lead to data exfiltration, unauthorized system access, or other security risks.
**Key security considerations**:
* **Audit thoroughly**: Review all files bundled in the Skill: SKILL.md, scripts, images, and other resources. Look for unusual patterns like unexpected network calls, file access patterns, or operations that don't match the Skill's stated purpose
* **External sources are risky**: Skills that fetch data from external URLs pose particular risk, as fetched content may contain malicious instructions. Even trustworthy Skills can be compromised if their external dependencies change over time
* **Tool misuse**: Malicious Skills can invoke tools (file operations, bash commands, code execution) in harmful ways
* **Data exposure**: Skills with access to sensitive data could be designed to leak information to external systems
* **Treat like installing software**: Only use Skills from trusted sources. Be especially careful when integrating Skills into production systems with access to sensitive data or critical operations
## Available Skills
### Pre-built Agent Skills
The following pre-built Agent Skills are available for immediate use:
* **PowerPoint (pptx)**: Create presentations, edit slides, analyze presentation content
* **Excel (xlsx)**: Create spreadsheets, analyze data, generate reports with charts
* **Word (docx)**: Create documents, edit content, format text
* **PDF (pdf)**: Generate formatted PDF documents and reports
These Skills are available on the Claude API and claude.ai. See the [quickstart tutorial](/docs/agent-skills/quickstart) to start using them in the API.
### Custom Skills examples
For complete examples of custom Skills, see the [Skills cookbook](https://github.com/anthropics/claude-cookbooks/tree/main/skills).
## Limitations and constraints
Understanding these limitations helps you plan your Skills deployment effectively.
### Cross-surface availability
**Custom Skills do not sync across surfaces**. Skills uploaded to one surface are not automatically available on others:
* Skills uploaded to Claude.ai must be separately uploaded to the API
* Skills uploaded via the API are not available on Claude.ai
* Claude Code Skills are filesystem-based and separate from both Claude.ai and API
You'll need to manage and upload Skills separately for each surface where you want to use them.
### Sharing scope
Skills have different sharing models depending on where you use them:
* **Claude.ai**: Individual user only; each team member must upload separately
* **Claude API**: Workspace-wide; all workspace members can access uploaded Skills
* **Claude Code**: Personal (`~/.claude/skills/`) or project-based (`.claude/skills/`)
Claude.ai does not currently support centralized admin management or org-wide distribution of custom Skills.
### Runtime environment constraints
Skills run in the code execution container with these limitations:
* **No network access**: Skills cannot make external API calls or access the internet
* **No runtime package installation**: Only pre-installed packages are available. You cannot install new packages during execution.
* **Pre-configured dependencies only**: Check the [code execution tool documentation](/en/docs/agents-and-tools/tool-use/code-execution-tool) for the list of available packages
Plan your Skills to work within these constraints.
## Next steps
Create your first Skill
Use Skills with the Claude API
Create and manage custom Skills in Claude Code
Write Skills that Claude can use effectively
---
# Quickstart
URL: http://www.claudeskills.org/docs/agent-skills/quickstart
Description: Create documents with Claude Agent Skills using the API.
> Learn how to use Agent Skills to create documents with the Claude API in under 10 minutes.
This tutorial shows you how to use Agent Skills to create a PowerPoint presentation. You'll learn how to enable Skills, make a simple request, and access the generated file.
## Prerequisites
* [Anthropic API key](https://console.anthropic.com/settings/keys)
* Python 3.7+ or curl installed
* Basic familiarity with making API requests
## What are Agent Skills?
Pre-built Agent Skills extend Claude's capabilities with specialized expertise for tasks like creating documents, analyzing data, and processing files. Anthropic provides the following pre-built Agent Skills in the API:
* **PowerPoint (pptx)**: Create and edit presentations
* **Excel (xlsx)**: Create and analyze spreadsheets
* **Word (docx)**: Create and edit documents
* **PDF (pdf)**: Generate PDF documents
**Want to create custom Skills?** See the [Agent Skills Cookbook](https://github.com/anthropics/claude-cookbooks/tree/main/skills) for examples of building your own Skills with domain-specific expertise.
## Step 1: List available Skills
First, let's see what Skills are available. We'll use the Skills API to list all Anthropic-managed Skills:
```python
import anthropic
client = anthropic.Anthropic()
# List Anthropic-managed Skills
skills = client.beta.skills.list(
source="anthropic",
betas=["skills-2025-10-02"]
)
for skill in skills.data:
print(f"{skill.id}: {skill.display_title}")
```
```typescript
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic();
// List Anthropic-managed Skills
const skills = await client.beta.skills.list({
source: 'anthropic',
betas: ['skills-2025-10-02']
});
for (const skill of skills.data) {
console.log(`${skill.id}: ${skill.display_title}`);
}
```
```bash
curl "https://api.anthropic.com/v1/skills?source=anthropic" \
-H "x-api-key: $ANTHROPIC_API_KEY" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: skills-2025-10-02"
```
You see the following Skills: `pptx`, `xlsx`, `docx`, and `pdf`.
This API returns each Skill's metadata: its name and description. Claude loads this metadata at startup to know what Skills are available. This is the first level of **progressive disclosure**, where Claude discovers Skills without loading their full instructions yet.
## Step 2: Create a presentation
Now we'll use the PowerPoint Skill to create a presentation about renewable energy. We specify Skills using the `container` parameter in the Messages API:
```python
import anthropic
client = anthropic.Anthropic()
# Create a message with the PowerPoint Skill
response = client.beta.messages.create(
model="claude-sonnet-4-5-20250929",
max_tokens=4096,
betas=["code-execution-2025-08-25", "skills-2025-10-02"],
container={
"skills": [
{
"type": "anthropic",
"skill_id": "pptx",
"version": "latest"
}
]
},
messages=[{
"role": "user",
"content": "Create a presentation about renewable energy with 5 slides"
}],
tools=[{
"type": "code_execution_20250825",
"name": "code_execution"
}]
)
print(response.content)
```
```typescript
import Anthropic from '@anthropic-ai/sdk';
const client = new Anthropic();
// Create a message with the PowerPoint Skill
const response = await client.beta.messages.create({
model: 'claude-sonnet-4-5-20250929',
max_tokens: 4096,
betas: ['code-execution-2025-08-25', 'skills-2025-10-02'],
container: {
skills: [
{
type: 'anthropic',
skill_id: 'pptx',
version: 'latest'
}
]
},
messages: [{
role: 'user',
content: 'Create a presentation about renewable energy with 5 slides'
}],
tools: [{
type: 'code_execution_20250825',
name: 'code_execution'
}]
});
console.log(response.content);
```
```bash
curl https://api.anthropic.com/v1/messages \
-H "x-api-key: $ANTHROPIC_API_KEY" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: code-execution-2025-08-25,skills-2025-10-02" \
-H "content-type: application/json" \
-d '{
"model": "claude-sonnet-4-5-20250929",
"max_tokens": 4096,
"container": {
"skills": [
{
"type": "anthropic",
"skill_id": "pptx",
"version": "latest"
}
]
},
"messages": [{
"role": "user",
"content": "Create a presentation about renewable energy with 5 slides"
}],
"tools": [{
"type": "code_execution_20250825",
"name": "code_execution"
}]
}'
```
Let's break down what each part does:
* **`container.skills`**: Specifies which Skills Claude can use
* **`type: "anthropic"`**: Indicates this is an Anthropic-managed Skill
* **`skill_id: "pptx"`**: The PowerPoint Skill identifier
* **`version: "latest"`**: The Skill version set to the most recently published
* **`tools`**: Enables code execution (required for Skills)
* **Beta headers**: `code-execution-2025-08-25` and `skills-2025-10-02`
When you make this request, Claude automatically matches your task to the relevant Skill. Since you asked for a presentation, Claude determines the PowerPoint Skill is relevant and loads its full instructions: the second level of progressive disclosure. Then Claude executes the Skill's code to create your presentation.
## Step 3: Download the created file
The presentation was created in the code execution container and saved as a file. The response includes a file reference with a file ID. Extract the file ID and download it using the Files API:
```python
# Extract file ID from response
file_id = None
for block in response.content:
if block.type == 'tool_use' and block.name == 'code_execution':
# File ID is in the tool result
for result_block in block.content:
if hasattr(result_block, 'file_id'):
file_id = result_block.file_id
break
if file_id:
# Download the file
file_content = client.beta.files.download(
file_id=file_id,
betas=["files-api-2025-04-14"]
)
# Save to disk
with open("renewable_energy.pptx", "wb") as f:
file_content.write_to_file(f.name)
print(f"Presentation saved to renewable_energy.pptx")
```
```typescript
// Extract file ID from response
let fileId: string | null = null;
for (const block of response.content) {
if (block.type === 'tool_use' && block.name === 'code_execution') {
// File ID is in the tool result
for (const resultBlock of block.content) {
if ('file_id' in resultBlock) {
fileId = resultBlock.file_id;
break;
}
}
}
}
if (fileId) {
// Download the file
const fileContent = await client.beta.files.download(fileId, {
betas: ['files-api-2025-04-14']
});
// Save to disk
const fs = require('fs');
fs.writeFileSync('renewable_energy.pptx', Buffer.from(await fileContent.arrayBuffer()));
console.log('Presentation saved to renewable_energy.pptx');
}
```
```bash
# Extract file_id from response (using jq)
FILE_ID=$(echo "$RESPONSE" | jq -r '.content[] | select(.type=="tool_use" and .name=="code_execution") | .content[] | select(.file_id) | .file_id')
# Download the file
curl "https://api.anthropic.com/v1/files/$FILE_ID/content" \
-H "x-api-key: $ANTHROPIC_API_KEY" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: files-api-2025-04-14" \
--output renewable_energy.pptx
echo "Presentation saved to renewable_energy.pptx"
```
For complete details on working with generated files, see the [code execution tool documentation](/en/docs/agents-and-tools/tool-use/code-execution-tool#retrieve-generated-files).
## Try more examples
Now that you've created your first document with Skills, try these variations:
### Create a spreadsheet
```python
response = client.beta.messages.create(
model="claude-sonnet-4-5-20250929",
max_tokens=4096,
betas=["code-execution-2025-08-25", "skills-2025-10-02"],
container={
"skills": [
{
"type": "anthropic",
"skill_id": "xlsx",
"version": "latest"
}
]
},
messages=[{
"role": "user",
"content": "Create a quarterly sales tracking spreadsheet with sample data"
}],
tools=[{
"type": "code_execution_20250825",
"name": "code_execution"
}]
)
```
```typescript
const response = await client.beta.messages.create({
model: 'claude-sonnet-4-5-20250929',
max_tokens: 4096,
betas: ['code-execution-2025-08-25', 'skills-2025-10-02'],
container: {
skills: [
{
type: 'anthropic',
skill_id: 'xlsx',
version: 'latest'
}
]
},
messages: [{
role: 'user',
content: 'Create a quarterly sales tracking spreadsheet with sample data'
}],
tools: [{
type: 'code_execution_20250825',
name: 'code_execution'
}]
});
```
```bash
curl https://api.anthropic.com/v1/messages \
-H "x-api-key: $ANTHROPIC_API_KEY" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: code-execution-2025-08-25,skills-2025-10-02" \
-H "content-type: application/json" \
-d '{
"model": "claude-sonnet-4-5-20250929",
"max_tokens": 4096,
"container": {
"skills": [
{
"type": "anthropic",
"skill_id": "xlsx",
"version": "latest"
}
]
},
"messages": [{
"role": "user",
"content": "Create a quarterly sales tracking spreadsheet with sample data"
}],
"tools": [{
"type": "code_execution_20250825",
"name": "code_execution"
}]
}'
```
### Create a Word document
```python
response = client.beta.messages.create(
model="claude-sonnet-4-5-20250929",
max_tokens=4096,
betas=["code-execution-2025-08-25", "skills-2025-10-02"],
container={
"skills": [
{
"type": "anthropic",
"skill_id": "docx",
"version": "latest"
}
]
},
messages=[{
"role": "user",
"content": "Write a 2-page report on the benefits of renewable energy"
}],
tools=[{
"type": "code_execution_20250825",
"name": "code_execution"
}]
)
```
```typescript
const response = await client.beta.messages.create({
model: 'claude-sonnet-4-5-20250929',
max_tokens: 4096,
betas: ['code-execution-2025-08-25', 'skills-2025-10-02'],
container: {
skills: [
{
type: 'anthropic',
skill_id: 'docx',
version: 'latest'
}
]
},
messages: [{
role: 'user',
content: 'Write a 2-page report on the benefits of renewable energy'
}],
tools: [{
type: 'code_execution_20250825',
name: 'code_execution'
}]
});
```
```bash
curl https://api.anthropic.com/v1/messages \
-H "x-api-key: $ANTHROPIC_API_KEY" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: code-execution-2025-08-25,skills-2025-10-02" \
-H "content-type: application/json" \
-d '{
"model": "claude-sonnet-4-5-20250929",
"max_tokens": 4096,
"container": {
"skills": [
{
"type": "anthropic",
"skill_id": "docx",
"version": "latest"
}
]
},
"messages": [{
"role": "user",
"content": "Write a 2-page report on the benefits of renewable energy"
}],
"tools": [{
"type": "code_execution_20250825",
"name": "code_execution"
}]
}'
```
### Generate a PDF
```python
response = client.beta.messages.create(
model="claude-sonnet-4-5-20250929",
max_tokens=4096,
betas=["code-execution-2025-08-25", "skills-2025-10-02"],
container={
"skills": [
{
"type": "anthropic",
"skill_id": "pdf",
"version": "latest"
}
]
},
messages=[{
"role": "user",
"content": "Generate a PDF invoice template"
}],
tools=[{
"type": "code_execution_20250825",
"name": "code_execution"
}]
)
```
```typescript
const response = await client.beta.messages.create({
model: 'claude-sonnet-4-5-20250929',
max_tokens: 4096,
betas: ['code-execution-2025-08-25', 'skills-2025-10-02'],
container: {
skills: [
{
type: 'anthropic',
skill_id: 'pdf',
version: 'latest'
}
]
},
messages: [{
role: 'user',
content: 'Generate a PDF invoice template'
}],
tools: [{
type: 'code_execution_20250825',
name: 'code_execution'
}]
});
```
```bash
curl https://api.anthropic.com/v1/messages \
-H "x-api-key: $ANTHROPIC_API_KEY" \
-H "anthropic-version: 2023-06-01" \
-H "anthropic-beta: code-execution-2025-08-25,skills-2025-10-02" \
-H "content-type: application/json" \
-d '{
"model": "claude-sonnet-4-5-20250929",
"max_tokens": 4096,
"container": {
"skills": [
{
"type": "anthropic",
"skill_id": "pdf",
"version": "latest"
}
]
},
"messages": [{
"role": "user",
"content": "Generate a PDF invoice template"
}],
"tools": [{
"type": "code_execution_20250825",
"name": "code_execution"
}]
}'
```
## Next steps
Now that you've used pre-built Agent Skills, you can:
Use Skills with the Claude API
Upload your own Skills for specialized tasks
Learn best practices for writing effective Skills
Learn about Skills in Claude Code
Explore example Skills and implementation patterns
---
# Comparisons
URL: http://www.claudeskills.org/docs/comparisons
Description: How is Fumadocs different from other existing frameworks?
## Nextra
Fumadocs is highly inspired by Nextra. For example, the Routing Conventions. That is why
`meta.json` also exists in Fumadocs.
Nextra is more opinionated than Fumadocs. Fumadocs is accelerated by App Router. As a result, It provides many server-side functions, and you have to
configure things manually compared to simply editing a configuration file.
Fumadocs works great if you want more control over everything, such as
adding it to an existing codebase or implementing advanced routing.
### Feature Table
| Feature | Fumadocs | Nextra |
| ------------------- | ------------ | ------------------------- |
| Static Generation | Yes | Yes |
| Cached | Yes | Yes |
| Light/Dark Mode | Yes | Yes |
| Syntax Highlighting | Yes | Yes |
| Table of Contents | Yes | Yes |
| Full-text Search | Yes | Yes |
| i18n | Yes | Yes |
| Last Git Edit Time | Yes | Yes |
| Page Icons | Yes | Yes, via `_meta.js` files |
| RSC | Yes | Yes |
| Remote Source | Yes | Yes |
| SEO | Via Metadata | Yes |
| Built-in Components | Yes | Yes |
| RTL Layout | Yes | Yes |
### Additional Features
Features supported via 3rd party libraries like [TypeDoc](https://typedoc.org) will not be listed here.
| Feature | Fumadocs | Nextra |
| -------------------------- | -------- | ------ |
| OpenAPI Integration | Yes | No |
| TypeScript Docs Generation | Yes | No |
| TypeScript Twoslash | Yes | Yes |
## Mintlify
Mintlify is a documentation service, as compared to Fumadocs, it offers a free tier but isn't completely free and open source.
Fumadocs is not as powerful as Mintlify, for example, the OpenAPI integration of Mintlify.
As the creator of Fumadocs, I wouldn't recommend switching to Fumadocs from Mintlify if you're satisfied with the current way you build docs.
However, I believe Fumadocs is a suitable tool for all Next.js developers who want to have elegant docs.
## Docusaurus
Docusaurus is a powerful framework based on React.js. It offers many cool
features with plugins and custom themes.
### Better DX
Since Fumadocs is built on the top of Next.js, you'll have to start the Next.js dev
server every time to review changes, and initial boilerplate code is relatively more
compared to Docusaurus.
For a simple docs, Docusaurus might be a better choice if you don't need any Next.js specific functionality.
However, when you want to use Next.js, or seek extra customizability like tuning default UI components, Fumadocs could be a better choice.
### Plugins
You can easily achieve many things with plugins, their ecosystem is indeed larger and maintained by many contributors.
In comparison, the flexibility of Fumadocs allows you to implement them on your own, it may take longer to tune it to your satisfaction.
---
# Components
URL: http://www.claudeskills.org/docs/components
Description: Additional components to improve your docs
---
# Accordion
URL: http://www.claudeskills.org/docs/components/accordion
Description: Add Accordions to your documentation
## Usage
Based on
[Radix UI Accordion](https://www.radix-ui.com/primitives/docs/components/accordion), useful for FAQ sections.
```tsx
import React from 'react';
import { Accordion, Accordions } from 'fumadocs-ui/components/accordion';
My Content;
```
### Accordions
{/* */}
### Accordion
{/* */}
### Linking to Accordion
You can specify an `id` for accordion. The accordion will automatically open when the user is navigating to the page with the specified `id` in hash parameter.
```mdx
My Content
```
> The value of accordion is same as title by default. When an id presents, it will be used as the value instead.
---
# Banner
URL: http://www.claudeskills.org/docs/components/banner
Description: Add a banner to your site
## Usage
Put the element at the top of your root layout, you can use it for displaying announcements.
```tsx
import { Banner } from 'fumadocs-ui/components/banner';
export default function RootLayout({
children,
}: {
children: React.ReactNode;
}): React.ReactElement {
return (
Hello World
{children}
);
}
```
### Variant
Change the default variant.
```tsx
import { Banner } from 'fumadocs-ui/components/banner';
Hello World;
```
### Change Layout
By default, the banner uses a `style` tag to modify Fumadocs layouts (e.g. reduce the sidebar height).
You can disable it with:
```tsx
import { Banner } from 'fumadocs-ui/components/banner';
Hello World;
```
### Close
To allow users to close the banner, give the banner an ID.
```tsx
import { Banner } from 'fumadocs-ui/components/banner';
Hello World;
```
The state will be automatically persisted.
---
# Code Block (Dynamic)
URL: http://www.claudeskills.org/docs/components/dynamic-codeblock
Description: A codeblock that also highlights code
## Usage
```tsx
import { DynamicCodeBlock } from 'fumadocs-ui/components/dynamic-codeblock';
;
```
This component, different from the MDX [`CodeBlock`](/docs/mdx/codeblock) component, can be used without MDX.
It highlights the code with Shiki and use the default component to render it.
Features:
- Can be pre-rendered on server
- load languages and themes on browser lazily
### Options
```tsx
import { DynamicCodeBlock } from 'fumadocs-ui/components/dynamic-codeblock';
;
```
---
# Files
URL: http://www.claudeskills.org/docs/components/files
Description: Display file structure in your documentation
## Usage
Wrap file components in `Files`.
```mdx
import { File, Folder, Files } from 'fumadocs-ui/components/files';
```
### File
{/* */}
### Folder
{/* */}
---
# GitHub Info
URL: http://www.claudeskills.org/docs/components/github-info
Description: Display your GitHub repository information
## Usage
```tsx
import { GithubInfo } from 'fumadocs-ui/components/github-info';
;
```
It's recommended to add it to your docs layout with `links` option:
```tsx title="app/docs/layout.tsx"
import { DocsLayout, type DocsLayoutProps } from 'fumadocs-ui/layouts/notebook';
import type { ReactNode } from 'react';
import { baseOptions } from '@/app/layout.config';
import { source } from '@/lib/source';
import { GithubInfo } from 'fumadocs-ui/components/github-info';
const docsOptions: DocsLayoutProps = {
...baseOptions,
tree: source.pageTree,
links: [
{
type: 'custom',
children: (
),
},
],
};
export default function Layout({ children }: { children: ReactNode }) {
return {children};
}
```
---
# Zoomable Image
URL: http://www.claudeskills.org/docs/components/image-zoom
Description: Allow zoom-in images in your documentation
## Usage
Replace `img` with `ImageZoom` in your MDX components.
```tsx title="app/docs/[[...slug]]/page.tsx"
import { ImageZoom } from 'fumadocs-ui/components/image-zoom';
import defaultMdxComponents from 'fumadocs-ui/mdx';
return (
,
// other Mdx components
}}
/>
);
```
Now image zoom will be automatically enabled on all images.
```mdx

```
### Image Optimization
A default [`sizes` property](https://nextjs.org/docs/app/api-reference/components/image#sizes) will be defined for Next.js `` component if not specified.
---
# Inline TOC
URL: http://www.claudeskills.org/docs/components/inline-toc
Description: Add Inline TOC into your documentation
## Usage
Pass TOC items to the component.
```mdx
import { InlineTOC } from 'fumadocs-ui/components/inline-toc';
```
### Use in Pages
You can add inline TOC into every page.
```tsx
...
...
```
## Reference
{/* */}
---
# Root Toggle
URL: http://www.claudeskills.org/docs/components/root-toggle
Description: Switch between page trees
## Usages
Add this component to your sidebar or other places you want.
```tsx
import { DocsLayout } from 'fumadocs-ui/layouts/docs';
import { RootToggle } from 'fumadocs-ui/components/layout/root-toggle';
),
}}
/>;
```
---
# Steps
URL: http://www.claudeskills.org/docs/components/steps
Description: Adding steps to your docs
## Usage
Put your steps into the `Steps` container.
```mdx
import { Step, Steps } from 'fumadocs-ui/components/steps';
### Hello World
### Hello World
```
> We recommend using Tailwind CSS utility classes directly on Tailwind CSS projects.
### Without imports
You can use the Tailwind CSS utilities without importing it.
```mdx
```
It supports adding step styles to only headings with arbitrary variants.
```mdx
### Hello World
```
### Hello World
You no longer need to use the step component anymore.
---
# Tabs
URL: http://www.claudeskills.org/docs/components/tabs
## Usage
Import it in your MDX documents.
```mdx
import { Tab, Tabs } from 'fumadocs-ui/components/tabs';
Javascript is weirdRust is fast
```
### Without `value`
Without a `value`, it detects from the children index. Note that it might cause errors on re-renders, it's not encouraged if the tabs might change.
```mdx
import { Tab, Tabs } from 'fumadocs-ui/components/tabs';
Javascript is weirdRust is fast
```
#### Demo with Re-renders
Javascript is weirdRust is fast
{/* */}
### Shared Value
By passing an `groupId` property, you can share a value across all tabs with the same
id.
```mdx
Javascript is weirdRust is fast
```
### Persistent
You can enable persistent by passing a `persist` property. The value will be
stored in `localStorage`, with its id as the key.
```mdx
Javascript is weirdRust is fast
```
> Persistent only works if you have passed an `id`.
### Default Value
Set a default value by passing `defaultIndex`.
```mdx
Javascript is weirdRust is fast
```
### Link to Tab
Use HTML `id` attribute to link to a specific tab.
```mdx
Javascript is weirdRust is fast
`Hello World`
```
You can add the hash `#tab-cpp` to your URL and reload, the C++ tab will be activated.
Javascript is weirdRust is fast
`Hello World`
Additionally, the `updateAnchor` property can be set to `true` in the `Tabs` component
to automatically update the URL hash whenever time a new tab is selected:
```mdx
Javascript is weird
Rust is fast
`Hello World`
```
{/* */}
Hello!
World!
### Advanced
You can use the styled Radix UI primitive directly from exported `Primitive`.
```mdx
import { Primitive } from 'fumadocs-ui/components/tabs';
```
---
# Type Table
URL: http://www.claudeskills.org/docs/components/type-table
Description: A table for documenting types
## Usage
It accepts a `type` property.
```mdx
import { TypeTable } from 'fumadocs-ui/components/type-table';
```
## References
### Type Table
{/* */}
### Object Type
{/* */}
---
# Overview
URL: http://www.claudeskills.org/docs/customisation
Description: An overview of Fumadocs UI
## Architecture
### Page Tree
Navigation elements like sidebar take a [Page Tree](/docs/headless/page-tree) to render navigation links, it's a tree that describes all available pages and folders.
Normally, it is generated from your file structure using [`loader()`](/docs/headless/source-api), you can learn [how to organize pages](/docs/page-conventions).
## Customisation
### Layouts
You can use the exposed options of different layouts:
Layout for docs
Layout for docs content
A more compact version of Docs Layout
Layout for other pages
### Components
Fumadocs UI also offers styled components for interactive examples to enhance your docs, you can customise them with exposed props like `style` and `className`.
See [Components](/docs/components).
### Design System
Since the design system is built on Tailwind CSS, you can customise it [with CSS Variables](/docs/theme#colors).
### CLI
If none of them suits you, Fumadocs CLI is a tool to install Fumadocs UI components and layouts to your codebase, similar to Shadcn UI. Allowing you to fully customise Fumadocs UI:
```mdx
npx fumadocs add
```
---
# Internationalization
URL: http://www.claudeskills.org/docs/internationalization
Description: Support multiple languages in your documentation
Fumadocs is not a full-powered i18n library, it manages only its own components and utilities.
You can use other libraries like [next-intl](https://github.com/amannn/next-intl) for the rest of your app.
Read the [Next.js Docs](https://nextjs.org/docs/app/building-your-application/routing/internationalization) to learn more about implementing I18n in Next.js.
## Manual Setup
Define the i18n configurations in a file, we will import it with `@/ilb/i18n` in this guide.
{/*
../../examples/i18n/lib/i18n.ts
*/}
Pass it to the source loader.
```ts title="lib/source.ts"
import { i18n } from '@/lib/i18n';
import { loader } from 'fumadocs-core/source';
export const source = loader({
i18n, // [!code highlight]
// other options
});
```
And update Fumadocs UI layout options.
```tsx title="app/layout.config.tsx"
import { i18n } from '@/lib/i18n';
import type { BaseLayoutProps } from 'fumadocs-ui/layouts/shared';
export function baseOptions(locale: string): BaseLayoutProps {
return {
i18n,
// different props based on `locale`
};
}
```
### Middleware
Create a middleware that redirects users to appropriate locale.
```json doc-gen:file
{
"file": "../../examples/i18n/middleware.ts",
"codeblock": {
"lang": "ts",
"meta": "title=\"middleware.ts\""
}
}
```
See [Middleware](/docs/headless/internationalization#middleware) for customisable options.
> Note that this is optional, you can also use your own middleware or the one provided by i18n libraries.
### Routing
Create a `/app/[lang]` folder, and move all files (e.g. `page.tsx`, `layout.tsx`) from `/app` to the folder.
Wrap the root provider inside `I18nProvider`, and provide available languages & translations to it.
Note that only English translations are provided by default.
```tsx title="app/[lang]/layout.tsx"
import { RootProvider } from 'fumadocs-ui/provider';
import { I18nProvider, type Translations } from 'fumadocs-ui/i18n';
const cn: Partial = {
search: 'Translated Content',
// other translations
};
// available languages that will be displayed on UI
// make sure `locale` is consistent with your i18n config
const locales = [
{
name: 'English',
locale: 'en',
},
{
name: 'Chinese',
locale: 'cn',
},
];
export default async function RootLayout({
params,
children,
}: {
params: Promise<{ lang: string }>;
children: React.ReactNode;
}) {
const lang = (await params).lang;
return (
{children}
);
}
```
### Pass Locale
Pass the locale to Fumadocs in your pages and layouts.
{/* ```tsx title="/app/[lang]/(home)/layout.tsx" tab="Home Layout"
import type { ReactNode } from 'react';
import { HomeLayout } from 'fumadocs-ui/layouts/home';
import { baseOptions } from '@/app/layout.config';
export default async function Layout({
params,
children,
}: {
params: Promise<{ lang: string }>;
children: ReactNode;
}) {
const { lang } = await params;
return {children};
}
```
```tsx title="/app/[lang]/docs/layout.tsx" tab="Docs Layout"
import type { ReactNode } from 'react';
import { source } from '@/lib/source';
import { DocsLayout } from 'fumadocs-ui/layouts/docs';
import { baseOptions } from '@/app/layout.config';
export default async function Layout({
params,
children,
}: {
params: Promise<{ lang: string }>;
children: ReactNode;
}) {
const { lang } = await params;
return (
{children}
);
}
```
```ts title="page.tsx" tab="Docs Page"
import { source } from '@/lib/source';
export default async function Page({
params,
}: {
params: Promise<{ lang: string; slug?: string[] }>;
}) {
const { slug, lang } = await params;
// get page
source.getPage(slug); // [!code --]
source.getPage(slug, lang); // [!code ++]
// get pages
source.getPages(); // [!code --]
source.getPages(lang); // [!code ++]
}
``` */}
### Search
Configure i18n on your search solution.
- **Built-in Search (Orama):**
For [Supported Languages](https://docs.orama.com/docs/orama-js/supported-languages), no further changes are needed.
Otherwise, additional config is required (e.g. Chinese & Japanese). See [Special Languages](/docs/headless/search/orama#special-languages).
- **Cloud Solutions (e.g. Algolia):**
They usually have official support for multilingual.
## Writing Documents
{/* ../../shared/page-conventions.i18n.mdx */}
## Navigation
Fumadocs only handles navigation for its own layouts (e.g. sidebar).
For other places, you can use the `useParams` hook to get the locale from url, and attend it to `href`.
```tsx
import Link from 'next/link';
import { useParams } from 'next/navigation';
const { lang } = useParams();
return This is a link;
```
In addition, the [`fumadocs-core/dynamic-link`](/docs/headless/components/link#dynamic-hrefs) component supports dynamic hrefs, you can use it to attend the locale prefix.
It is useful for Markdown/MDX content.
```mdx title="content.mdx"
import { DynamicLink } from 'fumadocs-core/dynamic-link';
This is a link
```
---
# Docs Layout
URL: http://www.claudeskills.org/docs/layouts/docs
Description: The layout of documentation
The layout of documentation pages, it includes a sidebar and mobile-only navbar.
> It is a server component, you should not reference it in a client component.
## Usage
Pass your page tree to the component.
```tsx title="layout.tsx"
import { DocsLayout } from 'fumadocs-ui/layouts/docs';
import { baseOptions } from '@/app/layout.config';
import type { ReactNode } from 'react';
export default function Layout({ children }: { children: ReactNode }) {
return (
{children}
);
}
```
{/* */}
## Sidebar
```tsx title="layout.tsx"
import { DocsLayout } from 'fumadocs-ui/layouts/docs';
;
```
{/* */}
### Sidebar Tabs
See [Navigation Guide](/docs/navigation/sidebar#sidebar-tabs) for usages.
#### Decoration
Change the icon/styles of tabs.
```tsx
import { DocsLayout } from 'fumadocs-ui/layouts/docs';
({
...option,
icon: 'my icon',
}),
},
}}
/>;
```
## Nav
A mobile-only navbar, we recommend to customise it from `baseOptions`.
```tsx
import type { BaseLayoutProps } from 'fumadocs-ui/layouts/shared';
export const baseOptions: BaseLayoutProps = {
githubUrl: 'https://github.com/fuma-nama/fumadocs',
nav: {
title: 'My App',
},
};
```
{/* */}
### Transparent Mode
To make the navbar background transparent, you can configure transparent mode.
```tsx
import type { BaseLayoutProps } from 'fumadocs-ui/layouts/shared';
export const baseOptions: BaseLayoutProps = {
nav: {
transparentMode: 'top',
},
};
```
| Mode | Description |
| -------- | ---------------------------------------- |
| `always` | Always use a transparent background |
| `top` | When at the top of page |
| `none` | Disable transparent background (default) |
### Replace Navbar
To replace the navbar in Docs Layout, set `nav.component` to your own component.
```tsx title="layout.tsx"
import { baseOptions } from '@/app/layout.config';
import { DocsLayout } from 'fumadocs-ui/layouts/notebook';
import type { ReactNode } from 'react';
export default function Layout({ children }: { children: ReactNode }) {
return (
,
}}
>
{children}
);
}
```
Fumadocs uses **CSS Variables** to share the size of layout components, and fit each layout component into appropriate position.
You need to override `--fd-nav-height` to the exact height of your custom navbar, this can be done with a CSS stylesheet (e.g. in `global.css`):
```css
:root {
--fd-nav-height: 80px !important;
}
```
## Advanced
### Disable Prefetching
By default, it uses the Next.js Link component with prefetch enabled.
When the link component appears into the browser viewport, the content (RSC payload) will be prefetched.
On Vercel, this may cause a high usage of serverless functions and Data Cache.
It can also hit the limits of some other hosting platforms.
You can disable prefetching to reduce the amount of RSC requests.
```tsx
import { DocsLayout } from 'fumadocs-ui/layouts/docs';
;
```
---
# Home Layout
URL: http://www.claudeskills.org/docs/layouts/home-layout
Description: Shared layout for other pages
## Usage
Add a navbar and search dialog across other pages.
```tsx title="/app/(home)/layout.tsx"
import { HomeLayout } from 'fumadocs-ui/layouts/home';
import { baseOptions } from '@/app/layout.config';
import type { ReactNode } from 'react';
export default function Layout({ children }: { children: ReactNode }) {
return {children};
}
```
Create a [Route Group](https://nextjs.org/docs/app/building-your-application/routing/route-groups) to share the same layout across multiple pages.
---
# Notebook
URL: http://www.claudeskills.org/docs/layouts/notebook
Description: A more compact version of Docs Layout
## Usage
Enable the notebook layout with `fumadocs-ui/layouts/notebook`, it's a more compact layout than the default one.
```tsx title="layout.tsx"
import { DocsLayout } from 'fumadocs-ui/layouts/notebook';
import { baseOptions } from '@/app/layout.config';
import { source } from '@/lib/source';
import type { ReactNode } from 'react';
export default function Layout({ children }: { children: ReactNode }) {
return (
{children}
);
}
```
---
# Docs Page
URL: http://www.claudeskills.org/docs/layouts/page
Description: A page in your documentation
Page is the base element of a documentation, it includes Table of contents,
Footer, and Breadcrumb.
## Usage
```tsx title="page.tsx"
import {
DocsPage,
DocsDescription,
DocsTitle,
DocsBody,
} from 'fumadocs-ui/page';
titledescription...;
```
Instead of rendering the title with `DocsTitle` in `page.tsx`, you can put the title into MDX file.
This will render the title in the MDX body.
### Body
It applies the [Typography](/docs/theme#typography) styles, wrap your content inside.
```tsx
import { DocsBody } from 'fumadocs-ui/page';
This heading looks good!
;
```
### Category
Optional, link the other pages in its (page tree) folder with cards.
> You can use this component without ``.
```tsx title="page.tsx"
import { source } from '@/lib/source';
import { DocsCategory } from 'fumadocs-ui/page';
const page = source.getPage(['...']);
;
```
**Demo:**
{/* DocsCategory is not supported */}
{/* */}
## Configurations
### Full Mode
To extend the page to fill up all available space, pass `full` to the page component.
This will force TOC to be shown as a popover.
```tsx
import { DocsPage } from 'fumadocs-ui/page';
...;
```
### Table of Contents
An overview of all the headings in your article, it requires an array of headings.
For Markdown and MDX documents, You can obtain it using the
[TOC Utility](/docs/headless/utils/get-toc). Content sources like Fumadocs MDX offer this out-of-the-box.
```tsx
import { DocsPage } from 'fumadocs-ui/page';
...;
```
Customise or disable TOC from your documentation with the `tableOfContent` option.
```tsx
import { DocsPage } from 'fumadocs-ui/page';
...;
```
{/* */}
#### Style
You can choose another style for TOC, like `clerk` inspired by https://clerk.com:
```tsx
import { DocsPage } from 'fumadocs-ui/page';
...
;
```
#### Popover Mode
On smaller devices, it is shown on a popover instead.
Customise it with the `tableOfContentPopover` option.
```tsx
import { DocsPage } from 'fumadocs-ui/page';
...;
```
{/* */}
### Last Updated Time
Display last updated time of the page.
```tsx
import { DocsPage } from 'fumadocs-ui/page';
;
```
Since you might have different version controls (e.g. Github) or it's from
remote sources like Sanity, Fumadocs UI doesn't display the last updated time by
default.
For Github hosted documents, you can use
the [`getGithubLastEdit`](/docs/headless/utils/git-last-edit) utility.
```tsx
import { DocsPage } from 'fumadocs-ui/page';
import { getGithubLastEdit } from 'fumadocs-core/server';
const time = await getGithubLastEdit({
owner: 'fuma-nama',
repo: 'fumadocs',
path: `content/docs/${page.file.path}`,
});
;
```
You can also specify the last updated time of documents (e.g. using frontmatter).
Don't forget to [update the schema type](/docs/mdx/collections#schema) on Fumadocs MDX first.
### Edit on GitHub
Add "Edit on GitHub" button to the page.
```tsx
import { DocsPage } from 'fumadocs-ui/page';
;
```
### Footer
Footer is a navigation element that has two buttons to jump to the next and previous pages. When not specified, it shows the neighbour pages found from page tree.
Customise the footer with the `footer` option.
```tsx
import { DocsPage, DocsBody } from 'fumadocs-ui/page';
...;
```
{/* */}
### Breadcrumb
A navigation element, shown only when user is navigating in folders.
{/* */}
### MDX Page
In conjunction of Fumadocs MDX, you may create a `page.mdx` file and add the following.
```mdx
export { withArticle as default } from 'fumadocs-ui/page';
## Hello World
```
This creates a page with MDX, with proper typography styles applied.
---
# Root Provider
URL: http://www.claudeskills.org/docs/layouts/root-provider
Description: The context provider of Fumadocs UI.
The context provider of all the components, including `next-themes` and context
for search dialog. It should be located at the root layout.
## Usage
```jsx
import { RootProvider } from 'fumadocs-ui/provider';
export default function Layout({ children }) {
return (
{children}
);
}
```
### Search Dialog
Customize or disable the search dialog with `search` option.
```jsx
{children}
```
Learn more from [Search](/docs/search).
### Theme Provider
Fumadocs supports light/dark modes with [`next-themes`](https://github.com/pacocoursey/next-themes).
Customise or disable it with `theme` option.
```jsx
{children}
```
---
# Manual Installation
URL: http://www.claudeskills.org/docs/manual-installation
Description: Create a new fumadocs project from scratch.
> Read the [Quick Start](/docs) guide first for basic concept.
## Getting Started
Create a new Next.js application with `create-next-app`, and install required packages.
```mdx
fumadocs-ui fumadocs-core
```
### Content Source
Fumadocs supports different content sources, you can choose one you prefer.
There is a list of officially supported sources:
- [Setup Fumadocs MDX](/docs/mdx)
- [Setup Content Collections](/docs/headless/content-collections)
Make sure to configure the library correctly following their setup guide before continuing, we will import the source adapter using `@/lib/source.ts` in this guide.
### Root Layout
Wrap the entire application inside [Root Provider](/docs/layouts/root-provider), and add required styles to `body`.
```tsx
import { RootProvider } from 'fumadocs-ui/provider';
import type { ReactNode } from 'react';
export default function Layout({ children }: { children: ReactNode }) {
return (
{children}
);
}
```
### Styles
Setup Tailwind CSS v4 on your Next.js app, add the following to `global.css`.
```css title="Tailwind CSS"
@import 'tailwindcss';
@import 'fumadocs-ui/css/neutral.css';
@import 'fumadocs-ui/css/preset.css';
/* path of `fumadocs-ui` relative to the CSS file */
@source '../node_modules/fumadocs-ui/dist/**/*.js';
```
> It doesn't come with a default font, you may choose one from `next/font`.
### Layout
Create a `app/layout.config.tsx` file to put the shared options for our layouts.
```json doc-gen:file
{
"file": "../../examples/next-mdx/app/layout.config.tsx",
"codeblock": {
"meta": "title=\"app/layout.config.tsx\""
}
}
```
Create a folder `/app/docs` for our docs, and give it a proper layout.
```json doc-gen:file
{
"file": "../../examples/next-mdx/app/docs/layout.tsx",
"codeblock": {
"meta": "title=\"app/docs/layout.tsx\""
}
}
```
> `pageTree` refers to Page Tree, it should be provided by your content source.
### Page
Create a catch-all route `/app/docs/[[...slug]]` for docs pages.
In the page, wrap your content in the [Page](/docs/layouts/page) component.
It may vary depending on your content source. You should configure static rendering with `generateStaticParams` and metadata with `generateMetadata`.
```json doc-gen:file
{
"file": "../../examples/next-mdx/app/docs/[[...slug]]/page.tsx",
"codeblock": {
"meta": "title=\"app/docs/[[...slug]]/page.tsx\" tab=\"Fumadocs MDX\""
}
}
```
```json doc-gen:file
{
"file": "../../examples/content-collections/app/docs/[[...slug]]/page.tsx",
"codeblock": {
"meta": "title=\"app/docs/[[...slug]]/page.tsx\" tab=\"Content Collections\""
}
}
```
### Search
Use the default document search based on Orama.
```json doc-gen:file
{
"file": "../../examples/next-mdx/app/api/search/route.ts",
"codeblock": {
"meta": "title=\"app/api/search/route.ts\" tab=\"Fumadocs MDX\""
}
}
```
```json doc-gen:file
{
"file": "../../examples/content-collections/app/api/search/route.ts",
"codeblock": {
"meta": "title=\"app/api/search/route.ts\" tab=\"Content Collections\""
}
}
```
Learn more about [Document Search](/docs/headless/search).
### Done
You can start the dev server and create MDX files.
```mdx title="content/docs/index.mdx"
---
title: Hello World
---
## Introduction
I love Anime.
```
## Customise
You can use [Home Layout](/docs/layouts/home-layout) for other pages of the site, it includes a navbar with theme toggle.
## Deploying
It should work out-of-the-box with Vercel & Netlify.
### Docker Deployment
If you want to deploy your Fumadocs app using Docker with **Fumadocs MDX configured**, make sure to add the `source.config.ts` file to the `WORKDIR` in the Dockerfile.
The following snippet is taken from the official [Next.js Dockerfile Example](https://github.com/vercel/next.js/blob/canary/examples/with-docker/Dockerfile):
```zsh title="Dockerfile"
WORKDIR /app
# Install dependencies based on the preferred package manager
COPY package.json yarn.lock* package-lock.json* pnpm-lock.yaml* .npmrc* source.config.ts ./
```
This ensures Fumadocs MDX can access your configuration file during builds.
---
# Markdown
URL: http://www.claudeskills.org/docs/markdown
Description: How to write documents
## Introduction
Fumadocs provides many useful extensions to MDX, a markup language. Here is a brief introduction to the default MDX syntax of Fumadocs UI.
> MDX is not the only supported format of Fumadocs. In fact, you can use any renderers such as `next-mdx-remote` or CMS.
## Markdown
We use GFM (GitHub Flavored Markdown), a superset of Markdown (CommonMark).
See [GFM Specification](https://github.github.com/gfm).
````md
# Heading
## Heading
### Heading
#### Heading
Hello World, **Bold**, _Italic_, ~~Hidden~~
```js
console.log('Hello World');
```
1. First
2. Second
3. Third
- Item 1
- Item 2
> Quote here

| Table | Description |
| ----- | ----------- |
| Hello | World |
````
### Auto Links
Internal links use the `next/link` component to allow prefetching and avoid hard-reload.
External links will get the default `rel="noreferrer noopener" target="_blank"` attributes for security.
```mdx
[My Link](https://github.github.com/gfm)
This also works: https://github.github.com/gfm.
```
## MDX
MDX is a superset of Markdown, with support of JSX syntax.
It allows you to import components, and use them right in the document, or even export values.
```mdx
import { Component } from './component';
```
see [MDX Syntax](https://mdxjs.com/docs/what-is-mdx/#mdx-syntax) to learn more.
### Cards
Useful for adding links, it is included by default.
```mdx
Learn more about caching in Next.js
```
Learn more about caching in Next.js
#### Icon
You can specify an icon to cards.
```mdx
import { HomeIcon } from 'lucide-react';
} href="/" title="Home">
Go back to home
```
} href="/" title="Go back to home">
The home page of Fumadocs.
#### Without href
```mdx
Learn more about `fetch` in Next.js.
```
Learn more about `fetch` in Next.js.
### Callouts
Useful for adding tips/warnings, it is included by default.
```mdx
Hello World
```
Hello World
#### Title
Specify a callout title.
```mdx
Hello World
```
Hello World
#### Types
You can specify the type of callout.
- `info` (default)
- `warn`
- `error`
```mdx
Hello World
```
Hello World
### Customise Components
See [all MDX components and available options](/docs/mdx).
## Headings
An anchor is automatically applied to each heading, it sanitizes invalid characters like spaces. (e.g. `Hello World` to `hello-world`)
```md
# Hello `World`
```
### TOC Settings
The table of contents (TOC) will be generated based on headings, you can also customise the effects of headings:
```md
# Heading [!toc]
This heading will be hidden from TOC.
# Another Heading [toc]
This heading will **only** be visible in TOC, you can use it to add additional TOC items.
Like headings rendered in a React component:
```
### Custom Anchor
You can add `[#slug]` to customise heading anchors.
```md
# heading [#my-heading-id]
```
You can also chain it with TOC settings like:
```md
# heading [toc] [#my-heading-id]
```
To link people to a specific heading, add the heading id to hash fragment: `/page#my-heading-id`.
## Frontmatter
We support YAML frontmatter. It is a way to specify common information of the document (e.g. title).
Place it at the top of document.
```mdx
---
title: Hello World
---
## Title
```
See [Page Conventions](/docs/page-conventions#frontmatter) for a list of properties available for frontmatter.
## Codeblock
Syntax Highlighting is supported by default using [Rehype Code](/docs/headless/mdx/rehype-code).
````mdx
```js
console.log('Hello World');
```
````
You can add a title to the codeblock.
````mdx
```js title="My Title"
console.log('Hello World');
```
````
### Highlight Lines
You can highlight specific lines by adding `[!code highlight]`.
````md
```tsx
Hello World
// [\!code highlight]
Hello World
Goodbye
Hello World
```
````
### Highlight Words
You can highlight a specific word by adding `[!code word:]`.
````md
```js
// [\!code word:config]
const config = {
reactStrictMode: true,
};
```
````
### Diffs
````mdx
```ts
console.log('hewwo'); // [\!code --]
console.log('hello'); // [\!code ++]
```
````
```ts
console.log('hewwo'); // [!code --]
console.log('hello'); // [!code ++]
```
### Tab Groups
You can use code blocks with the `` component.
````mdx
import { Tab, Tabs } from 'fumadocs-ui/components/tabs';
```ts
console.log('A');
```
```ts
console.log('B');
```
````
> Note that you can add MDX components instead of importing them in MDX files.
```ts
console.log('A');
```
```ts
console.log('B');
```
### Using Typescript Twoslash
Write Typescript codeblocks with hover type information and detected types errors.
Not enabled by default. See [Twoslash](/docs/twoslash).
## Images
All built-in content sources handle images properly.
Images are automatically optimized for `next/image`.
```mdx

```

## Optional
Some optional plugins you can enable.
### Math Equations
Write math equations with TeX.
````md
```mdx
f(x) = x * e^{2 pi i \xi x}
```
````
```mdx
f(x) = x * e^{2 pi i \xi x}
```
To enable, see [Math Integration](/docs/math).
### Package Install
Generate code blocks for installing packages via package managers (JS/Node.js).
````md
```mdx
npm i next -D
```
````
```mdx
npm i next -D
```
To enable, see [Remark Install](/docs/headless/mdx/install).
### More
You can see [a list of plugins](/docs/headless/mdx) supported by Fumadocs.
---
# MDX
URL: http://www.claudeskills.org/docs/mdx
Description: Default MDX Components
## Usage
The default MDX components include Cards, Callouts, Code Blocks and Headings.
```ts
import defaultMdxComponents from 'fumadocs-ui/mdx';
```
### Relative Link
To support links with relative file path in `href`, override the default `a` component with:
```tsx
import { createRelativeLink } from 'fumadocs-ui/mdx';
import { source } from '@/lib/source';
const page = source.getPage(['...']);
return (
);
```
```mdx
[My Link](./file.mdx)
```
Server Component only.
---
# Callout
URL: http://www.claudeskills.org/docs/mdx/callout
Description: Add callout to your docs
## Usage
Add it to your MDX components.
```tsx
import { Callout } from 'fumadocs-ui/components/callout';
;
```
See [Markdown](/docs/markdown#callouts) for usages.
### Reference
{/* */}
---
# Card
URL: http://www.claudeskills.org/docs/mdx/card
Description: Use the Card component in your MDX documentation
## Usage
Add it to your MDX components.
```tsx
import { Card, Cards } from 'fumadocs-ui/components/card';
;
```
See [Markdown](/docs/markdown#cards) for usages.
### Cards
The container of cards.
### Card
Based on Next.js ``.
{/* */}
If you're not using Fumadocs MDX for rendering MDX (e.g. using Contentlayer), ensure that
tree shaking is working properly.
Most of the icon libraries support importing icons individually.
```tsx
import HomeIcon from 'lucide-react/dist/esm/icons/home';
```
As a workaround, you can pass icons to MDX Components too. (this uses Next.js bundler instead of content source)
```tsx title="page.tsx"
import { HomeIcon } from 'lucide-react';
const components = {
...defaultComponents,
HomeIcon,
};
```
---
# Code Block
URL: http://www.claudeskills.org/docs/mdx/codeblock
Description: Adding code blocks to your docs
Display code blocks, added by default.
- Copy button
- Custom titles and icons
## Usage
Wrap the pre element in ``, which acts as the wrapper of code block.
```tsx
import { Pre, CodeBlock } from 'fumadocs-ui/components/codeblock';
(
{props.children}
{/* [!code highlight] */}
),
}}
/>;
```
See [Markdown](/docs/markdown#codeblock) for usages.
### Keep Background
Use the background color generated by Shiki (the Rehype Code plugin).
```tsx
import { Pre, CodeBlock } from 'fumadocs-ui/components/codeblock';
(
{props.children}
),
}}
/>;
```
### Icons
Specify a custom icon by passing an `icon` prop to `CodeBlock` component.
By default, the icon will be injected by the custom Shiki transformer.
```js title="config.js"
console.log('js');
```
---
# Heading
URL: http://www.claudeskills.org/docs/mdx/heading
Description: Heading components for your MDX documentation
The heading component which automatically adds the `id` prop.
## Usage
Add it to your MDX components, from `h1` to `h6`.
```mdx
import { Heading } from 'fumadocs-ui/components/heading';
,
h2: (props) => ,
h3: (props) => ,
h4: (props) => ,
h5: (props) => ,
h6: (props) => ,
}}
/>
```
---
# Search
URL: http://www.claudeskills.org/docs/search
Description: Implement document search in your docs
Fumadocs UI provides a good-looking search UI for your docs, the search functionality is instead provided and documented on Fumadocs Core.
See [Document Search](/docs/headless/search).
## Search UI
Open with ⌘K or CtrlK.
### Configurations
You can customize search UI from the [Root Provider](/docs/layouts/root-provider) component in root layout.
When not specified, it uses the Default [`fetch` Search Client](/docs/headless/search/orama) powered by Orama.
### Custom Links
Add custom link items to search dialog.
They are shown as fallbacks when the query is empty.
```tsx title="app/layout.tsx"
import { RootProvider } from 'fumadocs-ui/root-provider';
{children}
;
```
### Disable Search
To opt-out of document search, disable it from root provider.
```tsx
import { RootProvider } from 'fumadocs-ui/root-provider';
{children}
;
```
### Hot Keys
Customise the hot keys to trigger search dialog.
```tsx
import { RootProvider } from 'fumadocs-ui/root-provider';
{children}
;
```
### Tag Filter
Add UI to change filters.
Make sure to configure [Tag Filter](/docs/headless/search/orama#tag-filter) on search server first.
```tsx
import { RootProvider } from 'fumadocs-ui/root-provider';
{children}
;
```
### Search Options
Pass options to the search client, like changing the API endpoint for Orama search server:
```tsx
import { RootProvider } from 'fumadocs-ui/root-provider';
{children}
;
```
### Replace Search Dialog
You can replace the default Search Dialog with:
```tsx title="components/search.tsx"
'use client';
import SearchDialog from 'fumadocs-ui/components/dialog/search-default';
import type { SharedProps } from 'fumadocs-ui/components/dialog/search';
export default function CustomDialog(props: SharedProps) {
// your own logic here
return ;
}
```
To pass it to the Root Provider, you need a wrapper with `use client` directive.
```tsx title="provider.tsx"
'use client';
import { RootProvider } from 'fumadocs-ui/provider';
import dynamic from 'next/dynamic';
import type { ReactNode } from 'react';
const SearchDialog = dynamic(() => import('@/components/search')); // lazy load
export function Provider({ children }: { children: ReactNode }) {
return (
{children}
);
}
```
Use it instead of your previous Root Provider
```tsx title="layout.tsx"
import { Provider } from './provider';
import type { ReactNode } from 'react';
export default function Layout({ children }: { children: ReactNode }) {
return (
{children}
);
}
```
## Other Solutions
### Algolia
For the setup guide, see [Integrate Algolia Search](/docs/headless/search/algolia).
While generally we recommend building your own search with their client-side
SDK, you can also plug the built-in dialog interface.
```tsx title="components/search.tsx"
'use client';
import algo from 'algoliasearch/lite';
import type { SharedProps } from 'fumadocs-ui/components/dialog/search';
import SearchDialog from 'fumadocs-ui/components/dialog/search-algolia';
const client = algo('appId', 'apiKey');
const index = client.initIndex('indexName');
export default function CustomSearchDialog(props: SharedProps) {
return ;
}
```
1. Replace `appId`, `apiKey` and `indexName` with your desired values.
2. [Replace the default search dialog](#replace-search-dialog) with your new component.
The built-in implementation doesn't use instant search (their official
javascript client).
#### Tag Filter
Same as default search client, you can configure [Tag Filter](/docs/headless/search/algolia#tag-filter) on the dialog.
```tsx title="components/search.tsx"
import SearchDialog from 'fumadocs-ui/components/dialog/search-algolia';
;
```
### Orama Cloud
For the setup guide, see [Integrate Orama Cloud](/docs/headless/search/orama-cloud).
```tsx title="components/search.tsx"
'use client';
import { OramaClient } from '@oramacloud/client';
import type { SharedProps } from 'fumadocs-ui/components/dialog/search';
import SearchDialog from 'fumadocs-ui/components/dialog/search-orama';
const client = new OramaClient({
endpoint: 'endpoint',
api_key: 'apiKey',
});
export default function CustomSearchDialog(props: SharedProps) {
return ;
}
```
1. Replace `endpoint`, `apiKey` with your desired values.
2. [Replace the default search dialog](#replace-search-dialog) with your new component.
### Community Integrations
A list of integrations maintained by community.
- [Trieve Search](/docs/headless/search/trieve)
## Built-in UI
If you want to use the built-in search dialog UI instead of building your own,
you may use the `SearchDialog` component.
```tsx
import {
SearchDialog,
type SharedProps,
} from 'fumadocs-ui/components/dialog/search';
export default function CustomSearchDialog(props: SharedProps) {
return ;
}
```
It is an internal API, might break during iterations
---
# Claude Skills Examples - 19 Real Agent Skills Explained
URL: http://www.claudeskills.org/docs/skills-cases
Description: Browse real Claude Skills examples with full SKILL.md breakdowns: PDF, Word, PowerPoint, MCP Builder, brand guidelines, and more - learn how each one works and reuse it.
This is a library of real **Claude Skills examples** - 19 working agent skills with their full `SKILL.md` files, scripts, and resources explained page by page. Every entry originates from the official [`anthropics/skills`](https://github.com/anthropics/skills) repository (MIT licensed), so what you study here is what actually ships: document skills like [Docx](/docs/skills-cases/docx), [PDF](/docs/skills-cases/pdf), [Pptx](/docs/skills-cases/pptx), and [Xlsx](/docs/skills-cases/xlsx); builder skills like [MCP Builder](/docs/skills-cases/mcp-builder) and [Web Artifacts Builder](/docs/skills-cases/artifacts-builder); and design skills like [Brand Guidelines](/docs/skills-cases/brand-guidelines) and [Theme Factory](/docs/skills-cases/theme-factory).
If you are new to [Claude Skills](/), start with the concepts primer below, then open any example - or grab the [skill template](/docs/skills-cases/template-skill) to build your own.
## Skills
Skills are folders of instructions, scripts, and resources that Claude loads dynamically to improve performance on specialized tasks. Skills teach Claude how to complete specific jobs in a repeatable way, whether that's creating documents with your company's brand guidelines, analyzing data using your organization's specific workflows, or automating personal tasks.
### Further Reading
- [What are skills?](https://support.claude.com/en/articles/12512176-what-are-skills)
- [Using skills in Claude](https://support.claude.com/en/articles/12512180-using-skills-in-claude)
- [How to create custom skills](https://support.claude.com/en/articles/12512198-creating-custom-skills)
- [Equipping agents for the real world with Agent Skills](https://anthropic.com/engineering/equipping-agents-for-the-real-world-with-agent-skills)
## About This Repository
The repository contains example skills that demonstrate what's possible with Claude's skills ecosystem. These examples range from creative applications (art, music, design) to technical tasks (testing web apps, MCP server generation) to enterprise workflows (communications, branding, etc.).
Each skill is self-contained in its own directory with a `SKILL.md` file containing the instructions and metadata that Claude uses. Browse through these examples to get inspiration for your own skills or to understand different patterns and approaches.
The example skills in this repo are open source (Apache 2.0). Anthropic has also included the document creation and editing skills that power [Claude's document capabilities](https://www.anthropic.com/news/create-files) under the hood in the [`document-skills/`](https://github.com/anthropics/skills/tree/main/document-skills) folder. These are source-available, not open source, but serve as a reference for more complex skills actively used in production.
> **Disclaimer:** These skills are provided for demonstration and educational purposes only. While some of these capabilities may be available in Claude, the implementations and behaviors you receive from Claude may differ from what is shown in these examples. Always test skills thoroughly in your own environment before relying on them for critical tasks.
## Example Skills
This repository includes a diverse collection of example skills demonstrating different capabilities:
### Creative & Design
- **algorithmic-art**: Create generative art using p5.js with seeded randomness, flow fields, and particle systems
- **canvas-design**: Design visual art in `.png` and `.pdf` formats using design philosophies
- **frontend-design**: Transform UI requirements into production-ready frontend code with bold, accessible layouts
- **slack-gif-creator**: Create animated GIFs optimized for Slack's size constraints
### Development & Technical
- **artifacts-builder**: Build complex claude.ai HTML artifacts using React, Tailwind CSS, and shadcn/ui components
- **mcp-builder**: Guide for creating high-quality MCP servers to integrate external APIs and services
- **webapp-testing**: Test local web applications using Playwright for UI verification and debugging
### Enterprise & Communication
- **brand-guidelines**: Apply Anthropic's official brand colors and typography to artifacts
- **internal-comms**: Write internal communications like status reports, newsletters, and FAQs
- **theme-factory**: Style artifacts with 10 pre-set professional themes or generate custom themes on the fly
### Meta Skills
- **skill-creator**: Guide for creating effective skills that extend Claude's capabilities
- **template-skill**: A basic template to use as a starting point for new skills
## Document Skills
The `document-skills/` subdirectory contains skills that Anthropic developed to help Claude create various document file formats. These skills demonstrate advanced patterns for working with complex file formats and binary data:
- **docx**: Create, edit, and analyze Word documents with support for tracked changes, comments, formatting preservation, and text extraction
- **pdf**: Comprehensive PDF manipulation toolkit for extracting text and tables, creating new PDFs, merging/splitting documents, and handling forms
- **pptx**: Create, edit, and analyze PowerPoint presentations with support for layouts, templates, charts, and automated slide generation
- **xlsx**: Create, edit, and analyze Excel spreadsheets with support for formulas, formatting, data analysis, and visualization
- **doc-coauthoring**: Collaborate on document revisions with review-ready notes, edits, and structured feedback
> **Note:** These document skills are point-in-time snapshots and are not actively maintained or updated. Versions of these skills ship pre-included with Claude. They are primarily intended as reference examples to illustrate how Anthropic approaches developing more complex skills that work with binary file formats and document structures.
## Try in Claude Code, Claude.ai, and the API
### Claude Code
You can register this repository as a Claude Code Plugin marketplace by running the following command in Claude Code:
```text
/plugin marketplace add anthropics/skills
```
After installing the plugin, you can use the skill by just mentioning it. For instance, if you install the document-skills plugin from the marketplace, you can ask Claude Code to do something like: "use the pdf skill to extract the form fields from path/to/some-file.pdf".
### Claude.ai
These example skills are already available to paid plans in Claude.ai. To use any skill from this repository or upload custom skills, follow the instructions in [Using skills in Claude](https://support.claude.com/en/articles/12512180-using-skills-in-claude#h_a4222fa77b).
### Claude API
You can use Anthropic's pre-built skills, and upload custom skills, via the Claude API. See the [Skills API Quickstart](https://docs.claude.com/en/api/skills-guide#creating-a-skill) for more.
## Creating a Basic Skill
Skills are simple to create: just a folder with a `SKILL.md` file containing YAML frontmatter and instructions. You can use the **template-skill** in this repository as a starting point:
```markdown
---
name: my-skill-name
description: A clear description of what this skill does and when to use it
---
# My Skill Name
[Add your instructions here that Claude will follow when this skill is active]
## Examples
- Example usage 1
- Example usage 2
## Guidelines
- Guideline 1
- Guideline 2
```
The frontmatter requires only two fields:
- `name`: A unique identifier for your skill (lowercase, hyphens for spaces)
- `description`: A complete description of what the skill does and when to use it
The markdown content below contains the instructions, examples, and guidelines that Claude will follow. For more details, see [How to create custom skills](https://support.claude.com/en/articles/12512198-creating-custom-skills).
## Partner Skills
Skills are an effective way to teach Claude how to get better at using specific software. As Anthropic sees notable examples from partners, they may highlight them here:
- **Notion**: [Notion Skills for Claude](https://www.notion.so/notiondevs/Notion-Skills-for-Claude-28da4445d27180c7af1df7d8615723d0)
---
# Algorithmic Art Skill - Generative Art with Claude
URL: http://www.claudeskills.org/docs/skills-cases/algorithmic-art
Description: How the Algorithmic Art skill guides Claude through seeded randomness, flow fields, and p5.js sketches - full SKILL.md breakdown.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Creating algorithmic art using p5.js with seeded randomness and interactive parameter exploration. Use this when users request creating art using code, generative art, algorithmic art, flow fields, or particle systems."*
## How the skill works
The skill's defining idea is that Claude must **write an algorithmic philosophy before writing code**. The SKILL.md walks through:
- **Philosophy creation** - generating a named artistic stance (with worked philosophy examples) instead of jumping to visuals
- **Deducing the conceptual seed** - deriving the artwork's controlling idea from the user's request
- **p5.js implementation** - with a hard rule marked "⚠️ STEP 0: READ THE TEMPLATE FIRST": all sketches start from `templates/generator_template.js`
- **Craftsmanship + technical requirements** - seeded randomness so every output is reproducible, and interactive parameter exploration via the bundled viewer
- **What's fixed vs variable** - which parts of the template Claude may change and which it must not
## What's inside the skill folder
- `templates/generator_template.js` - the mandatory p5.js starting point
- `templates/viewer.html` - interactive parameter explorer
- `SKILL.md` (~20 KB, one of the most detailed official skills), `LICENSE.txt`
## Key takeaways for your own skills
- **Templates with a "do not deviate" contract** produce far more consistent output than open-ended instructions.
- Seeded randomness turns generative art into a reproducible, parameterized artifact - the same discipline applies to any skill that generates variable output.
## See it on GitHub
[skills/algorithmic-art](https://github.com/anthropics/skills/tree/main/skills/algorithmic-art)
---
# Web Artifacts Builder - Claude Skill for React Artifacts
URL: http://www.claudeskills.org/docs/skills-cases/artifacts-builder
Description: How the Web Artifacts Builder skill bundles React and Tailwind into single-file HTML artifacts with shadcn components - full skill walkthrough.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Suite of tools for creating elaborate, multi-component claude.ai HTML artifacts using modern frontend web technologies (React, Tailwind CSS, shadcn/ui). Use for complex artifacts requiring state management, routing, or shadcn/ui components - not for simple single-file HTML/JSX artifacts."*
Note the scope line: simple one-file artifacts don't need this skill. It exists for the moment a project outgrows a single JSX block.
## How the skill works
The SKILL.md is a five-step pipeline wrapped in design guidelines:
1. **Initialize** the project with `scripts/init-artifact.sh` - a preconfigured React + Tailwind + shadcn/ui workspace
2. **Develop** with real components, state management, and routing
3. **Bundle** everything into a single HTML file with `scripts/bundle-artifact.sh`
4. **Share** the artifact with the user
5. **Test/visualize** it (optional verification step)
A `shadcn-components.tar.gz` archive ships inside the skill so components install without network access.
## What's inside the skill folder
- `scripts/init-artifact.sh` - project scaffolding
- `scripts/bundle-artifact.sh` - single-file HTML bundler
- `scripts/shadcn-components.tar.gz` - offline component library
- `SKILL.md`, `LICENSE.txt`
## Key takeaways for your own skills
- **Executable scripts beat instructions**: instead of describing setup in prose, the skill ships shell scripts Claude runs.
- Bundling offline dependencies (the shadcn archive) makes a skill work in sandboxed environments - a detail most community skills miss.
## See it on GitHub
[skills/web-artifacts-builder](https://github.com/anthropics/skills/tree/main/skills/web-artifacts-builder)
---
# Brand Guidelines Skill - Keep Claude Output On-Brand
URL: http://www.claudeskills.org/docs/skills-cases/brand-guidelines
Description: How the Brand Guidelines skill locks Claude's colors, typography, and voice to your brand system - full SKILL.md walkthrough with reuse tips.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Applies Anthropic's official brand colors and typography to any sort of artifact that may benefit from having Anthropic's look-and-feel. Use it when brand colors or style guidelines, visual formatting, or company design standards apply."*
This is the reference example of a **corporate identity skill**: it encodes one company's design system so every artifact Claude produces stays on-brand. Swap in your own values and you have a brand skill for your team.
## How the skill works
The SKILL.md is a compact design-system spec:
- **Colors** - Anthropic's official palette with usage roles (backgrounds, text, shapes, accents)
- **Typography** - the approved font stack with smart font application rules
- **Features** - text styling conventions and shape/accent color application
- **Technical details** - font management and color application mechanics, so the rules survive across HTML, slides, and documents
## What's inside the skill folder
- `SKILL.md` (~2 KB - one of the smallest official skills)
- `LICENSE.txt`
## Key takeaways for your own skills
- A brand skill doesn't need to be big: **2 KB of precise tokens beats 20 KB of prose**.
- Encode *roles* ("accent", "background"), not just hex values - that is what lets Claude apply the system to artifact types you didn't anticipate.
- This pattern is the fastest win for teams: fork it, replace the palette and fonts, done.
## See it on GitHub
[skills/brand-guidelines](https://github.com/anthropics/skills/tree/main/skills/brand-guidelines)
---
# Canvas Design Skill - Posters & Visual Art with Claude
URL: http://www.claudeskills.org/docs/skills-cases/canvas-design
Description: The Canvas Design skill turns Claude into a poster and visual-art designer with layout philosophy and PDF/PNG output - full walkthrough.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Create beautiful visual art in .png and .pdf documents using design philosophy. You should use this skill when the user asks to create a poster, piece of art, design, or other static piece. Create original visual designs, never copying existing artists' work to avoid copyright violations."*
## How the skill works
Like its sibling `algorithmic-art`, this skill makes Claude **author a visual philosophy first**: a named aesthetic stance with essential principles, before any pixels. The SKILL.md covers philosophy generation (with examples), deducing the "subtle reference" from the brief, the canvas creation process itself, a final review step, and a multi-page option for booklet-style outputs.
The skill ships its own **font library** - six licensed typefaces (Arsenal SC, Big Shoulders, Boldonse, Bricolage Grotesque, and more, each with OFL license files) - so typography never falls back to system defaults.
## What's inside the skill folder
- `canvas-fonts/` - bundled OFL-licensed fonts with license texts
- `SKILL.md` (~12 KB), `LICENSE.txt`
## Key takeaways for your own skills
- **Bundle your assets**: shipping fonts inside the skill removes the single biggest source of visual sameness.
- The philosophy-first pattern (shared with algorithmic-art) is Anthropic's repeated answer to "how do you make AI output less generic" - worth stealing for any creative skill.
## See it on GitHub
[skills/canvas-design](https://github.com/anthropics/skills/tree/main/skills/canvas-design)
---
# Claude API Skill - API Reference Guidance for Claude
URL: http://www.claudeskills.org/docs/skills-cases/claude-api
Description: The Claude API skill keeps model IDs, pricing, and SDK patterns at Claude's fingertips - see the reference skill inside.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the July 1, 2026 upstream update - this is one of the most actively maintained official skills.
## Overview
The claude-api skill is Anthropic's answer to a hard problem: **models' training knowledge of their own API goes stale**. It keeps current model IDs, pricing, and SDK patterns at Claude's fingertips - the SKILL.md literally contains a section titled "⚠️ API Drift - Your Training Prior May Be Stale" and a model table cached with an explicit date.
## How the skill works
The SKILL.md (roughly 73 KB - by far the largest official skill) is structured as a reference router:
- **Before you start / defaults** - output requirements and safe defaults
- **Which surface should I use?** - a decision tree across the Messages API, Tool Runner, Managed Agents, and the Agent SDK, including "Should I build an agent?"
- **Current models** - a dated table (cached June 24, 2026 as of this sync) covering the Claude 5 family including Fable 5, with IDs and capabilities
- **Authentication quick reference** plus language detection and per-language feature support
Beyond the SKILL.md, the folder fans out into **per-language reference packs**: curl, Python, TypeScript, Go, C#, and more - each with files like `streaming.md`, `tool-use.md`, `batches.md`, `files-api.md`, and `managed-agents.md`.
## What's inside the skill folder
- `SKILL.md` - the router and model reference
- `curl/`, `csharp/claude-api/`, `go/`, and other per-language directories with focused reference files
- `LICENSE.txt`
## Key takeaways for your own skills
- **Date-stamp cached facts** ("Current models, cached 2026-06-24") so both Claude and readers know freshness at a glance.
- The router + per-language-files layout shows how to keep a huge knowledge skill loadable: the main file decides, the leaf files carry detail.
## See it on GitHub
[skills/claude-api](https://github.com/anthropics/skills/tree/main/skills/claude-api)
---
# Doc Co-Authoring Skill - Draft Documents with Claude
URL: http://www.claudeskills.org/docs/skills-cases/doc-coauthoring
Description: How the Doc Co-Authoring skill structures Claude's drafting workflow: outlines, revisions, and collaborative editing - full breakdown.
Source: Content adapted from anthropics/skills (MIT).
This skill provides a structured workflow for guiding users through collaborative document creation. Act as an active guide, walking users through three stages: Context Gathering, Refinement & Structure, and Reader Testing.
## When to Offer This Workflow
**Trigger conditions:**
- User mentions writing documentation: "write a doc", "draft a proposal", "create a spec", "write up"
- User mentions specific doc types: "PRD", "design doc", "decision doc", "RFC"
- User seems to be starting a substantial writing task
**Initial offer:**
Offer the user a structured workflow for co-authoring the document. Explain the three stages:
1. **Context Gathering**: User provides all relevant context while Claude asks clarifying questions
2. **Refinement & Structure**: Iteratively build each section through brainstorming and editing
3. **Reader Testing**: Test the doc with a fresh Claude (no context) to catch blind spots before others read it
Explain that this approach helps ensure the doc works well when others read it (including when they paste it into Claude). Ask if they want to try this workflow or prefer to work freeform.
If user declines, work freeform. If user accepts, proceed to Stage 1.
## Stage 1: Context Gathering
**Goal:** Close the gap between what the user knows and what Claude knows, enabling smart guidance later.
### Initial Questions
Start by asking the user for meta-context about the document:
1. What type of document is this? (e.g., technical spec, decision doc, proposal)
2. Who's the primary audience?
3. What's the desired impact when someone reads this?
4. Is there a template or specific format to follow?
5. Any other constraints or context to know?
Inform them they can answer in shorthand or dump information however works best for them.
**If user provides a template or mentions a doc type:**
- Ask if they have a template document to share
- If they provide a link to a shared document, use the appropriate integration to fetch it
- If they provide a file, read it
**If user mentions editing an existing shared document:**
- Use the appropriate integration to read the current state
- Check for images without alt-text
- If images exist without alt-text, explain that when others use Claude to understand the doc, Claude won't be able to see them. Ask if they want alt-text generated. If so, request they paste each image into chat for descriptive alt-text generation.
### Info Dumping
Once initial questions are answered, encourage the user to dump all the context they have. Request information such as:
- Background on the project/problem
- Related team discussions or shared documents
- Why alternative solutions aren't being used
- Organizational context (team dynamics, past incidents, politics)
- Timeline pressures or constraints
- Technical architecture or dependencies
- Stakeholder concerns
Advise them not to worry about organizing it - just get it all out. Offer multiple ways to provide context:
- Info dump stream-of-consciousness
- Point to team channels or threads to read
- Link to shared documents
**If integrations are available** (e.g., Slack, Teams, Google Drive, SharePoint, or other MCP servers), mention that these can be used to pull in context directly.
**If no integrations are detected and in Claude.ai or Claude app:** Suggest they can enable connectors in their Claude settings to allow pulling context from messaging apps and document storage directly.
Inform them clarifying questions will be asked once they've done their initial dump.
**During context gathering:**
- If user mentions team channels or shared documents:
- If integrations available: Inform them the content will be read now, then use the appropriate integration
- If integrations not available: Explain lack of access. Suggest they enable connectors in Claude settings, or paste the relevant content directly.
- If user mentions entities/projects that are unknown:
- Ask if connected tools should be searched to learn more
- Wait for user confirmation before searching
- As user provides context, track what's being learned and what's still unclear
**Asking clarifying questions:**
When user signals they've done their initial dump (or after substantial context provided), ask clarifying questions to ensure understanding:
Generate 5-10 numbered questions based on gaps in the context.
Inform them they can use shorthand to answer (e.g., "1: yes, 2: see #channel, 3: no because backwards compat"), link to more docs, point to channels to read, or just keep info-dumping. Whatever's most efficient for them.
**Exit condition:**
Sufficient context has been gathered when questions show understanding - when edge cases and trade-offs can be asked about without needing basics explained.
**Transition:**
Ask if there's any more context they want to provide at this stage, or if it's time to move on to drafting the document.
If user wants to add more, let them. When ready, proceed to Stage 2.
## Stage 2: Refinement & Structure
**Goal:** Build the document section by section through brainstorming, curation, and iterative refinement.
**Instructions to user:**
Explain that the document will be built section by section. For each section:
1. Clarifying questions will be asked about what to include
2. 5-20 options will be brainstormed
3. User will indicate what to keep/remove/combine
4. The section will be drafted
5. It will be refined through surgical edits
Start with whichever section has the most unknowns (usually the core decision/proposal), then work through the rest.
**Section ordering:**
If the document structure is clear:
Ask which section they'd like to start with.
Suggest starting with whichever section has the most unknowns. For decision docs, that's usually the core proposal. For specs, it's typically the technical approach. Summary sections are best left for last.
If user doesn't know what sections they need:
Based on the type of document and template, suggest 3-5 sections appropriate for the doc type.
Ask if this structure works, or if they want to adjust it.
**Once structure is agreed:**
Create the initial document structure with placeholder text for all sections.
**If access to artifacts is available:**
Use `create_file` to create an artifact. This gives both Claude and the user a scaffold to work from.
Inform them that the initial structure with placeholders for all sections will be created.
Create artifact with all section headers and brief placeholder text like "[To be written]" or "[Content here]".
Provide the scaffold link and indicate it's time to fill in each section.
**If no access to artifacts:**
Create a markdown file in the working directory. Name it appropriately (e.g., `decision-doc.md`, `technical-spec.md`).
Inform them that the initial structure with placeholders for all sections will be created.
Create file with all section headers and placeholder text.
Confirm the filename has been created and indicate it's time to fill in each section.
**For each section:**
### Step 1: Clarifying Questions
Announce work will begin on the [SECTION NAME] section. Ask 5-10 clarifying questions about what should be included:
Generate 5-10 specific questions based on context and section purpose.
Inform them they can answer in shorthand or just indicate what's important to cover.
### Step 2: Brainstorming
For the [SECTION NAME] section, brainstorm [5-20] things that might be included, depending on the section's complexity. Look for:
- Context shared that might have been forgotten
- Angles or considerations not yet mentioned
Generate 5-20 numbered options based on section complexity. At the end, offer to brainstorm more if they want additional options.
### Step 3: Curation
Ask which points should be kept, removed, or combined. Request brief justifications to help learn priorities for the next sections.
Provide examples:
- "Keep 1,4,7,9"
- "Remove 3 (duplicates 1)"
- "Remove 6 (audience already knows this)"
- "Combine 11 and 12"
**If user gives freeform feedback** (e.g., "looks good" or "I like most of it but...") instead of numbered selections, extract their preferences and proceed. Parse what they want kept/removed/changed and apply it.
### Step 4: Gap Check
Based on what they've selected, ask if there's anything important missing for the [SECTION NAME] section.
### Step 5: Drafting
Use `str_replace` to replace the placeholder text for this section with the actual drafted content.
Announce the [SECTION NAME] section will be drafted now based on what they've selected.
**If using artifacts:**
After drafting, provide a link to the artifact.
Ask them to read through it and indicate what to change. Note that being specific helps learning for the next sections.
**If using a file (no artifacts):**
After drafting, confirm completion.
Inform them the [SECTION NAME] section has been drafted in [filename]. Ask them to read through it and indicate what to change. Note that being specific helps learning for the next sections.
**Key instruction for user (include when drafting the first section):**
Provide a note: Instead of editing the doc directly, ask them to indicate what to change. This helps learning of their style for future sections. For example: "Remove the X bullet - already covered by Y" or "Make the third paragraph more concise".
### Step 6: Iterative Refinement
As user provides feedback:
- Use `str_replace` to make edits (never reprint the whole doc)
- **If using artifacts:** Provide link to artifact after each edit
- **If using files:** Just confirm edits are complete
- If user edits doc directly and asks to read it: mentally note the changes they made and keep them in mind for future sections (this shows their preferences)
**Continue iterating** until user is satisfied with the section.
### Quality Checking
After 3 consecutive iterations with no substantial changes, ask if anything can be removed without losing important information.
When section is done, confirm [SECTION NAME] is complete. Ask if ready to move to the next section.
**Repeat for all sections.**
### Near Completion
As approaching completion (80%+ of sections done), announce intention to re-read the entire document and check for:
- Flow and consistency across sections
- Redundancy or contradictions
- Anything that feels like "slop" or generic filler
- Whether every sentence carries weight
Read entire document and provide feedback.
**When all sections are drafted and refined:**
Announce all sections are drafted. Indicate intention to review the complete document one more time.
Review for overall coherence, flow, completeness.
Provide any final suggestions.
Ask if ready to move to Reader Testing, or if they want to refine anything else.
## Stage 3: Reader Testing
**Goal:** Test the document with a fresh Claude (no context bleed) to verify it works for readers.
**Instructions to user:**
Explain that testing will now occur to see if the document actually works for readers. This catches blind spots - things that make sense to the authors but might confuse others.
### Testing Approach
**If access to sub-agents is available (e.g., in Claude Code):**
Perform the testing directly without user involvement.
### Step 1: Predict Reader Questions
Announce intention to predict what questions readers might ask when trying to discover this document.
Generate 5-10 questions that readers would realistically ask.
### Step 2: Test with Sub-Agent
Announce that these questions will be tested with a fresh Claude instance (no context from this conversation).
For each question, invoke a sub-agent with just the document content and the question.
Summarize what Reader Claude got right/wrong for each question.
### Step 3: Run Additional Checks
Announce additional checks will be performed.
Invoke sub-agent to check for ambiguity, false assumptions, contradictions.
Summarize any issues found.
### Step 4: Report and Fix
If issues found:
Report that Reader Claude struggled with specific issues.
List the specific issues.
Indicate intention to fix these gaps.
Loop back to refinement for problematic sections.
---
**If no access to sub-agents (e.g., claude.ai web interface):**
The user will need to do the testing manually.
### Step 1: Predict Reader Questions
Ask what questions people might ask when trying to discover this document. What would they type into Claude.ai?
Generate 5-10 questions that readers would realistically ask.
### Step 2: Setup Testing
Provide testing instructions:
1. Open a fresh Claude conversation: https://claude.ai
2. Paste or share the document content (if using a shared doc platform with connectors enabled, provide the link)
3. Ask Reader Claude the generated questions
For each question, instruct Reader Claude to provide:
- The answer
- Whether anything was ambiguous or unclear
- What knowledge/context the doc assumes is already known
Check if Reader Claude gives correct answers or misinterprets anything.
### Step 3: Additional Checks
Also ask Reader Claude:
- "What in this doc might be ambiguous or unclear to readers?"
- "What knowledge or context does this doc assume readers already have?"
- "Are there any internal contradictions or inconsistencies?"
### Step 4: Iterate Based on Results
Ask what Reader Claude got wrong or struggled with. Indicate intention to fix those gaps.
Loop back to refinement for any problematic sections.
---
### Exit Condition (Both Approaches)
When Reader Claude consistently answers questions correctly and doesn't surface new gaps or ambiguities, the doc is ready.
## Final Review
When Reader Testing passes:
Announce the doc has passed Reader Claude testing. Before completion:
1. Recommend they do a final read-through themselves - they own this document and are responsible for its quality
2. Suggest double-checking any facts, links, or technical details
3. Ask them to verify it achieves the impact they wanted
Ask if they want one more review, or if the work is done.
**If user wants final review, provide it. Otherwise:**
Announce document completion. Provide a few final tips:
- Consider linking this conversation in an appendix so readers can see how the doc was developed
- Use appendices to provide depth without bloating the main doc
- Update the doc as feedback is received from real readers
## Tips for Effective Guidance
**Tone:**
- Be direct and procedural
- Explain rationale briefly when it affects user behavior
- Don't try to "sell" the approach - just execute it
**Handling Deviations:**
- If user wants to skip a stage: Ask if they want to skip this and write freeform
- If user seems frustrated: Acknowledge this is taking longer than expected. Suggest ways to move faster
- Always give user agency to adjust the process
**Context Management:**
- Throughout, if context is missing on something mentioned, proactively ask
- Don't let gaps accumulate - address them as they come up
**Artifact Management:**
- Use `create_file` for drafting full sections
- Use `str_replace` for all edits
- Provide artifact link after every change
- Never use artifacts for brainstorming lists - that's just conversation
**Quality over Speed:**
- Don't rush through stages
- Each iteration should make meaningful improvements
- The goal is a document that actually works for readers
## See in GitHub
[See in GitHub](https://github.com/anthropics/skills/tree/main/doc-coauthoring)
---
# Docx Skill - Create & Edit Word Documents with Claude
URL: http://www.claudeskills.org/docs/skills-cases/docx
Description: The Docx skill lets Claude create, edit, and format Word documents: headings, tables of contents, tracked changes, and templates - see how the skill works inside.
Source: Content adapted from anthropics/skills (MIT).
## Overview
A .docx file is a ZIP archive containing XML files.
## Quick Reference
| Task | Approach |
|------|----------|
| Read/analyze content | `pandoc` or unpack for raw XML |
| Create new document | Use `docx-js` - see Creating New Documents below |
| Edit existing document | Unpack -> edit XML -> repack - see Editing Existing Documents below |
### Converting .doc to .docx
Legacy `.doc` files must be converted before editing:
```bash
python scripts/office/soffice.py --headless --convert-to docx document.doc
```
### Reading Content
```bash
# Text extraction with tracked changes
pandoc --track-changes=all document.docx -o output.md
# Raw XML access
python scripts/office/unpack.py document.docx unpacked/
```
### Converting to Images
```bash
python scripts/office/soffice.py --headless --convert-to pdf document.docx
pdftoppm -jpeg -r 150 document.pdf page
```
### Accepting Tracked Changes
To produce a clean document with all tracked changes accepted (requires LibreOffice):
```bash
python scripts/accept_changes.py input.docx output.docx
```
---
## Creating New Documents
Generate .docx files with JavaScript, then validate. Install: `npm install -g docx`
### Setup
```javascript
const { Document, Packer, Paragraph, TextRun, Table, TableRow, TableCell, ImageRun,
Header, Footer, AlignmentType, PageOrientation, LevelFormat, ExternalHyperlink,
InternalHyperlink, Bookmark, FootnoteReferenceRun, PositionalTab,
PositionalTabAlignment, PositionalTabRelativeTo, PositionalTabLeader,
TabStopType, TabStopPosition, Column, SectionType,
TableOfContents, HeadingLevel, BorderStyle, WidthType, ShadingType,
VerticalAlign, PageNumber, PageBreak } = require('docx');
const doc = new Document({ sections: [{ children: [/* content */] }] });
Packer.toBuffer(doc).then(buffer => fs.writeFileSync("doc.docx", buffer));
```
### Validation
After creating the file, validate it. If validation fails, unpack, fix the XML, and repack.
```bash
python scripts/office/validate.py doc.docx
```
### Page Size
```javascript
// CRITICAL: docx-js defaults to A4, not US Letter
// Always set page size explicitly for consistent results
sections: [{
properties: {
page: {
size: {
width: 12240, // 8.5 inches in DXA
height: 15840 // 11 inches in DXA
},
margin: { top: 1440, right: 1440, bottom: 1440, left: 1440 } // 1 inch margins
}
},
children: [/* content */]
}]
```
**Common page sizes (DXA units, 1440 DXA = 1 inch):**
| Paper | Width | Height | Content Width (1" margins) |
|-------|-------|--------|---------------------------|
| US Letter | 12,240 | 15,840 | 9,360 |
| A4 (default) | 11,906 | 16,838 | 9,026 |
**Landscape orientation:** docx-js swaps width/height internally, so pass portrait dimensions and let it handle the swap:
```javascript
size: {
width: 12240, // Pass SHORT edge as width
height: 15840, // Pass LONG edge as height
orientation: PageOrientation.LANDSCAPE // docx-js swaps them in the XML
},
// Content width = 15840 - left margin - right margin (uses the long edge)
```
### Styles (Override Built-in Headings)
Use Arial as the default font (universally supported). Keep titles black for readability.
```javascript
const doc = new Document({
styles: {
default: { document: { run: { font: "Arial", size: 24 } } }, // 12pt default
paragraphStyles: [
// IMPORTANT: Use exact IDs to override built-in styles
{ id: "Heading1", name: "Heading 1", basedOn: "Normal", next: "Normal", quickFormat: true,
run: { size: 32, bold: true, font: "Arial" },
paragraph: { spacing: { before: 240, after: 240 }, outlineLevel: 0 } }, // outlineLevel required for TOC
{ id: "Heading2", name: "Heading 2", basedOn: "Normal", next: "Normal", quickFormat: true,
run: { size: 28, bold: true, font: "Arial" },
paragraph: { spacing: { before: 180, after: 180 }, outlineLevel: 1 } },
]
},
sections: [{
children: [
new Paragraph({ heading: HeadingLevel.HEADING_1, children: [new TextRun("Title")] }),
]
}]
});
```
### Lists (NEVER use unicode bullets)
```javascript
// WRONG - never manually insert bullet characters
new Paragraph({ children: [new TextRun("* Item")] }) // BAD
new Paragraph({ children: [new TextRun("\u2022 Item")] }) // BAD
// CORRECT - use numbering config with LevelFormat.BULLET
const doc = new Document({
numbering: {
config: [
{ reference: "bullets",
levels: [{ level: 0, format: LevelFormat.BULLET, text: "*", alignment: AlignmentType.LEFT,
style: { paragraph: { indent: { left: 720, hanging: 360 } } } }] },
{ reference: "numbers",
levels: [{ level: 0, format: LevelFormat.DECIMAL, text: "%1.", alignment: AlignmentType.LEFT,
style: { paragraph: { indent: { left: 720, hanging: 360 } } } }] },
]
},
sections: [{
children: [
new Paragraph({ numbering: { reference: "bullets", level: 0 },
children: [new TextRun("Bullet item")] }),
new Paragraph({ numbering: { reference: "numbers", level: 0 },
children: [new TextRun("Numbered item")] }),
]
}]
});
// Each reference creates INDEPENDENT numbering
// Same reference = continues (1,2,3 then 4,5,6)
// Different reference = restarts (1,2,3 then 1,2,3)
```
### Tables
**CRITICAL: Tables need dual widths** - set both `columnWidths` on the table AND `width` on each cell. Without both, tables render incorrectly on some platforms.
```javascript
// CRITICAL: Always set table width for consistent rendering
// CRITICAL: Use ShadingType.CLEAR (not SOLID) to prevent black backgrounds
const border = { style: BorderStyle.SINGLE, size: 1, color: "CCCCCC" };
const borders = { top: border, bottom: border, left: border, right: border };
new Table({
width: { size: 9360, type: WidthType.DXA }, // Always use DXA (percentages break in Google Docs)
columnWidths: [4680, 4680], // Must sum to table width (DXA: 1440 = 1 inch)
rows: [
new TableRow({
children: [
new TableCell({
borders,
width: { size: 4680, type: WidthType.DXA }, // Also set on each cell
shading: { fill: "D5E8F0", type: ShadingType.CLEAR }, // CLEAR not SOLID
margins: { top: 80, bottom: 80, left: 120, right: 120 }, // Cell padding (internal, not added to width)
children: [new Paragraph({ children: [new TextRun("Cell")] })]
})
]
})
]
})
```
**Table width calculation:**
Always use `WidthType.DXA` - `WidthType.PERCENTAGE` breaks in Google Docs.
```javascript
// Table width = sum of columnWidths = content width
// US Letter with 1" margins: 12240 - 2880 = 9360 DXA
width: { size: 9360, type: WidthType.DXA },
columnWidths: [7000, 2360] // Must sum to table width
```
**Width rules:**
- **Always use `WidthType.DXA`** - never `WidthType.PERCENTAGE` (incompatible with Google Docs)
- Table width must equal the sum of `columnWidths`
- Cell `width` must match corresponding `columnWidth`
- Cell `margins` are internal padding - they reduce content area, not add to cell width
- For full-width tables: use content width (page width minus left and right margins)
### Images
```javascript
// CRITICAL: type parameter is REQUIRED
new Paragraph({
children: [new ImageRun({
type: "png", // Required: png, jpg, jpeg, gif, bmp, svg
data: fs.readFileSync("image.png"),
transformation: { width: 200, height: 150 },
altText: { title: "Title", description: "Desc", name: "Name" } // All three required
})]
})
```
### Page Breaks
```javascript
// CRITICAL: PageBreak must be inside a Paragraph
new Paragraph({ children: [new PageBreak()] })
// Or use pageBreakBefore
new Paragraph({ pageBreakBefore: true, children: [new TextRun("New page")] })
```
### Hyperlinks
```javascript
// External link
new Paragraph({
children: [new ExternalHyperlink({
children: [new TextRun({ text: "Click here", style: "Hyperlink" })],
link: "https://example.com",
})]
})
// Internal link (bookmark + reference)
// 1. Create bookmark at destination
new Paragraph({ heading: HeadingLevel.HEADING_1, children: [
new Bookmark({ id: "chapter1", children: [new TextRun("Chapter 1")] }),
]})
// 2. Link to it
new Paragraph({ children: [new InternalHyperlink({
children: [new TextRun({ text: "See Chapter 1", style: "Hyperlink" })],
anchor: "chapter1",
})]})
```
### Footnotes
```javascript
const doc = new Document({
footnotes: {
1: { children: [new Paragraph("Source: Annual Report 2024")] },
2: { children: [new Paragraph("See appendix for methodology")] },
},
sections: [{
children: [new Paragraph({
children: [
new TextRun("Revenue grew 15%"),
new FootnoteReferenceRun(1),
new TextRun(" using adjusted metrics"),
new FootnoteReferenceRun(2),
],
})]
}]
});
```
### Tab Stops
```javascript
// Right-align text on same line (e.g., date opposite a title)
new Paragraph({
children: [
new TextRun("Company Name"),
new TextRun("\tJanuary 2025"),
],
tabStops: [{ type: TabStopType.RIGHT, position: TabStopPosition.MAX }],
})
// Dot leader (e.g., TOC-style)
new Paragraph({
children: [
new TextRun("Introduction"),
new TextRun({ children: [
new PositionalTab({
alignment: PositionalTabAlignment.RIGHT,
relativeTo: PositionalTabRelativeTo.MARGIN,
leader: PositionalTabLeader.DOT,
}),
"3",
]}),
],
})
```
### Multi-Column Layouts
```javascript
// Equal-width columns
sections: [{
properties: {
column: {
count: 2, // number of columns
space: 720, // gap between columns in DXA (720 = 0.5 inch)
equalWidth: true,
separate: true, // vertical line between columns
},
},
children: [/* content flows naturally across columns */]
}]
// Custom-width columns (equalWidth must be false)
sections: [{
properties: {
column: {
equalWidth: false,
children: [
new Column({ width: 5400, space: 720 }),
new Column({ width: 3240 }),
],
},
},
children: [/* content */]
}]
```
Force a column break with a new section using `type: SectionType.NEXT_COLUMN`.
### Table of Contents
```javascript
// CRITICAL: Headings must use HeadingLevel ONLY - no custom styles
new TableOfContents("Table of Contents", { hyperlink: true, headingStyleRange: "1-3" })
```
### Headers/Footers
```javascript
sections: [{
properties: {
page: { margin: { top: 1440, right: 1440, bottom: 1440, left: 1440 } } // 1440 = 1 inch
},
headers: {
default: new Header({ children: [new Paragraph({ children: [new TextRun("Header")] })] })
},
footers: {
default: new Footer({ children: [new Paragraph({
children: [new TextRun("Page "), new TextRun({ children: [PageNumber.CURRENT] })]
})] })
},
children: [/* content */]
}]
```
### Critical Rules for docx-js
- **Set page size explicitly** - docx-js defaults to A4; use US Letter (12240 x 15840 DXA) for US documents
- **Landscape: pass portrait dimensions** - docx-js swaps width/height internally; pass short edge as `width`, long edge as `height`, and set `orientation: PageOrientation.LANDSCAPE`
- **Never use `\n`** - use separate Paragraph elements
- **Never use unicode bullets** - use `LevelFormat.BULLET` with numbering config
- **PageBreak must be in Paragraph** - standalone creates invalid XML
- **ImageRun requires `type`** - always specify png/jpg/etc
- **Always set table `width` with DXA** - never use `WidthType.PERCENTAGE` (breaks in Google Docs)
- **Tables need dual widths** - `columnWidths` array AND cell `width`, both must match
- **Table width = sum of columnWidths** - for DXA, ensure they add up exactly
- **Always add cell margins** - use `margins: { top: 80, bottom: 80, left: 120, right: 120 }` for readable padding
- **Use `ShadingType.CLEAR`** - never SOLID for table shading
- **Never use tables as dividers/rules** - cells have minimum height and render as empty boxes (including in headers/footers); use `border: { bottom: { style: BorderStyle.SINGLE, size: 6, color: "2E75B6", space: 1 } }` on a Paragraph instead. For two-column footers, use tab stops (see Tab Stops section), not tables
- **TOC requires HeadingLevel only** - no custom styles on heading paragraphs
- **Override built-in styles** - use exact IDs: "Heading1", "Heading2", etc.
- **Include `outlineLevel`** - required for TOC (0 for H1, 1 for H2, etc.)
---
## Editing Existing Documents
**Follow all 3 steps in order.**
### Step 1: Unpack
```bash
python scripts/office/unpack.py document.docx unpacked/
```
Extracts XML, pretty-prints, merges adjacent runs, and converts smart quotes to XML entities (`“` etc.) so they survive editing. Use `--merge-runs false` to skip run merging.
### Step 2: Edit XML
Edit files in `unpacked/word/`. See XML Reference below for patterns.
**Use "Claude" as the author** for tracked changes and comments, unless the user explicitly requests use of a different name.
**Use the Edit tool directly for string replacement. Do not write Python scripts.** Scripts introduce unnecessary complexity. The Edit tool shows exactly what is being replaced.
**CRITICAL: Use smart quotes for new content.** When adding text with apostrophes or quotes, use XML entities to produce smart quotes:
```xml
Here’s a quote: “Hello”
```
| Entity | Character |
|--------|-----------|
| `‘` | ' (left single) |
| `’` | ' (right single / apostrophe) |
| `“` | " (left double) |
| `”` | " (right double) |
**Adding comments:** Use `comment.py` to handle boilerplate across multiple XML files (text must be pre-escaped XML):
```bash
python scripts/comment.py unpacked/ 0 "Comment text with & and ’"
python scripts/comment.py unpacked/ 1 "Reply text" --parent 0 # reply to comment 0
python scripts/comment.py unpacked/ 0 "Text" --author "Custom Author" # custom author name
```
Then add markers to document.xml (see Comments in XML Reference).
### Step 3: Pack
```bash
python scripts/office/pack.py unpacked/ output.docx --original document.docx
```
Validates with auto-repair, condenses XML, and creates DOCX. Use `--validate false` to skip.
**Auto-repair will fix:**
- `durableId` >= 0x7FFFFFFF (regenerates valid ID)
- Missing `xml:space="preserve"` on `<w:t>` with whitespace
**Auto-repair won't fix:**
- Malformed XML, invalid element nesting, missing relationships, schema violations
### Common Pitfalls
- **Replace entire `<w:r>` elements**: When adding tracked changes, replace the whole `<w:r>...</w:r>` block with `<w:del>...<w:ins>...` as siblings. Don't inject tracked change tags inside a run.
- **Preserve `<w:rPr>` formatting**: Copy the original run's `<w:rPr>` block into your tracked change runs to maintain bold, font size, etc.
---
## XML Reference
### Schema Compliance
- **Element order in `<w:pPr>`**: `<w:pStyle>`, `<w:numPr>`, `<w:spacing>`, `<w:ind>`, `<w:jc>`, `<w:rPr>` last
- **Whitespace**: Add `xml:space="preserve"` to `<w:t>` with leading/trailing spaces
- **RSIDs**: Must be 8-digit hex (e.g., `00AB1234`)
### Tracked Changes
**Insertion:**
```xml
inserted text
```
**Deletion:**
```xml
deleted text
```
**Inside `<w:del>`**: Use `<w:delText>` instead of `<w:t>`, and `<w:delInstrText>` instead of `<w:instrText>`.
**Minimal edits** - only mark what changes:
```xml
The term is 3060 days.
```
**Deleting entire paragraphs/list items** - when removing ALL content from a paragraph, also mark the paragraph mark as deleted so it merges with the next paragraph. Add `<w:del/>` inside `<w:pPr><w:rPr>`:
```xml
...Entire paragraph content being deleted...
```
Without the `<w:del/>` in `<w:pPr><w:rPr>`, accepting changes leaves an empty paragraph/list item.
**Rejecting another author's insertion** - nest deletion inside their insertion:
```xml
their inserted text
```
**Restoring another author's deletion** - add insertion after (don't modify their deletion):
```xml
deleted textdeleted text
```
### Comments
After running `comment.py` (see Step 2), add markers to document.xml. For replies, use `--parent` flag and nest markers inside the parent's.
**CRITICAL: `<w:commentRangeStart>` and `<w:commentRangeEnd>` are siblings of `<w:r>`, never inside `<w:r>`.**
```xml
deleted more texttext
```
### Images
1. Add image file to `word/media/`
2. Add relationship to `word/_rels/document.xml.rels`:
```xml
```
3. Add content type to `[Content_Types].xml`:
```xml
```
4. Reference in document.xml:
```xml
```
---
## Dependencies
- **pandoc**: Text extraction
- **docx**: `npm install -g docx` (new documents)
- **LibreOffice**: PDF conversion (auto-configured for sandboxed environments via `scripts/office/soffice.py`)
- **Poppler**: `pdftoppm` for images
## Resource Files
### LICENSE.txt
[Download LICENSE.txt](/skills/docx/LICENSE.txt)
_Binary resource_
### scripts/__init__.py
[Download scripts/__init__.py](/skills/docx/scripts/__init__.py)
```python
```
### scripts/accept_changes.py
[Download scripts/accept_changes.py](/skills/docx/scripts/accept_changes.py)
```python
"""Accept all tracked changes in a DOCX file using LibreOffice.
Requires LibreOffice (soffice) to be installed.
"""
import argparse
import logging
import shutil
import subprocess
from pathlib import Path
from office.soffice import get_soffice_env
logger = logging.getLogger(__name__)
LIBREOFFICE_PROFILE = "/tmp/libreoffice_docx_profile"
MACRO_DIR = f"{LIBREOFFICE_PROFILE}/user/basic/Standard"
ACCEPT_CHANGES_MACRO = """
Sub AcceptAllTrackedChanges()
Dim document As Object
Dim dispatcher As Object
document = ThisComponent.CurrentController.Frame
dispatcher = createUnoService("com.sun.star.frame.DispatchHelper")
dispatcher.executeDispatch(document, ".uno:AcceptAllTrackedChanges", "", 0, Array())
ThisComponent.store()
ThisComponent.close(True)
End Sub
"""
def accept_changes(
input_file: str,
output_file: str,
) -> tuple[None, str]:
input_path = Path(input_file)
output_path = Path(output_file)
if not input_path.exists():
return None, f"Error: Input file not found: {input_file}"
if not input_path.suffix.lower() == ".docx":
return None, f"Error: Input file is not a DOCX file: {input_file}"
try:
output_path.parent.mkdir(parents=True, exist_ok=True)
shutil.copy2(input_path, output_path)
except Exception as e:
return None, f"Error: Failed to copy input file to output location: {e}"
if not _setup_libreoffice_macro():
return None, "Error: Failed to setup LibreOffice macro"
cmd = [
"soffice",
"--headless",
f"-env:UserInstallation=file://{LIBREOFFICE_PROFILE}",
"--norestore",
"vnd.sun.star.script:Standard.Module1.AcceptAllTrackedChanges?language=Basic&location=application",
str(output_path.absolute()),
]
try:
result = subprocess.run(
cmd,
capture_output=True,
text=True,
timeout=30,
check=False,
env=get_soffice_env(),
)
except subprocess.TimeoutExpired:
return (
None,
f"Successfully accepted all tracked changes: {input_file} -> {output_file}",
)
if result.returncode != 0:
return None, f"Error: LibreOffice failed: {result.stderr}"
return (
None,
f"Successfully accepted all tracked changes: {input_file} -> {output_file}",
)
def _setup_libreoffice_macro() -> bool:
macro_dir = Path(MACRO_DIR)
macro_file = macro_dir / "Module1.xba"
if macro_file.exists() and "AcceptAllTrackedChanges" in macro_file.read_text():
return True
if not macro_dir.exists():
subprocess.run(
[
"soffice",
"--headless",
f"-env:UserInstallation=file://{LIBREOFFICE_PROFILE}",
"--terminate_after_init",
],
capture_output=True,
timeout=10,
check=False,
env=get_soffice_env(),
)
macro_dir.mkdir(parents=True, exist_ok=True)
try:
macro_file.write_text(ACCEPT_CHANGES_MACRO)
return True
except Exception as e:
logger.warning(f"Failed to setup LibreOffice macro: {e}")
return False
if __name__ == "__main__":
parser = argparse.ArgumentParser(
description="Accept all tracked changes in a DOCX file"
)
parser.add_argument("input_file", help="Input DOCX file with tracked changes")
parser.add_argument(
"output_file", help="Output DOCX file (clean, no tracked changes)"
)
args = parser.parse_args()
_, message = accept_changes(args.input_file, args.output_file)
print(message)
if "Error" in message:
raise SystemExit(1)
```
### scripts/comment.py
[Download scripts/comment.py](/skills/docx/scripts/comment.py)
_Binary resource_
### scripts/office/helpers/__init__.py
[Download scripts/office/helpers/__init__.py](/skills/docx/scripts/office/helpers/__init__.py)
_Binary resource_
### scripts/office/helpers/merge_runs.py
[Download scripts/office/helpers/merge_runs.py](/skills/docx/scripts/office/helpers/merge_runs.py)
```python
"""Merge adjacent runs with identical formatting in DOCX.
Merges adjacent elements that have identical properties.
Works on runs in paragraphs and inside tracked changes (, ).
Also:
- Removes rsid attributes from runs (revision metadata that doesn't affect rendering)
- Removes proofErr elements (spell/grammar markers that block merging)
"""
from pathlib import Path
import defusedxml.minidom
def merge_runs(input_dir: str) -> tuple[int, str]:
doc_xml = Path(input_dir) / "word" / "document.xml"
if not doc_xml.exists():
return 0, f"Error: {doc_xml} not found"
try:
dom = defusedxml.minidom.parseString(doc_xml.read_text(encoding="utf-8"))
root = dom.documentElement
_remove_elements(root, "proofErr")
_strip_run_rsid_attrs(root)
containers = {run.parentNode for run in _find_elements(root, "r")}
merge_count = 0
for container in containers:
merge_count += _merge_runs_in(container)
doc_xml.write_bytes(dom.toxml(encoding="UTF-8"))
return merge_count, f"Merged {merge_count} runs"
except Exception as e:
return 0, f"Error: {e}"
def _find_elements(root, tag: str) -> list:
results = []
def traverse(node):
if node.nodeType == node.ELEMENT_NODE:
name = node.localName or node.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(node)
for child in node.childNodes:
traverse(child)
traverse(root)
return results
def _get_child(parent, tag: str):
for child in parent.childNodes:
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name == tag or name.endswith(f":{tag}"):
return child
return None
def _get_children(parent, tag: str) -> list:
results = []
for child in parent.childNodes:
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(child)
return results
def _is_adjacent(elem1, elem2) -> bool:
node = elem1.nextSibling
while node:
if node == elem2:
return True
if node.nodeType == node.ELEMENT_NODE:
return False
if node.nodeType == node.TEXT_NODE and node.data.strip():
return False
node = node.nextSibling
return False
def _remove_elements(root, tag: str):
for elem in _find_elements(root, tag):
if elem.parentNode:
elem.parentNode.removeChild(elem)
def _strip_run_rsid_attrs(root):
for run in _find_elements(root, "r"):
for attr in list(run.attributes.values()):
if "rsid" in attr.name.lower():
run.removeAttribute(attr.name)
def _merge_runs_in(container) -> int:
merge_count = 0
run = _first_child_run(container)
while run:
while True:
next_elem = _next_element_sibling(run)
if next_elem and _is_run(next_elem) and _can_merge(run, next_elem):
_merge_run_content(run, next_elem)
container.removeChild(next_elem)
merge_count += 1
else:
break
_consolidate_text(run)
run = _next_sibling_run(run)
return merge_count
def _first_child_run(container):
for child in container.childNodes:
if child.nodeType == child.ELEMENT_NODE and _is_run(child):
return child
return None
def _next_element_sibling(node):
sibling = node.nextSibling
while sibling:
if sibling.nodeType == sibling.ELEMENT_NODE:
return sibling
sibling = sibling.nextSibling
return None
def _next_sibling_run(node):
sibling = node.nextSibling
while sibling:
if sibling.nodeType == sibling.ELEMENT_NODE:
if _is_run(sibling):
return sibling
sibling = sibling.nextSibling
return None
def _is_run(node) -> bool:
name = node.localName or node.tagName
return name == "r" or name.endswith(":r")
def _can_merge(run1, run2) -> bool:
rpr1 = _get_child(run1, "rPr")
rpr2 = _get_child(run2, "rPr")
if (rpr1 is None) != (rpr2 is None):
return False
if rpr1 is None:
return True
return rpr1.toxml() == rpr2.toxml()
def _merge_run_content(target, source):
for child in list(source.childNodes):
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name != "rPr" and not name.endswith(":rPr"):
target.appendChild(child)
def _consolidate_text(run):
t_elements = _get_children(run, "t")
for i in range(len(t_elements) - 1, 0, -1):
curr, prev = t_elements[i], t_elements[i - 1]
if _is_adjacent(prev, curr):
prev_text = prev.firstChild.data if prev.firstChild else ""
curr_text = curr.firstChild.data if curr.firstChild else ""
merged = prev_text + curr_text
if prev.firstChild:
prev.firstChild.data = merged
else:
prev.appendChild(run.ownerDocument.createTextNode(merged))
if merged.startswith(" ") or merged.endswith(" "):
prev.setAttribute("xml:space", "preserve")
elif prev.hasAttribute("xml:space"):
prev.removeAttribute("xml:space")
run.removeChild(curr)
```
### scripts/office/helpers/simplify_redlines.py
[Download scripts/office/helpers/simplify_redlines.py](/skills/docx/scripts/office/helpers/simplify_redlines.py)
```python
"""Simplify tracked changes by merging adjacent w:ins or w:del elements.
Merges adjacent elements from the same author into a single element.
Same for elements. This makes heavily-redlined documents easier to
work with by reducing the number of tracked change wrappers.
Rules:
- Only merges w:ins with w:ins, w:del with w:del (same element type)
- Only merges if same author (ignores timestamp differences)
- Only merges if truly adjacent (only whitespace between them)
"""
import xml.etree.ElementTree as ET
import zipfile
from pathlib import Path
import defusedxml.minidom
WORD_NS = "http://schemas.openxmlformats.org/wordprocessingml/2006/main"
def simplify_redlines(input_dir: str) -> tuple[int, str]:
doc_xml = Path(input_dir) / "word" / "document.xml"
if not doc_xml.exists():
return 0, f"Error: {doc_xml} not found"
try:
dom = defusedxml.minidom.parseString(doc_xml.read_text(encoding="utf-8"))
root = dom.documentElement
merge_count = 0
containers = _find_elements(root, "p") + _find_elements(root, "tc")
for container in containers:
merge_count += _merge_tracked_changes_in(container, "ins")
merge_count += _merge_tracked_changes_in(container, "del")
doc_xml.write_bytes(dom.toxml(encoding="UTF-8"))
return merge_count, f"Simplified {merge_count} tracked changes"
except Exception as e:
return 0, f"Error: {e}"
def _merge_tracked_changes_in(container, tag: str) -> int:
merge_count = 0
tracked = [
child
for child in container.childNodes
if child.nodeType == child.ELEMENT_NODE and _is_element(child, tag)
]
if len(tracked) < 2:
return 0
i = 0
while i < len(tracked) - 1:
curr = tracked[i]
next_elem = tracked[i + 1]
if _can_merge_tracked(curr, next_elem):
_merge_tracked_content(curr, next_elem)
container.removeChild(next_elem)
tracked.pop(i + 1)
merge_count += 1
else:
i += 1
return merge_count
def _is_element(node, tag: str) -> bool:
name = node.localName or node.tagName
return name == tag or name.endswith(f":{tag}")
def _get_author(elem) -> str:
author = elem.getAttribute("w:author")
if not author:
for attr in elem.attributes.values():
if attr.localName == "author" or attr.name.endswith(":author"):
return attr.value
return author
def _can_merge_tracked(elem1, elem2) -> bool:
if _get_author(elem1) != _get_author(elem2):
return False
node = elem1.nextSibling
while node and node != elem2:
if node.nodeType == node.ELEMENT_NODE:
return False
if node.nodeType == node.TEXT_NODE and node.data.strip():
return False
node = node.nextSibling
return True
def _merge_tracked_content(target, source):
while source.firstChild:
child = source.firstChild
source.removeChild(child)
target.appendChild(child)
def _find_elements(root, tag: str) -> list:
results = []
def traverse(node):
if node.nodeType == node.ELEMENT_NODE:
name = node.localName or node.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(node)
for child in node.childNodes:
traverse(child)
traverse(root)
return results
def get_tracked_change_authors(doc_xml_path: Path) -> dict[str, int]:
if not doc_xml_path.exists():
return {}
try:
tree = ET.parse(doc_xml_path)
root = tree.getroot()
except ET.ParseError:
return {}
namespaces = {"w": WORD_NS}
author_attr = f"{{{WORD_NS}}}author"
authors: dict[str, int] = {}
for tag in ["ins", "del"]:
for elem in root.findall(f".//w:{tag}", namespaces):
author = elem.get(author_attr)
if author:
authors[author] = authors.get(author, 0) + 1
return authors
def _get_authors_from_docx(docx_path: Path) -> dict[str, int]:
try:
with zipfile.ZipFile(docx_path, "r") as zf:
if "word/document.xml" not in zf.namelist():
return {}
with zf.open("word/document.xml") as f:
tree = ET.parse(f)
root = tree.getroot()
namespaces = {"w": WORD_NS}
author_attr = f"{{{WORD_NS}}}author"
authors: dict[str, int] = {}
for tag in ["ins", "del"]:
for elem in root.findall(f".//w:{tag}", namespaces):
author = elem.get(author_attr)
if author:
authors[author] = authors.get(author, 0) + 1
return authors
except (zipfile.BadZipFile, ET.ParseError):
return {}
def infer_author(modified_dir: Path, original_docx: Path, default: str = "Claude") -> str:
modified_xml = modified_dir / "word" / "document.xml"
modified_authors = get_tracked_change_authors(modified_xml)
if not modified_authors:
return default
original_authors = _get_authors_from_docx(original_docx)
new_changes: dict[str, int] = {}
for author, count in modified_authors.items():
original_count = original_authors.get(author, 0)
diff = count - original_count
if diff > 0:
new_changes[author] = diff
if not new_changes:
return default
if len(new_changes) == 1:
return next(iter(new_changes))
raise ValueError(
f"Multiple authors added new changes: {new_changes}. "
"Cannot infer which author to validate."
)
```
### scripts/office/pack.py
[Download scripts/office/pack.py](/skills/docx/scripts/office/pack.py)
```python
"""Pack a directory into a DOCX, PPTX, or XLSX file.
Validates with auto-repair, condenses XML formatting, and creates the Office file.
Usage:
python pack.py [--original ] [--validate true|false]
Examples:
python pack.py unpacked/ output.docx --original input.docx
python pack.py unpacked/ output.pptx --validate false
"""
import argparse
import sys
import shutil
import tempfile
import zipfile
from pathlib import Path
import defusedxml.minidom
from validators import DOCXSchemaValidator, PPTXSchemaValidator, RedliningValidator
def pack(
input_directory: str,
output_file: str,
original_file: str | None = None,
validate: bool = True,
infer_author_func=None,
) -> tuple[None, str]:
input_dir = Path(input_directory)
output_path = Path(output_file)
suffix = output_path.suffix.lower()
if not input_dir.is_dir():
return None, f"Error: {input_dir} is not a directory"
if suffix not in {".docx", ".pptx", ".xlsx"}:
return None, f"Error: {output_file} must be a .docx, .pptx, or .xlsx file"
if validate and original_file:
original_path = Path(original_file)
if original_path.exists():
success, output = _run_validation(
input_dir, original_path, suffix, infer_author_func
)
if output:
print(output)
if not success:
return None, f"Error: Validation failed for {input_dir}"
with tempfile.TemporaryDirectory() as temp_dir:
temp_content_dir = Path(temp_dir) / "content"
shutil.copytree(input_dir, temp_content_dir)
for pattern in ["*.xml", "*.rels"]:
for xml_file in temp_content_dir.rglob(pattern):
_condense_xml(xml_file)
output_path.parent.mkdir(parents=True, exist_ok=True)
with zipfile.ZipFile(output_path, "w", zipfile.ZIP_DEFLATED) as zf:
for f in temp_content_dir.rglob("*"):
if f.is_file():
zf.write(f, f.relative_to(temp_content_dir))
return None, f"Successfully packed {input_dir} to {output_file}"
def _run_validation(
unpacked_dir: Path,
original_file: Path,
suffix: str,
infer_author_func=None,
) -> tuple[bool, str | None]:
output_lines = []
validators = []
if suffix == ".docx":
author = "Claude"
if infer_author_func:
try:
author = infer_author_func(unpacked_dir, original_file)
except ValueError as e:
print(f"Warning: {e} Using default author 'Claude'.", file=sys.stderr)
validators = [
DOCXSchemaValidator(unpacked_dir, original_file),
RedliningValidator(unpacked_dir, original_file, author=author),
]
elif suffix == ".pptx":
validators = [PPTXSchemaValidator(unpacked_dir, original_file)]
if not validators:
return True, None
total_repairs = sum(v.repair() for v in validators)
if total_repairs:
output_lines.append(f"Auto-repaired {total_repairs} issue(s)")
success = all(v.validate() for v in validators)
if success:
output_lines.append("All validations PASSED!")
return success, "\n".join(output_lines) if output_lines else None
def _condense_xml(xml_file: Path) -> None:
try:
with open(xml_file, encoding="utf-8") as f:
dom = defusedxml.minidom.parse(f)
for element in dom.getElementsByTagName("*"):
if element.tagName.endswith(":t"):
continue
for child in list(element.childNodes):
if (
child.nodeType == child.TEXT_NODE
and child.nodeValue
and child.nodeValue.strip() == ""
) or child.nodeType == child.COMMENT_NODE:
element.removeChild(child)
xml_file.write_bytes(dom.toxml(encoding="UTF-8"))
except Exception as e:
print(f"ERROR: Failed to parse {xml_file.name}: {e}", file=sys.stderr)
raise
if __name__ == "__main__":
parser = argparse.ArgumentParser(
description="Pack a directory into a DOCX, PPTX, or XLSX file"
)
parser.add_argument("input_directory", help="Unpacked Office document directory")
parser.add_argument("output_file", help="Output Office file (.docx/.pptx/.xlsx)")
parser.add_argument(
"--original",
help="Original file for validation comparison",
)
parser.add_argument(
"--validate",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Run validation with auto-repair (default: true)",
)
args = parser.parse_args()
_, message = pack(
args.input_directory,
args.output_file,
original_file=args.original,
validate=args.validate,
)
print(message)
if "Error" in message:
sys.exit(1)
```
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd](/skills/docx/scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd](/skills/docx/scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd](/skills/docx/scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd](/skills/docx/scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd](/skills/docx/scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd)
_Binary resource_
### scripts/office/schemas/mce/mc.xsd
[Download scripts/office/schemas/mce/mc.xsd](/skills/docx/scripts/office/schemas/mce/mc.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2010.xsd
[Download scripts/office/schemas/microsoft/wml-2010.xsd](/skills/docx/scripts/office/schemas/microsoft/wml-2010.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2012.xsd
[Download scripts/office/schemas/microsoft/wml-2012.xsd](/skills/docx/scripts/office/schemas/microsoft/wml-2012.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2018.xsd
[Download scripts/office/schemas/microsoft/wml-2018.xsd](/skills/docx/scripts/office/schemas/microsoft/wml-2018.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-cex-2018.xsd
[Download scripts/office/schemas/microsoft/wml-cex-2018.xsd](/skills/docx/scripts/office/schemas/microsoft/wml-cex-2018.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-cid-2016.xsd
[Download scripts/office/schemas/microsoft/wml-cid-2016.xsd](/skills/docx/scripts/office/schemas/microsoft/wml-cid-2016.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd
[Download scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd](/skills/docx/scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-symex-2015.xsd
[Download scripts/office/schemas/microsoft/wml-symex-2015.xsd](/skills/docx/scripts/office/schemas/microsoft/wml-symex-2015.xsd)
_Binary resource_
### scripts/office/soffice.py
[Download scripts/office/soffice.py](/skills/docx/scripts/office/soffice.py)
```python
"""
Helper for running LibreOffice (soffice) in environments where AF_UNIX
sockets may be blocked (e.g., sandboxed VMs). Detects the restriction
at runtime and applies an LD_PRELOAD shim if needed.
Usage:
from office.soffice import run_soffice, get_soffice_env
# Option 1 – run soffice directly
result = run_soffice(["--headless", "--convert-to", "pdf", "input.docx"])
# Option 2 – get env dict for your own subprocess calls
env = get_soffice_env()
subprocess.run(["soffice", ...], env=env)
"""
import os
import socket
import subprocess
import tempfile
from pathlib import Path
def get_soffice_env() -> dict:
env = os.environ.copy()
env["SAL_USE_VCLPLUGIN"] = "svp"
if _needs_shim():
shim = _ensure_shim()
env["LD_PRELOAD"] = str(shim)
return env
def run_soffice(args: list[str], **kwargs) -> subprocess.CompletedProcess:
env = get_soffice_env()
return subprocess.run(["soffice"] + args, env=env, **kwargs)
_SHIM_SO = Path(tempfile.gettempdir()) / "lo_socket_shim.so"
def _needs_shim() -> bool:
try:
s = socket.socket(socket.AF_UNIX, socket.SOCK_STREAM)
s.close()
return False
except OSError:
return True
def _ensure_shim() -> Path:
if _SHIM_SO.exists():
return _SHIM_SO
src = Path(tempfile.gettempdir()) / "lo_socket_shim.c"
src.write_text(_SHIM_SOURCE)
subprocess.run(
["gcc", "-shared", "-fPIC", "-o", str(_SHIM_SO), str(src), "-ldl"],
check=True,
capture_output=True,
)
src.unlink()
return _SHIM_SO
_SHIM_SOURCE = r"""
#define _GNU_SOURCE
#include
#include
#include
#include
#include
#include
#include
static int (*real_socket)(int, int, int);
static int (*real_socketpair)(int, int, int, int[2]);
static int (*real_listen)(int, int);
static int (*real_accept)(int, struct sockaddr *, socklen_t *);
static int (*real_close)(int);
static int (*real_read)(int, void *, size_t);
/* Per-FD bookkeeping (FDs >= 1024 are passed through unshimmed). */
static int is_shimmed[1024];
static int peer_of[1024];
static int wake_r[1024]; /* accept() blocks reading this */
static int wake_w[1024]; /* close() writes to this */
static int listener_fd = -1; /* FD that received listen() */
__attribute__((constructor))
static void init(void) {
real_socket = dlsym(RTLD_NEXT, "socket");
real_socketpair = dlsym(RTLD_NEXT, "socketpair");
real_listen = dlsym(RTLD_NEXT, "listen");
real_accept = dlsym(RTLD_NEXT, "accept");
real_close = dlsym(RTLD_NEXT, "close");
real_read = dlsym(RTLD_NEXT, "read");
for (int i = 0; i < 1024; i++) {
peer_of[i] = -1;
wake_r[i] = -1;
wake_w[i] = -1;
}
}
/* ---- socket ---------------------------------------------------------- */
int socket(int domain, int type, int protocol) {
if (domain == AF_UNIX) {
int fd = real_socket(domain, type, protocol);
if (fd >= 0) return fd;
/* socket(AF_UNIX) blocked – fall back to socketpair(). */
int sv[2];
if (real_socketpair(domain, type, protocol, sv) == 0) {
if (sv[0] >= 0 && sv[0] < 1024) {
is_shimmed[sv[0]] = 1;
peer_of[sv[0]] = sv[1];
int wp[2];
if (pipe(wp) == 0) {
wake_r[sv[0]] = wp[0];
wake_w[sv[0]] = wp[1];
}
}
return sv[0];
}
errno = EPERM;
return -1;
}
return real_socket(domain, type, protocol);
}
/* ---- listen ---------------------------------------------------------- */
int listen(int sockfd, int backlog) {
if (sockfd >= 0 && sockfd < 1024 && is_shimmed[sockfd]) {
listener_fd = sockfd;
return 0;
}
return real_listen(sockfd, backlog);
}
/* ---- accept ---------------------------------------------------------- */
int accept(int sockfd, struct sockaddr *addr, socklen_t *addrlen) {
if (sockfd >= 0 && sockfd < 1024 && is_shimmed[sockfd]) {
/* Block until close() writes to the wake pipe. */
if (wake_r[sockfd] >= 0) {
char buf;
real_read(wake_r[sockfd], &buf, 1);
}
errno = ECONNABORTED;
return -1;
}
return real_accept(sockfd, addr, addrlen);
}
/* ---- close ----------------------------------------------------------- */
int close(int fd) {
if (fd >= 0 && fd < 1024 && is_shimmed[fd]) {
int was_listener = (fd == listener_fd);
is_shimmed[fd] = 0;
if (wake_w[fd] >= 0) { /* unblock accept() */
char c = 0;
write(wake_w[fd], &c, 1);
real_close(wake_w[fd]);
wake_w[fd] = -1;
}
if (wake_r[fd] >= 0) { real_close(wake_r[fd]); wake_r[fd] = -1; }
if (peer_of[fd] >= 0) { real_close(peer_of[fd]); peer_of[fd] = -1; }
if (was_listener)
_exit(0); /* conversion done – exit */
}
return real_close(fd);
}
"""
if __name__ == "__main__":
import sys
result = run_soffice(sys.argv[1:])
sys.exit(result.returncode)
```
### scripts/office/unpack.py
[Download scripts/office/unpack.py](/skills/docx/scripts/office/unpack.py)
```python
"""Unpack Office files (DOCX, PPTX, XLSX) for editing.
Extracts the ZIP archive, pretty-prints XML files, and optionally:
- Merges adjacent runs with identical formatting (DOCX only)
- Simplifies adjacent tracked changes from same author (DOCX only)
Usage:
python unpack.py [options]
Examples:
python unpack.py document.docx unpacked/
python unpack.py presentation.pptx unpacked/
python unpack.py document.docx unpacked/ --merge-runs false
"""
import argparse
import sys
import zipfile
from pathlib import Path
import defusedxml.minidom
from helpers.merge_runs import merge_runs as do_merge_runs
from helpers.simplify_redlines import simplify_redlines as do_simplify_redlines
SMART_QUOTE_REPLACEMENTS = {
"\u201c": "“",
"\u201d": "”",
"\u2018": "‘",
"\u2019": "’",
}
def unpack(
input_file: str,
output_directory: str,
merge_runs: bool = True,
simplify_redlines: bool = True,
) -> tuple[None, str]:
input_path = Path(input_file)
output_path = Path(output_directory)
suffix = input_path.suffix.lower()
if not input_path.exists():
return None, f"Error: {input_file} does not exist"
if suffix not in {".docx", ".pptx", ".xlsx"}:
return None, f"Error: {input_file} must be a .docx, .pptx, or .xlsx file"
try:
output_path.mkdir(parents=True, exist_ok=True)
with zipfile.ZipFile(input_path, "r") as zf:
zf.extractall(output_path)
xml_files = list(output_path.rglob("*.xml")) + list(output_path.rglob("*.rels"))
for xml_file in xml_files:
_pretty_print_xml(xml_file)
message = f"Unpacked {input_file} ({len(xml_files)} XML files)"
if suffix == ".docx":
if simplify_redlines:
simplify_count, _ = do_simplify_redlines(str(output_path))
message += f", simplified {simplify_count} tracked changes"
if merge_runs:
merge_count, _ = do_merge_runs(str(output_path))
message += f", merged {merge_count} runs"
for xml_file in xml_files:
_escape_smart_quotes(xml_file)
return None, message
except zipfile.BadZipFile:
return None, f"Error: {input_file} is not a valid Office file"
except Exception as e:
return None, f"Error unpacking: {e}"
def _pretty_print_xml(xml_file: Path) -> None:
try:
content = xml_file.read_text(encoding="utf-8")
dom = defusedxml.minidom.parseString(content)
xml_file.write_bytes(dom.toprettyxml(indent=" ", encoding="utf-8"))
except Exception:
pass
def _escape_smart_quotes(xml_file: Path) -> None:
try:
content = xml_file.read_text(encoding="utf-8")
for char, entity in SMART_QUOTE_REPLACEMENTS.items():
content = content.replace(char, entity)
xml_file.write_text(content, encoding="utf-8")
except Exception:
pass
if __name__ == "__main__":
parser = argparse.ArgumentParser(
description="Unpack an Office file (DOCX, PPTX, XLSX) for editing"
)
parser.add_argument("input_file", help="Office file to unpack")
parser.add_argument("output_directory", help="Output directory")
parser.add_argument(
"--merge-runs",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Merge adjacent runs with identical formatting (DOCX only, default: true)",
)
parser.add_argument(
"--simplify-redlines",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Merge adjacent tracked changes from same author (DOCX only, default: true)",
)
args = parser.parse_args()
_, message = unpack(
args.input_file,
args.output_directory,
merge_runs=args.merge_runs,
simplify_redlines=args.simplify_redlines,
)
print(message)
if "Error" in message:
sys.exit(1)
```
### scripts/office/validate.py
[Download scripts/office/validate.py](/skills/docx/scripts/office/validate.py)
```python
"""
Command line tool to validate Office document XML files against XSD schemas and tracked changes.
Usage:
python validate.py [--original ] [--auto-repair] [--author NAME]
The first argument can be either:
- An unpacked directory containing the Office document XML files
- A packed Office file (.docx/.pptx/.xlsx) which will be unpacked to a temp directory
Auto-repair fixes:
- paraId/durableId values that exceed OOXML limits
- Missing xml:space="preserve" on w:t elements with whitespace
"""
import argparse
import sys
import tempfile
import zipfile
from pathlib import Path
from validators import DOCXSchemaValidator, PPTXSchemaValidator, RedliningValidator
def main():
parser = argparse.ArgumentParser(description="Validate Office document XML files")
parser.add_argument(
"path",
help="Path to unpacked directory or packed Office file (.docx/.pptx/.xlsx)",
)
parser.add_argument(
"--original",
required=False,
default=None,
help="Path to original file (.docx/.pptx/.xlsx). If omitted, all XSD errors are reported and redlining validation is skipped.",
)
parser.add_argument(
"-v",
"--verbose",
action="store_true",
help="Enable verbose output",
)
parser.add_argument(
"--auto-repair",
action="store_true",
help="Automatically repair common issues (hex IDs, whitespace preservation)",
)
parser.add_argument(
"--author",
default="Claude",
help="Author name for redlining validation (default: Claude)",
)
args = parser.parse_args()
path = Path(args.path)
assert path.exists(), f"Error: {path} does not exist"
original_file = None
if args.original:
original_file = Path(args.original)
assert original_file.is_file(), f"Error: {original_file} is not a file"
assert original_file.suffix.lower() in [".docx", ".pptx", ".xlsx"], (
f"Error: {original_file} must be a .docx, .pptx, or .xlsx file"
)
file_extension = (original_file or path).suffix.lower()
assert file_extension in [".docx", ".pptx", ".xlsx"], (
f"Error: Cannot determine file type from {path}. Use --original or provide a .docx/.pptx/.xlsx file."
)
if path.is_file() and path.suffix.lower() in [".docx", ".pptx", ".xlsx"]:
temp_dir = tempfile.mkdtemp()
with zipfile.ZipFile(path, "r") as zf:
zf.extractall(temp_dir)
unpacked_dir = Path(temp_dir)
else:
assert path.is_dir(), f"Error: {path} is not a directory or Office file"
unpacked_dir = path
match file_extension:
case ".docx":
validators = [
DOCXSchemaValidator(unpacked_dir, original_file, verbose=args.verbose),
]
if original_file:
validators.append(
RedliningValidator(unpacked_dir, original_file, verbose=args.verbose, author=args.author)
)
case ".pptx":
validators = [
PPTXSchemaValidator(unpacked_dir, original_file, verbose=args.verbose),
]
case _:
print(f"Error: Validation not supported for file type {file_extension}")
sys.exit(1)
if args.auto_repair:
total_repairs = sum(v.repair() for v in validators)
if total_repairs:
print(f"Auto-repaired {total_repairs} issue(s)")
success = all(v.validate() for v in validators)
if success:
print("All validations PASSED!")
sys.exit(0 if success else 1)
if __name__ == "__main__":
main()
```
### scripts/office/validators/__init__.py
[Download scripts/office/validators/__init__.py](/skills/docx/scripts/office/validators/__init__.py)
```python
"""
Validation modules for Word document processing.
"""
from .base import BaseSchemaValidator
from .docx import DOCXSchemaValidator
from .pptx import PPTXSchemaValidator
from .redlining import RedliningValidator
__all__ = [
"BaseSchemaValidator",
"DOCXSchemaValidator",
"PPTXSchemaValidator",
"RedliningValidator",
]
```
### scripts/office/validators/base.py
[Download scripts/office/validators/base.py](/skills/docx/scripts/office/validators/base.py)
_Binary resource_
### scripts/office/validators/docx.py
[Download scripts/office/validators/docx.py](/skills/docx/scripts/office/validators/docx.py)
_Binary resource_
### scripts/office/validators/pptx.py
[Download scripts/office/validators/pptx.py](/skills/docx/scripts/office/validators/pptx.py)
_Binary resource_
### scripts/office/validators/redlining.py
[Download scripts/office/validators/redlining.py](/skills/docx/scripts/office/validators/redlining.py)
_Binary resource_
### scripts/templates/comments.xml
[Download scripts/templates/comments.xml](/skills/docx/scripts/templates/comments.xml)
_Binary resource_
### scripts/templates/commentsExtended.xml
[Download scripts/templates/commentsExtended.xml](/skills/docx/scripts/templates/commentsExtended.xml)
_Binary resource_
### scripts/templates/commentsExtensible.xml
[Download scripts/templates/commentsExtensible.xml](/skills/docx/scripts/templates/commentsExtensible.xml)
_Binary resource_
### scripts/templates/commentsIds.xml
[Download scripts/templates/commentsIds.xml](/skills/docx/scripts/templates/commentsIds.xml)
_Binary resource_
### scripts/templates/people.xml
[Download scripts/templates/people.xml](/skills/docx/scripts/templates/people.xml)
_Binary resource_
## See in GitHub
[See in GitHub](https://github.com/anthropics/skills/tree/main/docx)
---
# Frontend Design Skill - Better UI Code from Claude
URL: http://www.claudeskills.org/docs/skills-cases/frontend-design
Description: How the Frontend Design skill pushes Claude toward production-grade UI: design tokens, spacing systems, and distinctive layouts - full breakdown.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the June 9, 2026 upstream rewrite.
## Overview
The official description: *"Guidance for distinctive, intentional visual design when building new UI or reshaping an existing one. Helps with aesthetic direction, typography, and making choices that don't read as templated defaults."*
The 2026 rewrite reframes the whole skill around one stance: Claude acts as **the design lead at a small studio whose client has already rejected templated proposals**. Every choice - palette, type, layout - must be specific to the brief, including "one real aesthetic risk you can justify."
## How the skill works
The current SKILL.md walks through five stages:
1. **Ground it in the subject** - if the brief doesn't pin down the product, Claude must name a concrete subject, audience, and the page's single job before designing. Distinctive choices come from the subject's own world.
2. **Design principles** - the hero is a thesis; typography carries the personality (no default font pairs); structure is information (numbered markers only when order really matters); motion is deliberate, not scattered.
3. **Process: brainstorm → explore → plan → critique → build → critique again** - Claude first writes a compact token system (4-6 named hex colors, 2+ type roles, a layout concept in ASCII wireframes, and a "signature" element the page will be remembered by), then reviews that plan against the brief *before* writing code.
4. **Anti-default calibration** - the skill explicitly names the three looks AI design currently clusters around (warm cream + serif + terracotta; near-black + acid green; broadsheet hairlines) and instructs Claude not to spend free choices on them.
5. **CSS discipline** - watch selector specificity so section/CTA rules don't cancel each other's spacing.
## What's inside the skill folder
- `SKILL.md` - the full design playbook (~8 KB)
- `LICENSE.txt`
## Key takeaways for your own skills
- Encode taste as **named anti-patterns**: listing the default looks to avoid is more actionable than "be creative."
- Force a **plan-then-critique gate** before generation - the skill makes Claude argue with its own first draft.
## See it on GitHub
[skills/frontend-design](https://github.com/anthropics/skills/tree/main/skills/frontend-design)
---
# Internal Comms Skill - Status Updates & Memos with Claude
URL: http://www.claudeskills.org/docs/skills-cases/internal-comms
Description: The Internal Comms skill formats Claude's writing for status reports, incident updates, and leadership memos - see how it works.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"A set of resources to help me write all kinds of internal communications, using the formats that my company likes to use. Claude should use this skill whenever asked to write some sort of internal communications (status reports, leadership updates, 3P updates, company newsletters, FAQs, incident reports...)."*
## How the skill works
This is the minimal viable pattern for a **format-library skill**: a tiny SKILL.md (about 1.5 KB) with three sections - when to use it, how to use it, and trigger keywords - plus a folder of example documents that carry the actual formats:
- `examples/3p-updates.md` - progress/plans/problems updates
- `examples/company-newsletter.md`
- `examples/faq-answers.md`
- `examples/general-comms.md`
Claude matches the requested document type to an example and mirrors its structure and tone.
## Key takeaways for your own skills
- **Examples are the spec**: for writing-style skills, one good sample document beats paragraphs of style description.
- The keywords section doubles as the trigger surface - listing the exact phrases users say ("status report", "incident report") is what makes automatic skill selection reliable.
- This is the easiest official skill to fork for your own team: replace the four examples with your company's formats.
## See it on GitHub
[skills/internal-comms](https://github.com/anthropics/skills/tree/main/skills/internal-comms)
---
# MCP Builder - Claude Skill for Building MCP Servers
URL: http://www.claudeskills.org/docs/skills-cases/mcp-builder
Description: How the MCP Builder skill helps Claude scaffold Model Context Protocol servers, define tools, and write evaluation suites - with the full SKILL.md explained.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Guide for creating high-quality MCP (Model Context Protocol) servers that enable LLMs to interact with external services through well-designed tools. Use when building MCP servers to integrate external APIs or services, whether in Python (FastMCP) or Node/TypeScript (MCP SDK)."*
This is the skill to reach for when you want Claude to scaffold an MCP server that other agents can actually rely on - it bakes in research, implementation patterns, and an evaluation loop.
## How the skill works
The SKILL.md organizes the build into three phases:
1. **Phase 1 - Deep research and planning**: understand modern MCP design, study the protocol docs and the target framework (FastMCP for Python, MCP SDK for Node/TypeScript), then plan the tool surface before writing code.
2. **Phase 2 - Implementation**: set up the project structure, implement core infrastructure, then implement tools one by one with well-designed inputs, outputs, and error messages.
3. **Phase 3 - Review and test**: code-quality pass, then build and test - including agent-facing evaluations, not just unit tests.
## What's inside the skill folder
- `reference/mcp_best_practices.md` - the design rules tools must follow
- `reference/python_mcp_server.md` and `reference/node_mcp_server.md` - per-stack implementation references
- `reference/evaluation.md` plus `scripts/evaluation.py`, `scripts/example_evaluation.xml` - a working evaluation harness
- `scripts/connections.py`, `scripts/requirements.txt`
## Key takeaways for your own skills
- The skill treats **evaluation as part of the deliverable**: an MCP server ships with an eval suite, not just endpoints.
- Splitting per-language references into separate files keeps the main SKILL.md small enough to load fast - a pattern worth copying in any multi-stack skill.
## See it on GitHub
[skills/mcp-builder](https://github.com/anthropics/skills/tree/main/skills/mcp-builder)
---
# PDF Skill - Fill, Extract & Generate PDFs with Claude
URL: http://www.claudeskills.org/docs/skills-cases/pdf
Description: The PDF skill gives Claude form filling, text and table extraction, merging, and generation - see the full SKILL.md and when Claude triggers it.
Source: Content adapted from anthropics/skills (MIT).
## Overview
This guide covers essential PDF processing operations using Python libraries and command-line tools. For advanced features, JavaScript libraries, and detailed examples, see REFERENCE.md. If you need to fill out a PDF form, read FORMS.md and follow its instructions.
## Quick Start
```python
from pypdf import PdfReader, PdfWriter
# Read a PDF
reader = PdfReader("document.pdf")
print(f"Pages: {len(reader.pages)}")
# Extract text
text = ""
for page in reader.pages:
text += page.extract_text()
```
## Python Libraries
### pypdf - Basic Operations
#### Merge PDFs
```python
from pypdf import PdfWriter, PdfReader
writer = PdfWriter()
for pdf_file in ["doc1.pdf", "doc2.pdf", "doc3.pdf"]:
reader = PdfReader(pdf_file)
for page in reader.pages:
writer.add_page(page)
with open("merged.pdf", "wb") as output:
writer.write(output)
```
#### Split PDF
```python
reader = PdfReader("input.pdf")
for i, page in enumerate(reader.pages):
writer = PdfWriter()
writer.add_page(page)
with open(f"page_{i+1}.pdf", "wb") as output:
writer.write(output)
```
#### Extract Metadata
```python
reader = PdfReader("document.pdf")
meta = reader.metadata
print(f"Title: {meta.title}")
print(f"Author: {meta.author}")
print(f"Subject: {meta.subject}")
print(f"Creator: {meta.creator}")
```
#### Rotate Pages
```python
reader = PdfReader("input.pdf")
writer = PdfWriter()
page = reader.pages[0]
page.rotate(90) # Rotate 90 degrees clockwise
writer.add_page(page)
with open("rotated.pdf", "wb") as output:
writer.write(output)
```
### pdfplumber - Text and Table Extraction
#### Extract Text with Layout
```python
import pdfplumber
with pdfplumber.open("document.pdf") as pdf:
for page in pdf.pages:
text = page.extract_text()
print(text)
```
#### Extract Tables
```python
with pdfplumber.open("document.pdf") as pdf:
for i, page in enumerate(pdf.pages):
tables = page.extract_tables()
for j, table in enumerate(tables):
print(f"Table {j+1} on page {i+1}:")
for row in table:
print(row)
```
#### Advanced Table Extraction
```python
import pandas as pd
with pdfplumber.open("document.pdf") as pdf:
all_tables = []
for page in pdf.pages:
tables = page.extract_tables()
for table in tables:
if table: # Check if table is not empty
df = pd.DataFrame(table[1:], columns=table[0])
all_tables.append(df)
# Combine all tables
if all_tables:
combined_df = pd.concat(all_tables, ignore_index=True)
combined_df.to_excel("extracted_tables.xlsx", index=False)
```
### reportlab - Create PDFs
#### Basic PDF Creation
```python
from reportlab.lib.pagesizes import letter
from reportlab.pdfgen import canvas
c = canvas.Canvas("hello.pdf", pagesize=letter)
width, height = letter
# Add text
c.drawString(100, height - 100, "Hello World!")
c.drawString(100, height - 120, "This is a PDF created with reportlab")
# Add a line
c.line(100, height - 140, 400, height - 140)
# Save
c.save()
```
#### Create PDF with Multiple Pages
```python
from reportlab.lib.pagesizes import letter
from reportlab.platypus import SimpleDocTemplate, Paragraph, Spacer, PageBreak
from reportlab.lib.styles import getSampleStyleSheet
doc = SimpleDocTemplate("report.pdf", pagesize=letter)
styles = getSampleStyleSheet()
story = []
# Add content
title = Paragraph("Report Title", styles['Title'])
story.append(title)
story.append(Spacer(1, 12))
body = Paragraph("This is the body of the report. " * 20, styles['Normal'])
story.append(body)
story.append(PageBreak())
# Page 2
story.append(Paragraph("Page 2", styles['Heading1']))
story.append(Paragraph("Content for page 2", styles['Normal']))
# Build PDF
doc.build(story)
```
#### Subscripts and Superscripts
**IMPORTANT**: Never use Unicode subscript/superscript characters (0123456789, 0123456789) in ReportLab PDFs. The built-in fonts do not include these glyphs, causing them to render as solid black boxes.
Instead, use ReportLab's XML markup tags in Paragraph objects:
```python
from reportlab.platypus import Paragraph
from reportlab.lib.styles import getSampleStyleSheet
styles = getSampleStyleSheet()
# Subscripts: use tag
chemical = Paragraph("H2O", styles['Normal'])
# Superscripts: use tag
squared = Paragraph("x2 + y2", styles['Normal'])
```
For canvas-drawn text (not Paragraph objects), manually adjust font the size and position rather than using Unicode subscripts/superscripts.
## Command-Line Tools
### pdftotext (poppler-utils)
```bash
# Extract text
pdftotext input.pdf output.txt
# Extract text preserving layout
pdftotext -layout input.pdf output.txt
# Extract specific pages
pdftotext -f 1 -l 5 input.pdf output.txt # Pages 1-5
```
### qpdf
```bash
# Merge PDFs
qpdf --empty --pages file1.pdf file2.pdf -- merged.pdf
# Split pages
qpdf input.pdf --pages . 1-5 -- pages1-5.pdf
qpdf input.pdf --pages . 6-10 -- pages6-10.pdf
# Rotate pages
qpdf input.pdf output.pdf --rotate=+90:1 # Rotate page 1 by 90 degrees
# Remove password
qpdf --password=mypassword --decrypt encrypted.pdf decrypted.pdf
```
### pdftk (if available)
```bash
# Merge
pdftk file1.pdf file2.pdf cat output merged.pdf
# Split
pdftk input.pdf burst
# Rotate
pdftk input.pdf rotate 1east output rotated.pdf
```
## Common Tasks
### Extract Text from Scanned PDFs
```python
# Requires: pip install pytesseract pdf2image
import pytesseract
from pdf2image import convert_from_path
# Convert PDF to images
images = convert_from_path('scanned.pdf')
# OCR each page
text = ""
for i, image in enumerate(images):
text += f"Page {i+1}:\n"
text += pytesseract.image_to_string(image)
text += "\n\n"
print(text)
```
### Add Watermark
```python
from pypdf import PdfReader, PdfWriter
# Create watermark (or load existing)
watermark = PdfReader("watermark.pdf").pages[0]
# Apply to all pages
reader = PdfReader("document.pdf")
writer = PdfWriter()
for page in reader.pages:
page.merge_page(watermark)
writer.add_page(page)
with open("watermarked.pdf", "wb") as output:
writer.write(output)
```
### Extract Images
```bash
# Using pdfimages (poppler-utils)
pdfimages -j input.pdf output_prefix
# This extracts all images as output_prefix-000.jpg, output_prefix-001.jpg, etc.
```
### Password Protection
```python
from pypdf import PdfReader, PdfWriter
reader = PdfReader("input.pdf")
writer = PdfWriter()
for page in reader.pages:
writer.add_page(page)
# Add password
writer.encrypt("userpassword", "ownerpassword")
with open("encrypted.pdf", "wb") as output:
writer.write(output)
```
## Quick Reference
| Task | Best Tool | Command/Code |
|------|-----------|--------------|
| Merge PDFs | pypdf | `writer.add_page(page)` |
| Split PDFs | pypdf | One page per file |
| Extract text | pdfplumber | `page.extract_text()` |
| Extract tables | pdfplumber | `page.extract_tables()` |
| Create PDFs | reportlab | Canvas or Platypus |
| Command line merge | qpdf | `qpdf --empty --pages ...` |
| OCR scanned PDFs | pytesseract | Convert to image first |
| Fill PDF forms | pdf-lib or pypdf (see FORMS.md) | See FORMS.md |
## Next Steps
- For advanced pypdfium2 usage, see REFERENCE.md
- For JavaScript libraries (pdf-lib), see REFERENCE.md
- If you need to fill out a PDF form, follow the instructions in FORMS.md
- For troubleshooting guides, see REFERENCE.md
## Resource Files
### LICENSE.txt
[Download LICENSE.txt](/skills/pdf/LICENSE.txt)
_Binary resource_
### forms.md
[Download forms.md](/skills/pdf/forms.md)
_Binary resource_
### reference.md
[Download reference.md](/skills/pdf/reference.md)
_Binary resource_
### scripts/check_bounding_boxes.py
[Download scripts/check_bounding_boxes.py](/skills/pdf/scripts/check_bounding_boxes.py)
```python
from dataclasses import dataclass
import json
import sys
@dataclass
class RectAndField:
rect: list[float]
rect_type: str
field: dict
def get_bounding_box_messages(fields_json_stream) -> list[str]:
messages = []
fields = json.load(fields_json_stream)
messages.append(f"Read {len(fields['form_fields'])} fields")
def rects_intersect(r1, r2):
disjoint_horizontal = r1[0] >= r2[2] or r1[2] <= r2[0]
disjoint_vertical = r1[1] >= r2[3] or r1[3] <= r2[1]
return not (disjoint_horizontal or disjoint_vertical)
rects_and_fields = []
for f in fields["form_fields"]:
rects_and_fields.append(RectAndField(f["label_bounding_box"], "label", f))
rects_and_fields.append(RectAndField(f["entry_bounding_box"], "entry", f))
has_error = False
for i, ri in enumerate(rects_and_fields):
for j in range(i + 1, len(rects_and_fields)):
rj = rects_and_fields[j]
if ri.field["page_number"] == rj.field["page_number"] and rects_intersect(ri.rect, rj.rect):
has_error = True
if ri.field is rj.field:
messages.append(f"FAILURE: intersection between label and entry bounding boxes for `{ri.field['description']}` ({ri.rect}, {rj.rect})")
else:
messages.append(f"FAILURE: intersection between {ri.rect_type} bounding box for `{ri.field['description']}` ({ri.rect}) and {rj.rect_type} bounding box for `{rj.field['description']}` ({rj.rect})")
if len(messages) >= 20:
messages.append("Aborting further checks; fix bounding boxes and try again")
return messages
if ri.rect_type == "entry":
if "entry_text" in ri.field:
font_size = ri.field["entry_text"].get("font_size", 14)
entry_height = ri.rect[3] - ri.rect[1]
if entry_height < font_size:
has_error = True
messages.append(f"FAILURE: entry bounding box height ({entry_height}) for `{ri.field['description']}` is too short for the text content (font size: {font_size}). Increase the box height or decrease the font size.")
if len(messages) >= 20:
messages.append("Aborting further checks; fix bounding boxes and try again")
return messages
if not has_error:
messages.append("SUCCESS: All bounding boxes are valid")
return messages
if __name__ == "__main__":
if len(sys.argv) != 2:
print("Usage: check_bounding_boxes.py [fields.json]")
sys.exit(1)
with open(sys.argv[1]) as f:
messages = get_bounding_box_messages(f)
for msg in messages:
print(msg)
```
### scripts/check_fillable_fields.py
[Download scripts/check_fillable_fields.py](/skills/pdf/scripts/check_fillable_fields.py)
```python
import sys
from pypdf import PdfReader
reader = PdfReader(sys.argv[1])
if (reader.get_fields()):
print("This PDF has fillable form fields")
else:
print("This PDF does not have fillable form fields; you will need to visually determine where to enter data")
```
### scripts/convert_pdf_to_images.py
[Download scripts/convert_pdf_to_images.py](/skills/pdf/scripts/convert_pdf_to_images.py)
```python
import os
import sys
from pdf2image import convert_from_path
def convert(pdf_path, output_dir, max_dim=1000):
images = convert_from_path(pdf_path, dpi=200)
for i, image in enumerate(images):
width, height = image.size
if width > max_dim or height > max_dim:
scale_factor = min(max_dim / width, max_dim / height)
new_width = int(width * scale_factor)
new_height = int(height * scale_factor)
image = image.resize((new_width, new_height))
image_path = os.path.join(output_dir, f"page_{i+1}.png")
image.save(image_path)
print(f"Saved page {i+1} as {image_path} (size: {image.size})")
print(f"Converted {len(images)} pages to PNG images")
if __name__ == "__main__":
if len(sys.argv) != 3:
print("Usage: convert_pdf_to_images.py [input pdf] [output directory]")
sys.exit(1)
pdf_path = sys.argv[1]
output_directory = sys.argv[2]
convert(pdf_path, output_directory)
```
### scripts/create_validation_image.py
[Download scripts/create_validation_image.py](/skills/pdf/scripts/create_validation_image.py)
```python
import json
import sys
from PIL import Image, ImageDraw
def create_validation_image(page_number, fields_json_path, input_path, output_path):
with open(fields_json_path, 'r') as f:
data = json.load(f)
img = Image.open(input_path)
draw = ImageDraw.Draw(img)
num_boxes = 0
for field in data["form_fields"]:
if field["page_number"] == page_number:
entry_box = field['entry_bounding_box']
label_box = field['label_bounding_box']
draw.rectangle(entry_box, outline='red', width=2)
draw.rectangle(label_box, outline='blue', width=2)
num_boxes += 2
img.save(output_path)
print(f"Created validation image at {output_path} with {num_boxes} bounding boxes")
if __name__ == "__main__":
if len(sys.argv) != 5:
print("Usage: create_validation_image.py [page number] [fields.json file] [input image path] [output image path]")
sys.exit(1)
page_number = int(sys.argv[1])
fields_json_path = sys.argv[2]
input_image_path = sys.argv[3]
output_image_path = sys.argv[4]
create_validation_image(page_number, fields_json_path, input_image_path, output_image_path)
```
### scripts/extract_form_field_info.py
[Download scripts/extract_form_field_info.py](/skills/pdf/scripts/extract_form_field_info.py)
```python
import json
import sys
from pypdf import PdfReader
def get_full_annotation_field_id(annotation):
components = []
while annotation:
field_name = annotation.get('/T')
if field_name:
components.append(field_name)
annotation = annotation.get('/Parent')
return ".".join(reversed(components)) if components else None
def make_field_dict(field, field_id):
field_dict = {"field_id": field_id}
ft = field.get('/FT')
if ft == "/Tx":
field_dict["type"] = "text"
elif ft == "/Btn":
field_dict["type"] = "checkbox"
states = field.get("/_States_", [])
if len(states) == 2:
if "/Off" in states:
field_dict["checked_value"] = states[0] if states[0] != "/Off" else states[1]
field_dict["unchecked_value"] = "/Off"
else:
print(f"Unexpected state values for checkbox `${field_id}`. Its checked and unchecked values may not be correct; if you're trying to check it, visually verify the results.")
field_dict["checked_value"] = states[0]
field_dict["unchecked_value"] = states[1]
elif ft == "/Ch":
field_dict["type"] = "choice"
states = field.get("/_States_", [])
field_dict["choice_options"] = [{
"value": state[0],
"text": state[1],
} for state in states]
else:
field_dict["type"] = f"unknown ({ft})"
return field_dict
def get_field_info(reader: PdfReader):
fields = reader.get_fields()
field_info_by_id = {}
possible_radio_names = set()
for field_id, field in fields.items():
if field.get("/Kids"):
if field.get("/FT") == "/Btn":
possible_radio_names.add(field_id)
continue
field_info_by_id[field_id] = make_field_dict(field, field_id)
radio_fields_by_id = {}
for page_index, page in enumerate(reader.pages):
annotations = page.get('/Annots', [])
for ann in annotations:
field_id = get_full_annotation_field_id(ann)
if field_id in field_info_by_id:
field_info_by_id[field_id]["page"] = page_index + 1
field_info_by_id[field_id]["rect"] = ann.get('/Rect')
elif field_id in possible_radio_names:
try:
on_values = [v for v in ann["/AP"]["/N"] if v != "/Off"]
except KeyError:
continue
if len(on_values) == 1:
rect = ann.get("/Rect")
if field_id not in radio_fields_by_id:
radio_fields_by_id[field_id] = {
"field_id": field_id,
"type": "radio_group",
"page": page_index + 1,
"radio_options": [],
}
radio_fields_by_id[field_id]["radio_options"].append({
"value": on_values[0],
"rect": rect,
})
fields_with_location = []
for field_info in field_info_by_id.values():
if "page" in field_info:
fields_with_location.append(field_info)
else:
print(f"Unable to determine location for field id: {field_info.get('field_id')}, ignoring")
def sort_key(f):
if "radio_options" in f:
rect = f["radio_options"][0]["rect"] or [0, 0, 0, 0]
else:
rect = f.get("rect") or [0, 0, 0, 0]
adjusted_position = [-rect[1], rect[0]]
return [f.get("page"), adjusted_position]
sorted_fields = fields_with_location + list(radio_fields_by_id.values())
sorted_fields.sort(key=sort_key)
return sorted_fields
def write_field_info(pdf_path: str, json_output_path: str):
reader = PdfReader(pdf_path)
field_info = get_field_info(reader)
with open(json_output_path, "w") as f:
json.dump(field_info, f, indent=2)
print(f"Wrote {len(field_info)} fields to {json_output_path}")
if __name__ == "__main__":
if len(sys.argv) != 3:
print("Usage: extract_form_field_info.py [input pdf] [output json]")
sys.exit(1)
write_field_info(sys.argv[1], sys.argv[2])
```
### scripts/extract_form_structure.py
[Download scripts/extract_form_structure.py](/skills/pdf/scripts/extract_form_structure.py)
```python
"""
Extract form structure from a non-fillable PDF.
This script analyzes the PDF to find:
- Text labels with their exact coordinates
- Horizontal lines (row boundaries)
- Checkboxes (small rectangles)
Output: A JSON file with the form structure that can be used to generate
accurate field coordinates for filling.
Usage: python extract_form_structure.py
"""
import json
import sys
import pdfplumber
def extract_form_structure(pdf_path):
structure = {
"pages": [],
"labels": [],
"lines": [],
"checkboxes": [],
"row_boundaries": []
}
with pdfplumber.open(pdf_path) as pdf:
for page_num, page in enumerate(pdf.pages, 1):
structure["pages"].append({
"page_number": page_num,
"width": float(page.width),
"height": float(page.height)
})
words = page.extract_words()
for word in words:
structure["labels"].append({
"page": page_num,
"text": word["text"],
"x0": round(float(word["x0"]), 1),
"top": round(float(word["top"]), 1),
"x1": round(float(word["x1"]), 1),
"bottom": round(float(word["bottom"]), 1)
})
for line in page.lines:
if abs(float(line["x1"]) - float(line["x0"])) > page.width * 0.5:
structure["lines"].append({
"page": page_num,
"y": round(float(line["top"]), 1),
"x0": round(float(line["x0"]), 1),
"x1": round(float(line["x1"]), 1)
})
for rect in page.rects:
width = float(rect["x1"]) - float(rect["x0"])
height = float(rect["bottom"]) - float(rect["top"])
if 5 <= width <= 15 and 5 <= height <= 15 and abs(width - height) < 2:
structure["checkboxes"].append({
"page": page_num,
"x0": round(float(rect["x0"]), 1),
"top": round(float(rect["top"]), 1),
"x1": round(float(rect["x1"]), 1),
"bottom": round(float(rect["bottom"]), 1),
"center_x": round((float(rect["x0"]) + float(rect["x1"])) / 2, 1),
"center_y": round((float(rect["top"]) + float(rect["bottom"])) / 2, 1)
})
lines_by_page = {}
for line in structure["lines"]:
page = line["page"]
if page not in lines_by_page:
lines_by_page[page] = []
lines_by_page[page].append(line["y"])
for page, y_coords in lines_by_page.items():
y_coords = sorted(set(y_coords))
for i in range(len(y_coords) - 1):
structure["row_boundaries"].append({
"page": page,
"row_top": y_coords[i],
"row_bottom": y_coords[i + 1],
"row_height": round(y_coords[i + 1] - y_coords[i], 1)
})
return structure
def main():
if len(sys.argv) != 3:
print("Usage: extract_form_structure.py ")
sys.exit(1)
pdf_path = sys.argv[1]
output_path = sys.argv[2]
print(f"Extracting structure from {pdf_path}...")
structure = extract_form_structure(pdf_path)
with open(output_path, "w") as f:
json.dump(structure, f, indent=2)
print(f"Found:")
print(f" - {len(structure['pages'])} pages")
print(f" - {len(structure['labels'])} text labels")
print(f" - {len(structure['lines'])} horizontal lines")
print(f" - {len(structure['checkboxes'])} checkboxes")
print(f" - {len(structure['row_boundaries'])} row boundaries")
print(f"Saved to {output_path}")
if __name__ == "__main__":
main()
```
### scripts/fill_fillable_fields.py
[Download scripts/fill_fillable_fields.py](/skills/pdf/scripts/fill_fillable_fields.py)
```python
import json
import sys
from pypdf import PdfReader, PdfWriter
from extract_form_field_info import get_field_info
def fill_pdf_fields(input_pdf_path: str, fields_json_path: str, output_pdf_path: str):
with open(fields_json_path) as f:
fields = json.load(f)
fields_by_page = {}
for field in fields:
if "value" in field:
field_id = field["field_id"]
page = field["page"]
if page not in fields_by_page:
fields_by_page[page] = {}
fields_by_page[page][field_id] = field["value"]
reader = PdfReader(input_pdf_path)
has_error = False
field_info = get_field_info(reader)
fields_by_ids = {f["field_id"]: f for f in field_info}
for field in fields:
existing_field = fields_by_ids.get(field["field_id"])
if not existing_field:
has_error = True
print(f"ERROR: `{field['field_id']}` is not a valid field ID")
elif field["page"] != existing_field["page"]:
has_error = True
print(f"ERROR: Incorrect page number for `{field['field_id']}` (got {field['page']}, expected {existing_field['page']})")
else:
if "value" in field:
err = validation_error_for_field_value(existing_field, field["value"])
if err:
print(err)
has_error = True
if has_error:
sys.exit(1)
writer = PdfWriter(clone_from=reader)
for page, field_values in fields_by_page.items():
writer.update_page_form_field_values(writer.pages[page - 1], field_values, auto_regenerate=False)
writer.set_need_appearances_writer(True)
with open(output_pdf_path, "wb") as f:
writer.write(f)
def validation_error_for_field_value(field_info, field_value):
field_type = field_info["type"]
field_id = field_info["field_id"]
if field_type == "checkbox":
checked_val = field_info["checked_value"]
unchecked_val = field_info["unchecked_value"]
if field_value != checked_val and field_value != unchecked_val:
return f'ERROR: Invalid value "{field_value}" for checkbox field "{field_id}". The checked value is "{checked_val}" and the unchecked value is "{unchecked_val}"'
elif field_type == "radio_group":
option_values = [opt["value"] for opt in field_info["radio_options"]]
if field_value not in option_values:
return f'ERROR: Invalid value "{field_value}" for radio group field "{field_id}". Valid values are: {option_values}'
elif field_type == "choice":
choice_values = [opt["value"] for opt in field_info["choice_options"]]
if field_value not in choice_values:
return f'ERROR: Invalid value "{field_value}" for choice field "{field_id}". Valid values are: {choice_values}'
return None
def monkeypatch_pydpf_method():
from pypdf.generic import DictionaryObject
from pypdf.constants import FieldDictionaryAttributes
original_get_inherited = DictionaryObject.get_inherited
def patched_get_inherited(self, key: str, default = None):
result = original_get_inherited(self, key, default)
if key == FieldDictionaryAttributes.Opt:
if isinstance(result, list) and all(isinstance(v, list) and len(v) == 2 for v in result):
result = [r[0] for r in result]
return result
DictionaryObject.get_inherited = patched_get_inherited
if __name__ == "__main__":
if len(sys.argv) != 4:
print("Usage: fill_fillable_fields.py [input pdf] [field_values.json] [output pdf]")
sys.exit(1)
monkeypatch_pydpf_method()
input_pdf = sys.argv[1]
fields_json = sys.argv[2]
output_pdf = sys.argv[3]
fill_pdf_fields(input_pdf, fields_json, output_pdf)
```
### scripts/fill_pdf_form_with_annotations.py
[Download scripts/fill_pdf_form_with_annotations.py](/skills/pdf/scripts/fill_pdf_form_with_annotations.py)
```python
import json
import sys
from pypdf import PdfReader, PdfWriter
from pypdf.annotations import FreeText
def transform_from_image_coords(bbox, image_width, image_height, pdf_width, pdf_height):
x_scale = pdf_width / image_width
y_scale = pdf_height / image_height
left = bbox[0] * x_scale
right = bbox[2] * x_scale
top = pdf_height - (bbox[1] * y_scale)
bottom = pdf_height - (bbox[3] * y_scale)
return left, bottom, right, top
def transform_from_pdf_coords(bbox, pdf_height):
left = bbox[0]
right = bbox[2]
pypdf_top = pdf_height - bbox[1]
pypdf_bottom = pdf_height - bbox[3]
return left, pypdf_bottom, right, pypdf_top
def fill_pdf_form(input_pdf_path, fields_json_path, output_pdf_path):
with open(fields_json_path, "r") as f:
fields_data = json.load(f)
reader = PdfReader(input_pdf_path)
writer = PdfWriter()
writer.append(reader)
pdf_dimensions = {}
for i, page in enumerate(reader.pages):
mediabox = page.mediabox
pdf_dimensions[i + 1] = [mediabox.width, mediabox.height]
annotations = []
for field in fields_data["form_fields"]:
page_num = field["page_number"]
page_info = next(p for p in fields_data["pages"] if p["page_number"] == page_num)
pdf_width, pdf_height = pdf_dimensions[page_num]
if "pdf_width" in page_info:
transformed_entry_box = transform_from_pdf_coords(
field["entry_bounding_box"],
float(pdf_height)
)
else:
image_width = page_info["image_width"]
image_height = page_info["image_height"]
transformed_entry_box = transform_from_image_coords(
field["entry_bounding_box"],
image_width, image_height,
float(pdf_width), float(pdf_height)
)
if "entry_text" not in field or "text" not in field["entry_text"]:
continue
entry_text = field["entry_text"]
text = entry_text["text"]
if not text:
continue
font_name = entry_text.get("font", "Arial")
font_size = str(entry_text.get("font_size", 14)) + "pt"
font_color = entry_text.get("font_color", "000000")
annotation = FreeText(
text=text,
rect=transformed_entry_box,
font=font_name,
font_size=font_size,
font_color=font_color,
border_color=None,
background_color=None,
)
annotations.append(annotation)
writer.add_annotation(page_number=page_num - 1, annotation=annotation)
with open(output_pdf_path, "wb") as output:
writer.write(output)
print(f"Successfully filled PDF form and saved to {output_pdf_path}")
print(f"Added {len(annotations)} text annotations")
if __name__ == "__main__":
if len(sys.argv) != 4:
print("Usage: fill_pdf_form_with_annotations.py [input pdf] [fields.json] [output pdf]")
sys.exit(1)
input_pdf = sys.argv[1]
fields_json = sys.argv[2]
output_pdf = sys.argv[3]
fill_pdf_form(input_pdf, fields_json, output_pdf)
```
## See in GitHub
[See in GitHub](https://github.com/anthropics/skills/tree/main/pdf)
---
# Pptx Skill - Create PowerPoint Decks with Claude
URL: http://www.claudeskills.org/docs/skills-cases/pptx
Description: How the Pptx skill lets Claude build and edit PowerPoint presentations: layouts, speaker notes, and slide generation - full skill breakdown.
Source: Content adapted from anthropics/skills (MIT).
## Quick Reference
| Task | Guide |
|------|-------|
| Read/analyze content | `python -m markitdown presentation.pptx` |
| Edit or create from template | Read [editing.md](editing.md) |
| Create from scratch | Read [pptxgenjs.md](pptxgenjs.md) |
---
## Reading Content
```bash
# Text extraction
python -m markitdown presentation.pptx
# Visual overview
python scripts/thumbnail.py presentation.pptx
# Raw XML
python scripts/office/unpack.py presentation.pptx unpacked/
```
---
## Editing Workflow
**Read [editing.md](editing.md) for full details.**
1. Analyze template with `thumbnail.py`
2. Unpack -> manipulate slides -> edit content -> clean -> pack
---
## Creating from Scratch
**Read [pptxgenjs.md](pptxgenjs.md) for full details.**
Use when no template or reference presentation is available.
---
## Design Ideas
**Don't create boring slides.** Plain bullets on a white background won't impress anyone. Consider ideas from this list for each slide.
### Before Starting
- **Pick a bold, content-informed color palette**: The palette should feel designed for THIS topic. If swapping your colors into a completely different presentation would still "work," you haven't made specific enough choices.
- **Dominance over equality**: One color should dominate (60-70% visual weight), with 1-2 supporting tones and one sharp accent. Never give all colors equal weight.
- **Dark/light contrast**: Dark backgrounds for title + conclusion slides, light for content ("sandwich" structure). Or commit to dark throughout for a premium feel.
- **Commit to a visual motif**: Pick ONE distinctive element and repeat it - rounded image frames, icons in colored circles, thick single-side borders. Carry it across every slide.
### Color Palettes
Choose colors that match your topic - don't default to generic blue. Use these palettes as inspiration:
| Theme | Primary | Secondary | Accent |
|-------|---------|-----------|--------|
| **Midnight Executive** | `1E2761` (navy) | `CADCFC` (ice blue) | `FFFFFF` (white) |
| **Forest & Moss** | `2C5F2D` (forest) | `97BC62` (moss) | `F5F5F5` (cream) |
| **Coral Energy** | `F96167` (coral) | `F9E795` (gold) | `2F3C7E` (navy) |
| **Warm Terracotta** | `B85042` (terracotta) | `E7E8D1` (sand) | `A7BEAE` (sage) |
| **Ocean Gradient** | `065A82` (deep blue) | `1C7293` (teal) | `21295C` (midnight) |
| **Charcoal Minimal** | `36454F` (charcoal) | `F2F2F2` (off-white) | `212121` (black) |
| **Teal Trust** | `028090` (teal) | `00A896` (seafoam) | `02C39A` (mint) |
| **Berry & Cream** | `6D2E46` (berry) | `A26769` (dusty rose) | `ECE2D0` (cream) |
| **Sage Calm** | `84B59F` (sage) | `69A297` (eucalyptus) | `50808E` (slate) |
| **Cherry Bold** | `990011` (cherry) | `FCF6F5` (off-white) | `2F3C7E` (navy) |
### For Each Slide
**Every slide needs a visual element** - image, chart, icon, or shape. Text-only slides are forgettable.
**Layout options:**
- Two-column (text left, illustration on right)
- Icon + text rows (icon in colored circle, bold header, description below)
- 2x2 or 2x3 grid (image on one side, grid of content blocks on other)
- Half-bleed image (full left or right side) with content overlay
**Data display:**
- Large stat callouts (big numbers 60-72pt with small labels below)
- Comparison columns (before/after, pros/cons, side-by-side options)
- Timeline or process flow (numbered steps, arrows)
**Visual polish:**
- Icons in small colored circles next to section headers
- Italic accent text for key stats or taglines
### Typography
**Choose an interesting font pairing** - don't default to Arial. Pick a header font with personality and pair it with a clean body font.
| Header Font | Body Font |
|-------------|-----------|
| Georgia | Calibri |
| Arial Black | Arial |
| Calibri | Calibri Light |
| Cambria | Calibri |
| Trebuchet MS | Calibri |
| Impact | Arial |
| Palatino | Garamond |
| Consolas | Calibri |
| Element | Size |
|---------|------|
| Slide title | 36-44pt bold |
| Section header | 20-24pt bold |
| Body text | 14-16pt |
| Captions | 10-12pt muted |
### Spacing
- 0.5" minimum margins
- 0.3-0.5" between content blocks
- Leave breathing room-don't fill every inch
### Avoid (Common Mistakes)
- **Don't repeat the same layout** - vary columns, cards, and callouts across slides
- **Don't center body text** - left-align paragraphs and lists; center only titles
- **Don't skimp on size contrast** - titles need 36pt+ to stand out from 14-16pt body
- **Don't default to blue** - pick colors that reflect the specific topic
- **Don't mix spacing randomly** - choose 0.3" or 0.5" gaps and use consistently
- **Don't style one slide and leave the rest plain** - commit fully or keep it simple throughout
- **Don't create text-only slides** - add images, icons, charts, or visual elements; avoid plain title + bullets
- **Don't forget text box padding** - when aligning lines or shapes with text edges, set `margin: 0` on the text box or offset the shape to account for padding
- **Don't use low-contrast elements** - icons AND text need strong contrast against the background; avoid light text on light backgrounds or dark text on dark backgrounds
- **NEVER use accent lines under titles** - these are a hallmark of AI-generated slides; use whitespace or background color instead
---
## QA (Required)
**Assume there are problems. Your job is to find them.**
Your first render is almost never correct. Approach QA as a bug hunt, not a confirmation step. If you found zero issues on first inspection, you weren't looking hard enough.
### Content QA
```bash
python -m markitdown output.pptx
```
Check for missing content, typos, wrong order.
**When using templates, check for leftover placeholder text:**
```bash
python -m markitdown output.pptx | grep -iE "xxxx|lorem|ipsum|this.*(page|slide).*layout"
```
If grep returns results, fix them before declaring success.
### Visual QA
** USE SUBAGENTS** - even for 2-3 slides. You've been staring at the code and will see what you expect, not what's there. Subagents have fresh eyes.
Convert slides to images (see [Converting to Images](#converting-to-images)), then use this prompt:
```
Visually inspect these slides. Assume there are issues - find them.
Look for:
- Overlapping elements (text through shapes, lines through words, stacked elements)
- Text overflow or cut off at edges/box boundaries
- Decorative lines positioned for single-line text but title wrapped to two lines
- Source citations or footers colliding with content above
- Elements too close (< 0.3" gaps) or cards/sections nearly touching
- Uneven gaps (large empty area in one place, cramped in another)
- Insufficient margin from slide edges (< 0.5")
- Columns or similar elements not aligned consistently
- Low-contrast text (e.g., light gray text on cream-colored background)
- Low-contrast icons (e.g., dark icons on dark backgrounds without a contrasting circle)
- Text boxes too narrow causing excessive wrapping
- Leftover placeholder content
For each slide, list issues or areas of concern, even if minor.
Read and analyze these images:
1. /path/to/slide-01.jpg (Expected: [brief description])
2. /path/to/slide-02.jpg (Expected: [brief description])
Report ALL issues found, including minor ones.
```
### Verification Loop
1. Generate slides -> Convert to images -> Inspect
2. **List issues found** (if none found, look again more critically)
3. Fix issues
4. **Re-verify affected slides** - one fix often creates another problem
5. Repeat until a full pass reveals no new issues
**Do not declare success until you've completed at least one fix-and-verify cycle.**
---
## Converting to Images
Convert presentations to individual slide images for visual inspection:
```bash
python scripts/office/soffice.py --headless --convert-to pdf output.pptx
pdftoppm -jpeg -r 150 output.pdf slide
```
This creates `slide-01.jpg`, `slide-02.jpg`, etc.
To re-render specific slides after fixes:
```bash
pdftoppm -jpeg -r 150 -f N -l N output.pdf slide-fixed
```
---
## Dependencies
- `pip install "markitdown[pptx]"` - text extraction
- `pip install Pillow` - thumbnail grids
- `npm install -g pptxgenjs` - creating from scratch
- LibreOffice (`soffice`) - PDF conversion (auto-configured for sandboxed environments via `scripts/office/soffice.py`)
- Poppler (`pdftoppm`) - PDF to images
## Resource Files
### LICENSE.txt
[Download LICENSE.txt](/skills/pptx/LICENSE.txt)
_Binary resource_
### editing.md
[Download editing.md](/skills/pptx/editing.md)
_Binary resource_
### pptxgenjs.md
[Download pptxgenjs.md](/skills/pptx/pptxgenjs.md)
_Binary resource_
### scripts/__init__.py
[Download scripts/__init__.py](/skills/pptx/scripts/__init__.py)
_Binary resource_
### scripts/add_slide.py
[Download scripts/add_slide.py](/skills/pptx/scripts/add_slide.py)
_Binary resource_
### scripts/clean.py
[Download scripts/clean.py](/skills/pptx/scripts/clean.py)
_Binary resource_
### scripts/office/helpers/__init__.py
[Download scripts/office/helpers/__init__.py](/skills/pptx/scripts/office/helpers/__init__.py)
_Binary resource_
### scripts/office/helpers/merge_runs.py
[Download scripts/office/helpers/merge_runs.py](/skills/pptx/scripts/office/helpers/merge_runs.py)
```python
"""Merge adjacent runs with identical formatting in DOCX.
Merges adjacent elements that have identical properties.
Works on runs in paragraphs and inside tracked changes (, ).
Also:
- Removes rsid attributes from runs (revision metadata that doesn't affect rendering)
- Removes proofErr elements (spell/grammar markers that block merging)
"""
from pathlib import Path
import defusedxml.minidom
def merge_runs(input_dir: str) -> tuple[int, str]:
doc_xml = Path(input_dir) / "word" / "document.xml"
if not doc_xml.exists():
return 0, f"Error: {doc_xml} not found"
try:
dom = defusedxml.minidom.parseString(doc_xml.read_text(encoding="utf-8"))
root = dom.documentElement
_remove_elements(root, "proofErr")
_strip_run_rsid_attrs(root)
containers = {run.parentNode for run in _find_elements(root, "r")}
merge_count = 0
for container in containers:
merge_count += _merge_runs_in(container)
doc_xml.write_bytes(dom.toxml(encoding="UTF-8"))
return merge_count, f"Merged {merge_count} runs"
except Exception as e:
return 0, f"Error: {e}"
def _find_elements(root, tag: str) -> list:
results = []
def traverse(node):
if node.nodeType == node.ELEMENT_NODE:
name = node.localName or node.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(node)
for child in node.childNodes:
traverse(child)
traverse(root)
return results
def _get_child(parent, tag: str):
for child in parent.childNodes:
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name == tag or name.endswith(f":{tag}"):
return child
return None
def _get_children(parent, tag: str) -> list:
results = []
for child in parent.childNodes:
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(child)
return results
def _is_adjacent(elem1, elem2) -> bool:
node = elem1.nextSibling
while node:
if node == elem2:
return True
if node.nodeType == node.ELEMENT_NODE:
return False
if node.nodeType == node.TEXT_NODE and node.data.strip():
return False
node = node.nextSibling
return False
def _remove_elements(root, tag: str):
for elem in _find_elements(root, tag):
if elem.parentNode:
elem.parentNode.removeChild(elem)
def _strip_run_rsid_attrs(root):
for run in _find_elements(root, "r"):
for attr in list(run.attributes.values()):
if "rsid" in attr.name.lower():
run.removeAttribute(attr.name)
def _merge_runs_in(container) -> int:
merge_count = 0
run = _first_child_run(container)
while run:
while True:
next_elem = _next_element_sibling(run)
if next_elem and _is_run(next_elem) and _can_merge(run, next_elem):
_merge_run_content(run, next_elem)
container.removeChild(next_elem)
merge_count += 1
else:
break
_consolidate_text(run)
run = _next_sibling_run(run)
return merge_count
def _first_child_run(container):
for child in container.childNodes:
if child.nodeType == child.ELEMENT_NODE and _is_run(child):
return child
return None
def _next_element_sibling(node):
sibling = node.nextSibling
while sibling:
if sibling.nodeType == sibling.ELEMENT_NODE:
return sibling
sibling = sibling.nextSibling
return None
def _next_sibling_run(node):
sibling = node.nextSibling
while sibling:
if sibling.nodeType == sibling.ELEMENT_NODE:
if _is_run(sibling):
return sibling
sibling = sibling.nextSibling
return None
def _is_run(node) -> bool:
name = node.localName or node.tagName
return name == "r" or name.endswith(":r")
def _can_merge(run1, run2) -> bool:
rpr1 = _get_child(run1, "rPr")
rpr2 = _get_child(run2, "rPr")
if (rpr1 is None) != (rpr2 is None):
return False
if rpr1 is None:
return True
return rpr1.toxml() == rpr2.toxml()
def _merge_run_content(target, source):
for child in list(source.childNodes):
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name != "rPr" and not name.endswith(":rPr"):
target.appendChild(child)
def _consolidate_text(run):
t_elements = _get_children(run, "t")
for i in range(len(t_elements) - 1, 0, -1):
curr, prev = t_elements[i], t_elements[i - 1]
if _is_adjacent(prev, curr):
prev_text = prev.firstChild.data if prev.firstChild else ""
curr_text = curr.firstChild.data if curr.firstChild else ""
merged = prev_text + curr_text
if prev.firstChild:
prev.firstChild.data = merged
else:
prev.appendChild(run.ownerDocument.createTextNode(merged))
if merged.startswith(" ") or merged.endswith(" "):
prev.setAttribute("xml:space", "preserve")
elif prev.hasAttribute("xml:space"):
prev.removeAttribute("xml:space")
run.removeChild(curr)
```
### scripts/office/helpers/simplify_redlines.py
[Download scripts/office/helpers/simplify_redlines.py](/skills/pptx/scripts/office/helpers/simplify_redlines.py)
```python
"""Simplify tracked changes by merging adjacent w:ins or w:del elements.
Merges adjacent elements from the same author into a single element.
Same for elements. This makes heavily-redlined documents easier to
work with by reducing the number of tracked change wrappers.
Rules:
- Only merges w:ins with w:ins, w:del with w:del (same element type)
- Only merges if same author (ignores timestamp differences)
- Only merges if truly adjacent (only whitespace between them)
"""
import xml.etree.ElementTree as ET
import zipfile
from pathlib import Path
import defusedxml.minidom
WORD_NS = "http://schemas.openxmlformats.org/wordprocessingml/2006/main"
def simplify_redlines(input_dir: str) -> tuple[int, str]:
doc_xml = Path(input_dir) / "word" / "document.xml"
if not doc_xml.exists():
return 0, f"Error: {doc_xml} not found"
try:
dom = defusedxml.minidom.parseString(doc_xml.read_text(encoding="utf-8"))
root = dom.documentElement
merge_count = 0
containers = _find_elements(root, "p") + _find_elements(root, "tc")
for container in containers:
merge_count += _merge_tracked_changes_in(container, "ins")
merge_count += _merge_tracked_changes_in(container, "del")
doc_xml.write_bytes(dom.toxml(encoding="UTF-8"))
return merge_count, f"Simplified {merge_count} tracked changes"
except Exception as e:
return 0, f"Error: {e}"
def _merge_tracked_changes_in(container, tag: str) -> int:
merge_count = 0
tracked = [
child
for child in container.childNodes
if child.nodeType == child.ELEMENT_NODE and _is_element(child, tag)
]
if len(tracked) < 2:
return 0
i = 0
while i < len(tracked) - 1:
curr = tracked[i]
next_elem = tracked[i + 1]
if _can_merge_tracked(curr, next_elem):
_merge_tracked_content(curr, next_elem)
container.removeChild(next_elem)
tracked.pop(i + 1)
merge_count += 1
else:
i += 1
return merge_count
def _is_element(node, tag: str) -> bool:
name = node.localName or node.tagName
return name == tag or name.endswith(f":{tag}")
def _get_author(elem) -> str:
author = elem.getAttribute("w:author")
if not author:
for attr in elem.attributes.values():
if attr.localName == "author" or attr.name.endswith(":author"):
return attr.value
return author
def _can_merge_tracked(elem1, elem2) -> bool:
if _get_author(elem1) != _get_author(elem2):
return False
node = elem1.nextSibling
while node and node != elem2:
if node.nodeType == node.ELEMENT_NODE:
return False
if node.nodeType == node.TEXT_NODE and node.data.strip():
return False
node = node.nextSibling
return True
def _merge_tracked_content(target, source):
while source.firstChild:
child = source.firstChild
source.removeChild(child)
target.appendChild(child)
def _find_elements(root, tag: str) -> list:
results = []
def traverse(node):
if node.nodeType == node.ELEMENT_NODE:
name = node.localName or node.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(node)
for child in node.childNodes:
traverse(child)
traverse(root)
return results
def get_tracked_change_authors(doc_xml_path: Path) -> dict[str, int]:
if not doc_xml_path.exists():
return {}
try:
tree = ET.parse(doc_xml_path)
root = tree.getroot()
except ET.ParseError:
return {}
namespaces = {"w": WORD_NS}
author_attr = f"{{{WORD_NS}}}author"
authors: dict[str, int] = {}
for tag in ["ins", "del"]:
for elem in root.findall(f".//w:{tag}", namespaces):
author = elem.get(author_attr)
if author:
authors[author] = authors.get(author, 0) + 1
return authors
def _get_authors_from_docx(docx_path: Path) -> dict[str, int]:
try:
with zipfile.ZipFile(docx_path, "r") as zf:
if "word/document.xml" not in zf.namelist():
return {}
with zf.open("word/document.xml") as f:
tree = ET.parse(f)
root = tree.getroot()
namespaces = {"w": WORD_NS}
author_attr = f"{{{WORD_NS}}}author"
authors: dict[str, int] = {}
for tag in ["ins", "del"]:
for elem in root.findall(f".//w:{tag}", namespaces):
author = elem.get(author_attr)
if author:
authors[author] = authors.get(author, 0) + 1
return authors
except (zipfile.BadZipFile, ET.ParseError):
return {}
def infer_author(modified_dir: Path, original_docx: Path, default: str = "Claude") -> str:
modified_xml = modified_dir / "word" / "document.xml"
modified_authors = get_tracked_change_authors(modified_xml)
if not modified_authors:
return default
original_authors = _get_authors_from_docx(original_docx)
new_changes: dict[str, int] = {}
for author, count in modified_authors.items():
original_count = original_authors.get(author, 0)
diff = count - original_count
if diff > 0:
new_changes[author] = diff
if not new_changes:
return default
if len(new_changes) == 1:
return next(iter(new_changes))
raise ValueError(
f"Multiple authors added new changes: {new_changes}. "
"Cannot infer which author to validate."
)
```
### scripts/office/pack.py
[Download scripts/office/pack.py](/skills/pptx/scripts/office/pack.py)
```python
"""Pack a directory into a DOCX, PPTX, or XLSX file.
Validates with auto-repair, condenses XML formatting, and creates the Office file.
Usage:
python pack.py [--original ] [--validate true|false]
Examples:
python pack.py unpacked/ output.docx --original input.docx
python pack.py unpacked/ output.pptx --validate false
"""
import argparse
import sys
import shutil
import tempfile
import zipfile
from pathlib import Path
import defusedxml.minidom
from validators import DOCXSchemaValidator, PPTXSchemaValidator, RedliningValidator
def pack(
input_directory: str,
output_file: str,
original_file: str | None = None,
validate: bool = True,
infer_author_func=None,
) -> tuple[None, str]:
input_dir = Path(input_directory)
output_path = Path(output_file)
suffix = output_path.suffix.lower()
if not input_dir.is_dir():
return None, f"Error: {input_dir} is not a directory"
if suffix not in {".docx", ".pptx", ".xlsx"}:
return None, f"Error: {output_file} must be a .docx, .pptx, or .xlsx file"
if validate and original_file:
original_path = Path(original_file)
if original_path.exists():
success, output = _run_validation(
input_dir, original_path, suffix, infer_author_func
)
if output:
print(output)
if not success:
return None, f"Error: Validation failed for {input_dir}"
with tempfile.TemporaryDirectory() as temp_dir:
temp_content_dir = Path(temp_dir) / "content"
shutil.copytree(input_dir, temp_content_dir)
for pattern in ["*.xml", "*.rels"]:
for xml_file in temp_content_dir.rglob(pattern):
_condense_xml(xml_file)
output_path.parent.mkdir(parents=True, exist_ok=True)
with zipfile.ZipFile(output_path, "w", zipfile.ZIP_DEFLATED) as zf:
for f in temp_content_dir.rglob("*"):
if f.is_file():
zf.write(f, f.relative_to(temp_content_dir))
return None, f"Successfully packed {input_dir} to {output_file}"
def _run_validation(
unpacked_dir: Path,
original_file: Path,
suffix: str,
infer_author_func=None,
) -> tuple[bool, str | None]:
output_lines = []
validators = []
if suffix == ".docx":
author = "Claude"
if infer_author_func:
try:
author = infer_author_func(unpacked_dir, original_file)
except ValueError as e:
print(f"Warning: {e} Using default author 'Claude'.", file=sys.stderr)
validators = [
DOCXSchemaValidator(unpacked_dir, original_file),
RedliningValidator(unpacked_dir, original_file, author=author),
]
elif suffix == ".pptx":
validators = [PPTXSchemaValidator(unpacked_dir, original_file)]
if not validators:
return True, None
total_repairs = sum(v.repair() for v in validators)
if total_repairs:
output_lines.append(f"Auto-repaired {total_repairs} issue(s)")
success = all(v.validate() for v in validators)
if success:
output_lines.append("All validations PASSED!")
return success, "\n".join(output_lines) if output_lines else None
def _condense_xml(xml_file: Path) -> None:
try:
with open(xml_file, encoding="utf-8") as f:
dom = defusedxml.minidom.parse(f)
for element in dom.getElementsByTagName("*"):
if element.tagName.endswith(":t"):
continue
for child in list(element.childNodes):
if (
child.nodeType == child.TEXT_NODE
and child.nodeValue
and child.nodeValue.strip() == ""
) or child.nodeType == child.COMMENT_NODE:
element.removeChild(child)
xml_file.write_bytes(dom.toxml(encoding="UTF-8"))
except Exception as e:
print(f"ERROR: Failed to parse {xml_file.name}: {e}", file=sys.stderr)
raise
if __name__ == "__main__":
parser = argparse.ArgumentParser(
description="Pack a directory into a DOCX, PPTX, or XLSX file"
)
parser.add_argument("input_directory", help="Unpacked Office document directory")
parser.add_argument("output_file", help="Output Office file (.docx/.pptx/.xlsx)")
parser.add_argument(
"--original",
help="Original file for validation comparison",
)
parser.add_argument(
"--validate",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Run validation with auto-repair (default: true)",
)
args = parser.parse_args()
_, message = pack(
args.input_directory,
args.output_file,
original_file=args.original,
validate=args.validate,
)
print(message)
if "Error" in message:
sys.exit(1)
```
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd](/skills/pptx/scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd](/skills/pptx/scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd](/skills/pptx/scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd](/skills/pptx/scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd](/skills/pptx/scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd)
_Binary resource_
### scripts/office/schemas/mce/mc.xsd
[Download scripts/office/schemas/mce/mc.xsd](/skills/pptx/scripts/office/schemas/mce/mc.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2010.xsd
[Download scripts/office/schemas/microsoft/wml-2010.xsd](/skills/pptx/scripts/office/schemas/microsoft/wml-2010.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2012.xsd
[Download scripts/office/schemas/microsoft/wml-2012.xsd](/skills/pptx/scripts/office/schemas/microsoft/wml-2012.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2018.xsd
[Download scripts/office/schemas/microsoft/wml-2018.xsd](/skills/pptx/scripts/office/schemas/microsoft/wml-2018.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-cex-2018.xsd
[Download scripts/office/schemas/microsoft/wml-cex-2018.xsd](/skills/pptx/scripts/office/schemas/microsoft/wml-cex-2018.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-cid-2016.xsd
[Download scripts/office/schemas/microsoft/wml-cid-2016.xsd](/skills/pptx/scripts/office/schemas/microsoft/wml-cid-2016.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd
[Download scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd](/skills/pptx/scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-symex-2015.xsd
[Download scripts/office/schemas/microsoft/wml-symex-2015.xsd](/skills/pptx/scripts/office/schemas/microsoft/wml-symex-2015.xsd)
_Binary resource_
### scripts/office/soffice.py
[Download scripts/office/soffice.py](/skills/pptx/scripts/office/soffice.py)
```python
"""
Helper for running LibreOffice (soffice) in environments where AF_UNIX
sockets may be blocked (e.g., sandboxed VMs). Detects the restriction
at runtime and applies an LD_PRELOAD shim if needed.
Usage:
from office.soffice import run_soffice, get_soffice_env
# Option 1 – run soffice directly
result = run_soffice(["--headless", "--convert-to", "pdf", "input.docx"])
# Option 2 – get env dict for your own subprocess calls
env = get_soffice_env()
subprocess.run(["soffice", ...], env=env)
"""
import os
import socket
import subprocess
import tempfile
from pathlib import Path
def get_soffice_env() -> dict:
env = os.environ.copy()
env["SAL_USE_VCLPLUGIN"] = "svp"
if _needs_shim():
shim = _ensure_shim()
env["LD_PRELOAD"] = str(shim)
return env
def run_soffice(args: list[str], **kwargs) -> subprocess.CompletedProcess:
env = get_soffice_env()
return subprocess.run(["soffice"] + args, env=env, **kwargs)
_SHIM_SO = Path(tempfile.gettempdir()) / "lo_socket_shim.so"
def _needs_shim() -> bool:
try:
s = socket.socket(socket.AF_UNIX, socket.SOCK_STREAM)
s.close()
return False
except OSError:
return True
def _ensure_shim() -> Path:
if _SHIM_SO.exists():
return _SHIM_SO
src = Path(tempfile.gettempdir()) / "lo_socket_shim.c"
src.write_text(_SHIM_SOURCE)
subprocess.run(
["gcc", "-shared", "-fPIC", "-o", str(_SHIM_SO), str(src), "-ldl"],
check=True,
capture_output=True,
)
src.unlink()
return _SHIM_SO
_SHIM_SOURCE = r"""
#define _GNU_SOURCE
#include
#include
#include
#include
#include
#include
#include
static int (*real_socket)(int, int, int);
static int (*real_socketpair)(int, int, int, int[2]);
static int (*real_listen)(int, int);
static int (*real_accept)(int, struct sockaddr *, socklen_t *);
static int (*real_close)(int);
static int (*real_read)(int, void *, size_t);
/* Per-FD bookkeeping (FDs >= 1024 are passed through unshimmed). */
static int is_shimmed[1024];
static int peer_of[1024];
static int wake_r[1024]; /* accept() blocks reading this */
static int wake_w[1024]; /* close() writes to this */
static int listener_fd = -1; /* FD that received listen() */
__attribute__((constructor))
static void init(void) {
real_socket = dlsym(RTLD_NEXT, "socket");
real_socketpair = dlsym(RTLD_NEXT, "socketpair");
real_listen = dlsym(RTLD_NEXT, "listen");
real_accept = dlsym(RTLD_NEXT, "accept");
real_close = dlsym(RTLD_NEXT, "close");
real_read = dlsym(RTLD_NEXT, "read");
for (int i = 0; i < 1024; i++) {
peer_of[i] = -1;
wake_r[i] = -1;
wake_w[i] = -1;
}
}
/* ---- socket ---------------------------------------------------------- */
int socket(int domain, int type, int protocol) {
if (domain == AF_UNIX) {
int fd = real_socket(domain, type, protocol);
if (fd >= 0) return fd;
/* socket(AF_UNIX) blocked – fall back to socketpair(). */
int sv[2];
if (real_socketpair(domain, type, protocol, sv) == 0) {
if (sv[0] >= 0 && sv[0] < 1024) {
is_shimmed[sv[0]] = 1;
peer_of[sv[0]] = sv[1];
int wp[2];
if (pipe(wp) == 0) {
wake_r[sv[0]] = wp[0];
wake_w[sv[0]] = wp[1];
}
}
return sv[0];
}
errno = EPERM;
return -1;
}
return real_socket(domain, type, protocol);
}
/* ---- listen ---------------------------------------------------------- */
int listen(int sockfd, int backlog) {
if (sockfd >= 0 && sockfd < 1024 && is_shimmed[sockfd]) {
listener_fd = sockfd;
return 0;
}
return real_listen(sockfd, backlog);
}
/* ---- accept ---------------------------------------------------------- */
int accept(int sockfd, struct sockaddr *addr, socklen_t *addrlen) {
if (sockfd >= 0 && sockfd < 1024 && is_shimmed[sockfd]) {
/* Block until close() writes to the wake pipe. */
if (wake_r[sockfd] >= 0) {
char buf;
real_read(wake_r[sockfd], &buf, 1);
}
errno = ECONNABORTED;
return -1;
}
return real_accept(sockfd, addr, addrlen);
}
/* ---- close ----------------------------------------------------------- */
int close(int fd) {
if (fd >= 0 && fd < 1024 && is_shimmed[fd]) {
int was_listener = (fd == listener_fd);
is_shimmed[fd] = 0;
if (wake_w[fd] >= 0) { /* unblock accept() */
char c = 0;
write(wake_w[fd], &c, 1);
real_close(wake_w[fd]);
wake_w[fd] = -1;
}
if (wake_r[fd] >= 0) { real_close(wake_r[fd]); wake_r[fd] = -1; }
if (peer_of[fd] >= 0) { real_close(peer_of[fd]); peer_of[fd] = -1; }
if (was_listener)
_exit(0); /* conversion done – exit */
}
return real_close(fd);
}
"""
if __name__ == "__main__":
import sys
result = run_soffice(sys.argv[1:])
sys.exit(result.returncode)
```
### scripts/office/unpack.py
[Download scripts/office/unpack.py](/skills/pptx/scripts/office/unpack.py)
```python
"""Unpack Office files (DOCX, PPTX, XLSX) for editing.
Extracts the ZIP archive, pretty-prints XML files, and optionally:
- Merges adjacent runs with identical formatting (DOCX only)
- Simplifies adjacent tracked changes from same author (DOCX only)
Usage:
python unpack.py [options]
Examples:
python unpack.py document.docx unpacked/
python unpack.py presentation.pptx unpacked/
python unpack.py document.docx unpacked/ --merge-runs false
"""
import argparse
import sys
import zipfile
from pathlib import Path
import defusedxml.minidom
from helpers.merge_runs import merge_runs as do_merge_runs
from helpers.simplify_redlines import simplify_redlines as do_simplify_redlines
SMART_QUOTE_REPLACEMENTS = {
"\u201c": "“",
"\u201d": "”",
"\u2018": "‘",
"\u2019": "’",
}
def unpack(
input_file: str,
output_directory: str,
merge_runs: bool = True,
simplify_redlines: bool = True,
) -> tuple[None, str]:
input_path = Path(input_file)
output_path = Path(output_directory)
suffix = input_path.suffix.lower()
if not input_path.exists():
return None, f"Error: {input_file} does not exist"
if suffix not in {".docx", ".pptx", ".xlsx"}:
return None, f"Error: {input_file} must be a .docx, .pptx, or .xlsx file"
try:
output_path.mkdir(parents=True, exist_ok=True)
with zipfile.ZipFile(input_path, "r") as zf:
zf.extractall(output_path)
xml_files = list(output_path.rglob("*.xml")) + list(output_path.rglob("*.rels"))
for xml_file in xml_files:
_pretty_print_xml(xml_file)
message = f"Unpacked {input_file} ({len(xml_files)} XML files)"
if suffix == ".docx":
if simplify_redlines:
simplify_count, _ = do_simplify_redlines(str(output_path))
message += f", simplified {simplify_count} tracked changes"
if merge_runs:
merge_count, _ = do_merge_runs(str(output_path))
message += f", merged {merge_count} runs"
for xml_file in xml_files:
_escape_smart_quotes(xml_file)
return None, message
except zipfile.BadZipFile:
return None, f"Error: {input_file} is not a valid Office file"
except Exception as e:
return None, f"Error unpacking: {e}"
def _pretty_print_xml(xml_file: Path) -> None:
try:
content = xml_file.read_text(encoding="utf-8")
dom = defusedxml.minidom.parseString(content)
xml_file.write_bytes(dom.toprettyxml(indent=" ", encoding="utf-8"))
except Exception:
pass
def _escape_smart_quotes(xml_file: Path) -> None:
try:
content = xml_file.read_text(encoding="utf-8")
for char, entity in SMART_QUOTE_REPLACEMENTS.items():
content = content.replace(char, entity)
xml_file.write_text(content, encoding="utf-8")
except Exception:
pass
if __name__ == "__main__":
parser = argparse.ArgumentParser(
description="Unpack an Office file (DOCX, PPTX, XLSX) for editing"
)
parser.add_argument("input_file", help="Office file to unpack")
parser.add_argument("output_directory", help="Output directory")
parser.add_argument(
"--merge-runs",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Merge adjacent runs with identical formatting (DOCX only, default: true)",
)
parser.add_argument(
"--simplify-redlines",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Merge adjacent tracked changes from same author (DOCX only, default: true)",
)
args = parser.parse_args()
_, message = unpack(
args.input_file,
args.output_directory,
merge_runs=args.merge_runs,
simplify_redlines=args.simplify_redlines,
)
print(message)
if "Error" in message:
sys.exit(1)
```
### scripts/office/validate.py
[Download scripts/office/validate.py](/skills/pptx/scripts/office/validate.py)
```python
"""
Command line tool to validate Office document XML files against XSD schemas and tracked changes.
Usage:
python validate.py [--original ] [--auto-repair] [--author NAME]
The first argument can be either:
- An unpacked directory containing the Office document XML files
- A packed Office file (.docx/.pptx/.xlsx) which will be unpacked to a temp directory
Auto-repair fixes:
- paraId/durableId values that exceed OOXML limits
- Missing xml:space="preserve" on w:t elements with whitespace
"""
import argparse
import sys
import tempfile
import zipfile
from pathlib import Path
from validators import DOCXSchemaValidator, PPTXSchemaValidator, RedliningValidator
def main():
parser = argparse.ArgumentParser(description="Validate Office document XML files")
parser.add_argument(
"path",
help="Path to unpacked directory or packed Office file (.docx/.pptx/.xlsx)",
)
parser.add_argument(
"--original",
required=False,
default=None,
help="Path to original file (.docx/.pptx/.xlsx). If omitted, all XSD errors are reported and redlining validation is skipped.",
)
parser.add_argument(
"-v",
"--verbose",
action="store_true",
help="Enable verbose output",
)
parser.add_argument(
"--auto-repair",
action="store_true",
help="Automatically repair common issues (hex IDs, whitespace preservation)",
)
parser.add_argument(
"--author",
default="Claude",
help="Author name for redlining validation (default: Claude)",
)
args = parser.parse_args()
path = Path(args.path)
assert path.exists(), f"Error: {path} does not exist"
original_file = None
if args.original:
original_file = Path(args.original)
assert original_file.is_file(), f"Error: {original_file} is not a file"
assert original_file.suffix.lower() in [".docx", ".pptx", ".xlsx"], (
f"Error: {original_file} must be a .docx, .pptx, or .xlsx file"
)
file_extension = (original_file or path).suffix.lower()
assert file_extension in [".docx", ".pptx", ".xlsx"], (
f"Error: Cannot determine file type from {path}. Use --original or provide a .docx/.pptx/.xlsx file."
)
if path.is_file() and path.suffix.lower() in [".docx", ".pptx", ".xlsx"]:
temp_dir = tempfile.mkdtemp()
with zipfile.ZipFile(path, "r") as zf:
zf.extractall(temp_dir)
unpacked_dir = Path(temp_dir)
else:
assert path.is_dir(), f"Error: {path} is not a directory or Office file"
unpacked_dir = path
match file_extension:
case ".docx":
validators = [
DOCXSchemaValidator(unpacked_dir, original_file, verbose=args.verbose),
]
if original_file:
validators.append(
RedliningValidator(unpacked_dir, original_file, verbose=args.verbose, author=args.author)
)
case ".pptx":
validators = [
PPTXSchemaValidator(unpacked_dir, original_file, verbose=args.verbose),
]
case _:
print(f"Error: Validation not supported for file type {file_extension}")
sys.exit(1)
if args.auto_repair:
total_repairs = sum(v.repair() for v in validators)
if total_repairs:
print(f"Auto-repaired {total_repairs} issue(s)")
success = all(v.validate() for v in validators)
if success:
print("All validations PASSED!")
sys.exit(0 if success else 1)
if __name__ == "__main__":
main()
```
### scripts/office/validators/__init__.py
[Download scripts/office/validators/__init__.py](/skills/pptx/scripts/office/validators/__init__.py)
```python
"""
Validation modules for Word document processing.
"""
from .base import BaseSchemaValidator
from .docx import DOCXSchemaValidator
from .pptx import PPTXSchemaValidator
from .redlining import RedliningValidator
__all__ = [
"BaseSchemaValidator",
"DOCXSchemaValidator",
"PPTXSchemaValidator",
"RedliningValidator",
]
```
### scripts/office/validators/base.py
[Download scripts/office/validators/base.py](/skills/pptx/scripts/office/validators/base.py)
_Binary resource_
### scripts/office/validators/docx.py
[Download scripts/office/validators/docx.py](/skills/pptx/scripts/office/validators/docx.py)
_Binary resource_
### scripts/office/validators/pptx.py
[Download scripts/office/validators/pptx.py](/skills/pptx/scripts/office/validators/pptx.py)
_Binary resource_
### scripts/office/validators/redlining.py
[Download scripts/office/validators/redlining.py](/skills/pptx/scripts/office/validators/redlining.py)
_Binary resource_
### scripts/thumbnail.py
[Download scripts/thumbnail.py](/skills/pptx/scripts/thumbnail.py)
_Binary resource_
## See in GitHub
[See in GitHub](https://github.com/anthropics/skills/tree/main/pptx)
---
# Skill Creator - The Claude Skill That Builds Skills
URL: http://www.claudeskills.org/docs/skills-cases/skill-creator
Description: How the Skill Creator skill helps Claude scaffold new agent skills: interviews, structure, and packaging - the meta-skill explained.
Source: Content adapted from anthropics/skills (MIT).
A skill for creating new skills and iteratively improving them.
At a high level, the process of creating a skill goes like this:
- Decide what you want the skill to do and roughly how it should do it
- Write a draft of the skill
- Create a few test prompts and run claude-with-access-to-the-skill on them
- Help the user evaluate the results both qualitatively and quantitatively
- While the runs happen in the background, draft some quantitative evals if there aren't any (if there are some, you can either use as is or modify if you feel something needs to change about them). Then explain them to the user (or if they already existed, explain the ones that already exist)
- Use the `eval-viewer/generate_review.py` script to show the user the results for them to look at, and also let them look at the quantitative metrics
- Rewrite the skill based on feedback from the user's evaluation of the results (and also if there are any glaring flaws that become apparent from the quantitative benchmarks)
- Repeat until you're satisfied
- Expand the test set and try again at larger scale
Your job when using this skill is to figure out where the user is in this process and then jump in and help them progress through these stages. So for instance, maybe they're like "I want to make a skill for X". You can help narrow down what they mean, write a draft, write the test cases, figure out how they want to evaluate, run all the prompts, and repeat.
On the other hand, maybe they already have a draft of the skill. In this case you can go straight to the eval/iterate part of the loop.
Of course, you should always be flexible and if the user is like "I don't need to run a bunch of evaluations, just vibe with me", you can do that instead.
Then after the skill is done (but again, the order is flexible), you can also run the skill description improver, which we have a whole separate script for, to optimize the triggering of the skill.
Cool? Cool.
## Communicating with the user
The skill creator is liable to be used by people across a wide range of familiarity with coding jargon. If you haven't heard (and how could you, it's only very recently that it started), there's a trend now where the power of Claude is inspiring plumbers to open up their terminals, parents and grandparents to google "how to install npm". On the other hand, the bulk of users are probably fairly computer-literate.
So please pay attention to context cues to understand how to phrase your communication! In the default case, just to give you some idea:
- "evaluation" and "benchmark" are borderline, but OK
- for "JSON" and "assertion" you want to see serious cues from the user that they know what those things are before using them without explaining them
It's OK to briefly explain terms if you're in doubt, and feel free to clarify terms with a short definition if you're unsure if the user will get it.
---
## Creating a skill
### Capture Intent
Start by understanding the user's intent. The current conversation might already contain a workflow the user wants to capture (e.g., they say "turn this into a skill"). If so, extract answers from the conversation history first - the tools used, the sequence of steps, corrections the user made, input/output formats observed. The user may need to fill the gaps, and should confirm before proceeding to the next step.
1. What should this skill enable Claude to do?
2. When should this skill trigger? (what user phrases/contexts)
3. What's the expected output format?
4. Should we set up test cases to verify the skill works? Skills with objectively verifiable outputs (file transforms, data extraction, code generation, fixed workflow steps) benefit from test cases. Skills with subjective outputs (writing style, art) often don't need them. Suggest the appropriate default based on the skill type, but let the user decide.
### Interview and Research
Proactively ask questions about edge cases, input/output formats, example files, success criteria, and dependencies. Wait to write test prompts until you've got this part ironed out.
Check available MCPs - if useful for research (searching docs, finding similar skills, looking up best practices), research in parallel via subagents if available, otherwise inline. Come prepared with context to reduce burden on the user.
### Write the SKILL.md
Based on the user interview, fill in these components:
- **name**: Skill identifier
- **description**: When to trigger, what it does. This is the primary triggering mechanism - include both what the skill does AND specific contexts for when to use it. All "when to use" info goes here, not in the body. Note: currently Claude has a tendency to "undertrigger" skills -- to not use them when they'd be useful. To combat this, please make the skill descriptions a little bit "pushy". So for instance, instead of "How to build a simple fast dashboard to display internal Anthropic data.", you might write "How to build a simple fast dashboard to display internal Anthropic data. Make sure to use this skill whenever the user mentions dashboards, data visualization, internal metrics, or wants to display any kind of company data, even if they don't explicitly ask for a 'dashboard.'"
- **compatibility**: Required tools, dependencies (optional, rarely needed)
- **the rest of the skill :)**
### Skill Writing Guide
#### Anatomy of a Skill
```
skill-name/
SKILL.md (required)
YAML frontmatter (name, description required)
Markdown instructions
Bundled Resources (optional)
scripts/ - Executable code for deterministic/repetitive tasks
references/ - Docs loaded into context as needed
assets/ - Files used in output (templates, icons, fonts)
```
#### Progressive Disclosure
Skills use a three-level loading system:
1. **Metadata** (name + description) - Always in context (~100 words)
2. **SKILL.md body** - In context whenever skill triggers (<500 lines ideal)
3. **Bundled resources** - As needed (unlimited, scripts can execute without loading)
These word counts are approximate and you can feel free to go longer if needed.
**Key patterns:**
- Keep SKILL.md under 500 lines; if you're approaching this limit, add an additional layer of hierarchy along with clear pointers about where the model using the skill should go next to follow up.
- Reference files clearly from SKILL.md with guidance on when to read them
- For large reference files (>300 lines), include a table of contents
**Domain organization**: When a skill supports multiple domains/frameworks, organize by variant:
```
cloud-deploy/
SKILL.md (workflow + selection)
references/
aws.md
gcp.md
azure.md
```
Claude reads only the relevant reference file.
#### Principle of Lack of Surprise
This goes without saying, but skills must not contain malware, exploit code, or any content that could compromise system security. A skill's contents should not surprise the user in their intent if described. Don't go along with requests to create misleading skills or skills designed to facilitate unauthorized access, data exfiltration, or other malicious activities. Things like a "roleplay as an XYZ" are OK though.
#### Writing Patterns
Prefer using the imperative form in instructions.
**Defining output formats** - You can do it like this:
```markdown
## Report structure
ALWAYS use this exact template:
# [Title]
## Executive summary
## Key findings
## Recommendations
```
**Examples pattern** - It's useful to include examples. You can format them like this (but if "Input" and "Output" are in the examples you might want to deviate a little):
```markdown
## Commit message format
**Example 1:**
Input: Added user authentication with JWT tokens
Output: feat(auth): implement JWT-based authentication
```
### Writing Style
Try to explain to the model why things are important in lieu of heavy-handed musty MUSTs. Use theory of mind and try to make the skill general and not super-narrow to specific examples. Start by writing a draft and then look at it with fresh eyes and improve it.
### Test Cases
After writing the skill draft, come up with 2-3 realistic test prompts - the kind of thing a real user would actually say. Share them with the user: [you don't have to use this exact language] "Here are a few test cases I'd like to try. Do these look right, or do you want to add more?" Then run them.
Save test cases to `evals/evals.json`. Don't write assertions yet - just the prompts. You'll draft assertions in the next step while the runs are in progress.
```json
{
"skill_name": "example-skill",
"evals": [
{
"id": 1,
"prompt": "User's task prompt",
"expected_output": "Description of expected result",
"files": []
}
]
}
```
See `references/schemas.md` for the full schema (including the `assertions` field, which you'll add later).
## Running and evaluating test cases
This section is one continuous sequence - don't stop partway through. Do NOT use `/skill-test` or any other testing skill.
Put results in `<skill-name>-workspace/` as a sibling to the skill directory. Within the workspace, organize results by iteration (`iteration-1/`, `iteration-2/`, etc.) and within that, each test case gets a directory (`eval-0/`, `eval-1/`, etc.). Don't create all of this upfront - just create directories as you go.
### Step 1: Spawn all runs (with-skill AND baseline) in the same turn
For each test case, spawn two subagents in the same turn - one with the skill, one without. This is important: don't spawn the with-skill runs first and then come back for baselines later. Launch everything at once so it all finishes around the same time.
**With-skill run:**
```
Execute this task:
- Skill path:
- Task:
- Input files:
- Save outputs to: /iteration-/eval-/with_skill/outputs/
- Outputs to save:
```
**Baseline run** (same prompt, but the baseline depends on context):
- **Creating a new skill**: no skill at all. Same prompt, no skill path, save to `without_skill/outputs/`.
- **Improving an existing skill**: the old version. Before editing, snapshot the skill (`cp -r <skill-path> <workspace>/skill-snapshot/`), then point the baseline subagent at the snapshot. Save to `old_skill/outputs/`.
Write an `eval_metadata.json` for each test case (assertions can be empty for now). Give each eval a descriptive name based on what it's testing - not just "eval-0". Use this name for the directory too. If this iteration uses new or modified eval prompts, create these files for each new eval directory - don't assume they carry over from previous iterations.
```json
{
"eval_id": 0,
"eval_name": "descriptive-name-here",
"prompt": "The user's task prompt",
"assertions": []
}
```
### Step 2: While runs are in progress, draft assertions
Don't just wait for the runs to finish - you can use this time productively. Draft quantitative assertions for each test case and explain them to the user. If assertions already exist in `evals/evals.json`, review them and explain what they check.
Good assertions are objectively verifiable and have descriptive names - they should read clearly in the benchmark viewer so someone glancing at the results immediately understands what each one checks. Subjective skills (writing style, design quality) are better evaluated qualitatively - don't force assertions onto things that need human judgment.
Update the `eval_metadata.json` files and `evals/evals.json` with the assertions once drafted. Also explain to the user what they'll see in the viewer - both the qualitative outputs and the quantitative benchmark.
### Step 3: As runs complete, capture timing data
When each subagent task completes, you receive a notification containing `total_tokens` and `duration_ms`. Save this data immediately to `timing.json` in the run directory:
```json
{
"total_tokens": 84852,
"duration_ms": 23332,
"total_duration_seconds": 23.3
}
```
This is the only opportunity to capture this data - it comes through the task notification and isn't persisted elsewhere. Process each notification as it arrives rather than trying to batch them.
### Step 4: Grade, aggregate, and launch the viewer
Once all runs are done:
1. **Grade each run** - spawn a grader subagent (or grade inline) that reads `agents/grader.md` and evaluates each assertion against the outputs. Save results to `grading.json` in each run directory. The grading.json expectations array must use the fields `text`, `passed`, and `evidence` (not `name`/`met`/`details` or other variants) - the viewer depends on these exact field names. For assertions that can be checked programmatically, write and run a script rather than eyeballing it - scripts are faster, more reliable, and can be reused across iterations.
2. **Aggregate into benchmark** - run the aggregation script from the skill-creator directory:
```bash
python -m scripts.aggregate_benchmark /iteration-N --skill-name
```
This produces `benchmark.json` and `benchmark.md` with pass_rate, time, and tokens for each configuration, with mean stddev and the delta. If generating benchmark.json manually, see `references/schemas.md` for the exact schema the viewer expects.
Put each with_skill version before its baseline counterpart.
3. **Do an analyst pass** - read the benchmark data and surface patterns the aggregate stats might hide. See `agents/analyzer.md` (the "Analyzing Benchmark Results" section) for what to look for - things like assertions that always pass regardless of skill (non-discriminating), high-variance evals (possibly flaky), and time/token tradeoffs.
4. **Launch the viewer** with both qualitative outputs and quantitative data:
```bash
nohup python /eval-viewer/generate_review.py \
/iteration-N \
--skill-name "my-skill" \
--benchmark /iteration-N/benchmark.json \
> /dev/null 2>&1 &
VIEWER_PID=$!
```
For iteration 2+, also pass `--previous-workspace <workspace>/iteration-<N-1>`.
**Cowork / headless environments:** If `webbrowser.open()` is not available or the environment has no display, use `--static <output_path>` to write a standalone HTML file instead of starting a server. Feedback will be downloaded as a `feedback.json` file when the user clicks "Submit All Reviews". After download, copy `feedback.json` into the workspace directory for the next iteration to pick up.
Note: please use generate_review.py to create the viewer; there's no need to write custom HTML.
5. **Tell the user** something like: "I've opened the results in your browser. There are two tabs - 'Outputs' lets you click through each test case and leave feedback, 'Benchmark' shows the quantitative comparison. When you're done, come back here and let me know."
### What the user sees in the viewer
The "Outputs" tab shows one test case at a time:
- **Prompt**: the task that was given
- **Output**: the files the skill produced, rendered inline where possible
- **Previous Output** (iteration 2+): collapsed section showing last iteration's output
- **Formal Grades** (if grading was run): collapsed section showing assertion pass/fail
- **Feedback**: a textbox that auto-saves as they type
- **Previous Feedback** (iteration 2+): their comments from last time, shown below the textbox
The "Benchmark" tab shows the stats summary: pass rates, timing, and token usage for each configuration, with per-eval breakdowns and analyst observations.
Navigation is via prev/next buttons or arrow keys. When done, they click "Submit All Reviews" which saves all feedback to `feedback.json`.
### Step 5: Read the feedback
When the user tells you they're done, read `feedback.json`:
```json
{
"reviews": [
{"run_id": "eval-0-with_skill", "feedback": "the chart is missing axis labels", "timestamp": "..."},
{"run_id": "eval-1-with_skill", "feedback": "", "timestamp": "..."},
{"run_id": "eval-2-with_skill", "feedback": "perfect, love this", "timestamp": "..."}
],
"status": "complete"
}
```
Empty feedback means the user thought it was fine. Focus your improvements on the test cases where the user had specific complaints.
Kill the viewer server when you're done with it:
```bash
kill $VIEWER_PID 2>/dev/null
```
---
## Improving the skill
This is the heart of the loop. You've run the test cases, the user has reviewed the results, and now you need to make the skill better based on their feedback.
### How to think about improvements
1. **Generalize from the feedback.** The big picture thing that's happening here is that we're trying to create skills that can be used a million times (maybe literally, maybe even more who knows) across many different prompts. Here you and the user are iterating on only a few examples over and over again because it helps move faster. The user knows these examples in and out and it's quick for them to assess new outputs. But if the skill you and the user are codeveloping works only for those examples, it's useless. Rather than put in fiddly overfitty changes, or oppressively constrictive MUSTs, if there's some stubborn issue, you might try branching out and using different metaphors, or recommending different patterns of working. It's relatively cheap to try and maybe you'll land on something great.
2. **Keep the prompt lean.** Remove things that aren't pulling their weight. Make sure to read the transcripts, not just the final outputs - if it looks like the skill is making the model waste a bunch of time doing things that are unproductive, you can try getting rid of the parts of the skill that are making it do that and seeing what happens.
3. **Explain the why.** Try hard to explain the **why** behind everything you're asking the model to do. Today's LLMs are *smart*. They have good theory of mind and when given a good harness can go beyond rote instructions and really make things happen. Even if the feedback from the user is terse or frustrated, try to actually understand the task and why the user is writing what they wrote, and what they actually wrote, and then transmit this understanding into the instructions. If you find yourself writing ALWAYS or NEVER in all caps, or using super rigid structures, that's a yellow flag - if possible, reframe and explain the reasoning so that the model understands why the thing you're asking for is important. That's a more humane, powerful, and effective approach.
4. **Look for repeated work across test cases.** Read the transcripts from the test runs and notice if the subagents all independently wrote similar helper scripts or took the same multi-step approach to something. If all 3 test cases resulted in the subagent writing a `create_docx.py` or a `build_chart.py`, that's a strong signal the skill should bundle that script. Write it once, put it in `scripts/`, and tell the skill to use it. This saves every future invocation from reinventing the wheel.
This task is pretty important (we are trying to create billions a year in economic value here!) and your thinking time is not the blocker; take your time and really mull things over. I'd suggest writing a draft revision and then looking at it anew and making improvements. Really do your best to get into the head of the user and understand what they want and need.
### The iteration loop
After improving the skill:
1. Apply your improvements to the skill
2. Rerun all test cases into a new `iteration-<N+1>/` directory, including baseline runs. If you're creating a new skill, the baseline is always `without_skill` (no skill) - that stays the same across iterations. If you're improving an existing skill, use your judgment on what makes sense as the baseline: the original version the user came in with, or the previous iteration.
3. Launch the reviewer with `--previous-workspace` pointing at the previous iteration
4. Wait for the user to review and tell you they're done
5. Read the new feedback, improve again, repeat
Keep going until:
- The user says they're happy
- The feedback is all empty (everything looks good)
- You're not making meaningful progress
---
## Advanced: Blind comparison
For situations where you want a more rigorous comparison between two versions of a skill (e.g., the user asks "is the new version actually better?"), there's a blind comparison system. Read `agents/comparator.md` and `agents/analyzer.md` for the details. The basic idea is: give two outputs to an independent agent without telling it which is which, and let it judge quality. Then analyze why the winner won.
This is optional, requires subagents, and most users won't need it. The human review loop is usually sufficient.
---
## Description Optimization
The description field in SKILL.md frontmatter is the primary mechanism that determines whether Claude invokes a skill. After creating or improving a skill, offer to optimize the description for better triggering accuracy.
### Step 1: Generate trigger eval queries
Create 20 eval queries - a mix of should-trigger and should-not-trigger. Save as JSON:
```json
[
{"query": "the user prompt", "should_trigger": true},
{"query": "another prompt", "should_trigger": false}
]
```
The queries must be realistic and something a Claude Code or Claude.ai user would actually type. Not abstract requests, but requests that are concrete and specific and have a good amount of detail. For instance, file paths, personal context about the user's job or situation, column names and values, company names, URLs. A little bit of backstory. Some might be in lowercase or contain abbreviations or typos or casual speech. Use a mix of different lengths, and focus on edge cases rather than making them clear-cut (the user will get a chance to sign off on them).
Bad: `"Format this data"`, `"Extract text from PDF"`, `"Create a chart"`
Good: `"ok so my boss just sent me this xlsx file (its in my downloads, called something like 'Q4 sales final FINAL v2.xlsx') and she wants me to add a column that shows the profit margin as a percentage. The revenue is in column C and costs are in column D i think"`
For the **should-trigger** queries (8-10), think about coverage. You want different phrasings of the same intent - some formal, some casual. Include cases where the user doesn't explicitly name the skill or file type but clearly needs it. Throw in some uncommon use cases and cases where this skill competes with another but should win.
For the **should-not-trigger** queries (8-10), the most valuable ones are the near-misses - queries that share keywords or concepts with the skill but actually need something different. Think adjacent domains, ambiguous phrasing where a naive keyword match would trigger but shouldn't, and cases where the query touches on something the skill does but in a context where another tool is more appropriate.
The key thing to avoid: don't make should-not-trigger queries obviously irrelevant. "Write a fibonacci function" as a negative test for a PDF skill is too easy - it doesn't test anything. The negative cases should be genuinely tricky.
### Step 2: Review with user
Present the eval set to the user for review using the HTML template:
1. Read the template from `assets/eval_review.html`
2. Replace the placeholders:
- `__EVAL_DATA_PLACEHOLDER__` -> the JSON array of eval items (no quotes around it - it's a JS variable assignment)
- `__SKILL_NAME_PLACEHOLDER__` -> the skill's name
- `__SKILL_DESCRIPTION_PLACEHOLDER__` -> the skill's current description
3. Write to a temp file (e.g., `/tmp/eval_review_<skill-name>.html`) and open it: `open /tmp/eval_review_<skill-name>.html`
4. The user can edit queries, toggle should-trigger, add/remove entries, then click "Export Eval Set"
5. The file downloads to `~/Downloads/eval_set.json` - check the Downloads folder for the most recent version in case there are multiple (e.g., `eval_set (1).json`)
This step matters - bad eval queries lead to bad descriptions.
### Step 3: Run the optimization loop
Tell the user: "This will take some time - I'll run the optimization loop in the background and check on it periodically."
Save the eval set to the workspace, then run in the background:
```bash
python -m scripts.run_loop \
--eval-set \
--skill-path \
--model \
--max-iterations 5 \
--verbose
```
Use the model ID from your system prompt (the one powering the current session) so the triggering test matches what the user actually experiences.
While it runs, periodically tail the output to give the user updates on which iteration it's on and what the scores look like.
This handles the full optimization loop automatically. It splits the eval set into 60% train and 40% held-out test, evaluates the current description (running each query 3 times to get a reliable trigger rate), then calls Claude to propose improvements based on what failed. It re-evaluates each new description on both train and test, iterating up to 5 times. When it's done, it opens an HTML report in the browser showing the results per iteration and returns JSON with `best_description` - selected by test score rather than train score to avoid overfitting.
### How skill triggering works
Understanding the triggering mechanism helps design better eval queries. Skills appear in Claude's `available_skills` list with their name + description, and Claude decides whether to consult a skill based on that description. The important thing to know is that Claude only consults skills for tasks it can't easily handle on its own - simple, one-step queries like "read this PDF" may not trigger a skill even if the description matches perfectly, because Claude can handle them directly with basic tools. Complex, multi-step, or specialized queries reliably trigger skills when the description matches.
This means your eval queries should be substantive enough that Claude would actually benefit from consulting a skill. Simple queries like "read file X" are poor test cases - they won't trigger skills regardless of description quality.
### Step 4: Apply the result
Take `best_description` from the JSON output and update the skill's SKILL.md frontmatter. Show the user before/after and report the scores.
---
### Package and Present (only if `present_files` tool is available)
Check whether you have access to the `present_files` tool. If you don't, skip this step. If you do, package the skill and present the .skill file to the user:
```bash
python -m scripts.package_skill
```
After packaging, direct the user to the resulting `.skill` file path so they can install it.
---
## Claude.ai-specific instructions
In Claude.ai, the core workflow is the same (draft -> test -> review -> improve -> repeat), but because Claude.ai doesn't have subagents, some mechanics change. Here's what to adapt:
**Running test cases**: No subagents means no parallel execution. For each test case, read the skill's SKILL.md, then follow its instructions to accomplish the test prompt yourself. Do them one at a time. This is less rigorous than independent subagents (you wrote the skill and you're also running it, so you have full context), but it's a useful sanity check - and the human review step compensates. Skip the baseline runs - just use the skill to complete the task as requested.
**Reviewing results**: If you can't open a browser (e.g., Claude.ai's VM has no display, or you're on a remote server), skip the browser reviewer entirely. Instead, present results directly in the conversation. For each test case, show the prompt and the output. If the output is a file the user needs to see (like a .docx or .xlsx), save it to the filesystem and tell them where it is so they can download and inspect it. Ask for feedback inline: "How does this look? Anything you'd change?"
**Benchmarking**: Skip the quantitative benchmarking - it relies on baseline comparisons which aren't meaningful without subagents. Focus on qualitative feedback from the user.
**The iteration loop**: Same as before - improve the skill, rerun the test cases, ask for feedback - just without the browser reviewer in the middle. You can still organize results into iteration directories on the filesystem if you have one.
**Description optimization**: This section requires the `claude` CLI tool (specifically `claude -p`) which is only available in Claude Code. Skip it if you're on Claude.ai.
**Blind comparison**: Requires subagents. Skip it.
**Packaging**: The `package_skill.py` script works anywhere with Python and a filesystem. On Claude.ai, you can run it and the user can download the resulting `.skill` file.
**Updating an existing skill**: The user might be asking you to update an existing skill, not create a new one. In this case:
- **Preserve the original name.** Note the skill's directory name and `name` frontmatter field -- use them unchanged. E.g., if the installed skill is `research-helper`, output `research-helper.skill` (not `research-helper-v2`).
- **Copy to a writeable location before editing.** The installed skill path may be read-only. Copy to `/tmp/skill-name/`, edit there, and package from the copy.
- **If packaging manually, stage in `/tmp/` first**, then copy to the output directory -- direct writes may fail due to permissions.
---
## Cowork-Specific Instructions
If you're in Cowork, the main things to know are:
- You have subagents, so the main workflow (spawn test cases in parallel, run baselines, grade, etc.) all works. (However, if you run into severe problems with timeouts, it's OK to run the test prompts in series rather than parallel.)
- You don't have a browser or display, so when generating the eval viewer, use `--static <output_path>` to write a standalone HTML file instead of starting a server. Then proffer a link that the user can click to open the HTML in their browser.
- For whatever reason, the Cowork setup seems to disincline Claude from generating the eval viewer after running the tests, so just to reiterate: whether you're in Cowork or in Claude Code, after running tests, you should always generate the eval viewer for the human to look at examples before revising the skill yourself and trying to make corrections, using `generate_review.py` (not writing your own boutique html code). Sorry in advance but I'm gonna go all caps here: GENERATE THE EVAL VIEWER *BEFORE* evaluating inputs yourself. You want to get them in front of the human ASAP!
- Feedback works differently: since there's no running server, the viewer's "Submit All Reviews" button will download `feedback.json` as a file. You can then read it from there (you may have to request access first).
- Packaging works - `package_skill.py` just needs Python and a filesystem.
- Description optimization (`run_loop.py` / `run_eval.py`) should work in Cowork just fine since it uses `claude -p` via subprocess, not a browser, but please save it until you've fully finished making the skill and the user agrees it's in good shape.
- **Updating an existing skill**: The user might be asking you to update an existing skill, not create a new one. Follow the update guidance in the claude.ai section above.
---
## Reference files
The agents/ directory contains instructions for specialized subagents. Read them when you need to spawn the relevant subagent.
- `agents/grader.md` - How to evaluate assertions against outputs
- `agents/comparator.md` - How to do blind A/B comparison between two outputs
- `agents/analyzer.md` - How to analyze why one version beat another
The references/ directory has additional documentation:
- `references/schemas.md` - JSON structures for evals.json, grading.json, etc.
---
Repeating one more time the core loop here for emphasis:
- Figure out what the skill is about
- Draft or edit the skill
- Run claude-with-access-to-the-skill on test prompts
- With the user, evaluate the outputs:
- Create benchmark.json and run `eval-viewer/generate_review.py` to help the user review them
- Run quantitative evals
- Repeat until you and the user are satisfied
- Package the final skill and return it to the user.
Please add steps to your TodoList, if you have such a thing, to make sure you don't forget. If you're in Cowork, please specifically put "Create evals JSON and run `eval-viewer/generate_review.py` so human can review test cases" in your TodoList to make sure it happens.
Good luck!
## Resource Files
### LICENSE.txt
[Download LICENSE.txt](/skills/skill-creator/LICENSE.txt)
_Binary resource_
### agents/analyzer.md
[Download agents/analyzer.md](/skills/skill-creator/agents/analyzer.md)
_Binary resource_
### agents/comparator.md
[Download agents/comparator.md](/skills/skill-creator/agents/comparator.md)
_Binary resource_
### agents/grader.md
[Download agents/grader.md](/skills/skill-creator/agents/grader.md)
_Binary resource_
### assets/eval_review.html
[Download assets/eval_review.html](/skills/skill-creator/assets/eval_review.html)
_Binary resource_
### eval-viewer/generate_review.py
[Download eval-viewer/generate_review.py](/skills/skill-creator/eval-viewer/generate_review.py)
_Binary resource_
### eval-viewer/viewer.html
[Download eval-viewer/viewer.html](/skills/skill-creator/eval-viewer/viewer.html)
_Binary resource_
### references/schemas.md
[Download references/schemas.md](/skills/skill-creator/references/schemas.md)
_Binary resource_
### scripts/__init__.py
[Download scripts/__init__.py](/skills/skill-creator/scripts/__init__.py)
_Binary resource_
### scripts/aggregate_benchmark.py
[Download scripts/aggregate_benchmark.py](/skills/skill-creator/scripts/aggregate_benchmark.py)
_Binary resource_
### scripts/generate_report.py
[Download scripts/generate_report.py](/skills/skill-creator/scripts/generate_report.py)
_Binary resource_
### scripts/improve_description.py
[Download scripts/improve_description.py](/skills/skill-creator/scripts/improve_description.py)
_Binary resource_
### scripts/package_skill.py
[Download scripts/package_skill.py](/skills/skill-creator/scripts/package_skill.py)
```python
#!/usr/bin/env python3
"""
Skill Packager - Creates a distributable .skill file of a skill folder
Usage:
python utils/package_skill.py [output-directory]
Example:
python utils/package_skill.py skills/public/my-skill
python utils/package_skill.py skills/public/my-skill ./dist
"""
import fnmatch
import sys
import zipfile
from pathlib import Path
from scripts.quick_validate import validate_skill
# Patterns to exclude when packaging skills.
EXCLUDE_DIRS = {"__pycache__", "node_modules"}
EXCLUDE_GLOBS = {"*.pyc"}
EXCLUDE_FILES = {".DS_Store"}
# Directories excluded only at the skill root (not when nested deeper).
ROOT_EXCLUDE_DIRS = {"evals"}
def should_exclude(rel_path: Path) -> bool:
"""Check if a path should be excluded from packaging."""
parts = rel_path.parts
if any(part in EXCLUDE_DIRS for part in parts):
return True
# rel_path is relative to skill_path.parent, so parts[0] is the skill
# folder name and parts[1] (if present) is the first subdir.
if len(parts) > 1 and parts[1] in ROOT_EXCLUDE_DIRS:
return True
name = rel_path.name
if name in EXCLUDE_FILES:
return True
return any(fnmatch.fnmatch(name, pat) for pat in EXCLUDE_GLOBS)
def package_skill(skill_path, output_dir=None):
"""
Package a skill folder into a .skill file.
Args:
skill_path: Path to the skill folder
output_dir: Optional output directory for the .skill file (defaults to current directory)
Returns:
Path to the created .skill file, or None if error
"""
skill_path = Path(skill_path).resolve()
# Validate skill folder exists
if not skill_path.exists():
print(f"❌ Error: Skill folder not found: {skill_path}")
return None
if not skill_path.is_dir():
print(f"❌ Error: Path is not a directory: {skill_path}")
return None
# Validate SKILL.md exists
skill_md = skill_path / "SKILL.md"
if not skill_md.exists():
print(f"❌ Error: SKILL.md not found in {skill_path}")
return None
# Run validation before packaging
print("🔍 Validating skill...")
valid, message = validate_skill(skill_path)
if not valid:
print(f"❌ Validation failed: {message}")
print(" Please fix the validation errors before packaging.")
return None
print(f"✅ {message}\n")
# Determine output location
skill_name = skill_path.name
if output_dir:
output_path = Path(output_dir).resolve()
output_path.mkdir(parents=True, exist_ok=True)
else:
output_path = Path.cwd()
skill_filename = output_path / f"{skill_name}.skill"
# Create the .skill file (zip format)
try:
with zipfile.ZipFile(skill_filename, 'w', zipfile.ZIP_DEFLATED) as zipf:
# Walk through the skill directory, excluding build artifacts
for file_path in skill_path.rglob('*'):
if not file_path.is_file():
continue
arcname = file_path.relative_to(skill_path.parent)
if should_exclude(arcname):
print(f" Skipped: {arcname}")
continue
zipf.write(file_path, arcname)
print(f" Added: {arcname}")
print(f"\n✅ Successfully packaged skill to: {skill_filename}")
return skill_filename
except Exception as e:
print(f"❌ Error creating .skill file: {e}")
return None
def main():
if len(sys.argv) < 2:
print("Usage: python utils/package_skill.py [output-directory]")
print("\nExample:")
print(" python utils/package_skill.py skills/public/my-skill")
print(" python utils/package_skill.py skills/public/my-skill ./dist")
sys.exit(1)
skill_path = sys.argv[1]
output_dir = sys.argv[2] if len(sys.argv) > 2 else None
print(f"📦 Packaging skill: {skill_path}")
if output_dir:
print(f" Output directory: {output_dir}")
print()
result = package_skill(skill_path, output_dir)
if result:
sys.exit(0)
else:
sys.exit(1)
if __name__ == "__main__":
main()
```
### scripts/quick_validate.py
[Download scripts/quick_validate.py](/skills/skill-creator/scripts/quick_validate.py)
```python
#!/usr/bin/env python3
"""
Quick validation script for skills - minimal version
"""
import sys
import os
import re
import yaml
from pathlib import Path
def validate_skill(skill_path):
"""Basic validation of a skill"""
skill_path = Path(skill_path)
# Check SKILL.md exists
skill_md = skill_path / 'SKILL.md'
if not skill_md.exists():
return False, "SKILL.md not found"
# Read and validate frontmatter
content = skill_md.read_text()
if not content.startswith('---'):
return False, "No YAML frontmatter found"
# Extract frontmatter
match = re.match(r'^---\n(.*?)\n---', content, re.DOTALL)
if not match:
return False, "Invalid frontmatter format"
frontmatter_text = match.group(1)
# Parse YAML frontmatter
try:
frontmatter = yaml.safe_load(frontmatter_text)
if not isinstance(frontmatter, dict):
return False, "Frontmatter must be a YAML dictionary"
except yaml.YAMLError as e:
return False, f"Invalid YAML in frontmatter: {e}"
# Define allowed properties
ALLOWED_PROPERTIES = {'name', 'description', 'license', 'allowed-tools', 'metadata', 'compatibility'}
# Check for unexpected properties (excluding nested keys under metadata)
unexpected_keys = set(frontmatter.keys()) - ALLOWED_PROPERTIES
if unexpected_keys:
return False, (
f"Unexpected key(s) in SKILL.md frontmatter: {', '.join(sorted(unexpected_keys))}. "
f"Allowed properties are: {', '.join(sorted(ALLOWED_PROPERTIES))}"
)
# Check required fields
if 'name' not in frontmatter:
return False, "Missing 'name' in frontmatter"
if 'description' not in frontmatter:
return False, "Missing 'description' in frontmatter"
# Extract name for validation
name = frontmatter.get('name', '')
if not isinstance(name, str):
return False, f"Name must be a string, got {type(name).__name__}"
name = name.strip()
if name:
# Check naming convention (kebab-case: lowercase with hyphens)
if not re.match(r'^[a-z0-9-]+$', name):
return False, f"Name '{name}' should be kebab-case (lowercase letters, digits, and hyphens only)"
if name.startswith('-') or name.endswith('-') or '--' in name:
return False, f"Name '{name}' cannot start/end with hyphen or contain consecutive hyphens"
# Check name length (max 64 characters per spec)
if len(name) > 64:
return False, f"Name is too long ({len(name)} characters). Maximum is 64 characters."
# Extract and validate description
description = frontmatter.get('description', '')
if not isinstance(description, str):
return False, f"Description must be a string, got {type(description).__name__}"
description = description.strip()
if description:
# Check for angle brackets
if '<' in description or '>' in description:
return False, "Description cannot contain angle brackets (< or >)"
# Check description length (max 1024 characters per spec)
if len(description) > 1024:
return False, f"Description is too long ({len(description)} characters). Maximum is 1024 characters."
# Validate compatibility field if present (optional)
compatibility = frontmatter.get('compatibility', '')
if compatibility:
if not isinstance(compatibility, str):
return False, f"Compatibility must be a string, got {type(compatibility).__name__}"
if len(compatibility) > 500:
return False, f"Compatibility is too long ({len(compatibility)} characters). Maximum is 500 characters."
return True, "Skill is valid!"
if __name__ == "__main__":
if len(sys.argv) != 2:
print("Usage: python quick_validate.py ")
sys.exit(1)
valid, message = validate_skill(sys.argv[1])
print(message)
sys.exit(0 if valid else 1)
```
### scripts/run_eval.py
[Download scripts/run_eval.py](/skills/skill-creator/scripts/run_eval.py)
_Binary resource_
### scripts/run_loop.py
[Download scripts/run_loop.py](/skills/skill-creator/scripts/run_loop.py)
_Binary resource_
### scripts/utils.py
[Download scripts/utils.py](/skills/skill-creator/scripts/utils.py)
```python
"""Shared utilities for skill-creator scripts."""
from pathlib import Path
def parse_skill_md(skill_path: Path) -> tuple[str, str, str]:
"""Parse a SKILL.md file, returning (name, description, full_content)."""
content = (skill_path / "SKILL.md").read_text()
lines = content.split("\n")
if lines[0].strip() != "---":
raise ValueError("SKILL.md missing frontmatter (no opening ---)")
end_idx = None
for i, line in enumerate(lines[1:], start=1):
if line.strip() == "---":
end_idx = i
break
if end_idx is None:
raise ValueError("SKILL.md missing frontmatter (no closing ---)")
name = ""
description = ""
frontmatter_lines = lines[1:end_idx]
i = 0
while i < len(frontmatter_lines):
line = frontmatter_lines[i]
if line.startswith("name:"):
name = line[len("name:"):].strip().strip('"').strip("'")
elif line.startswith("description:"):
value = line[len("description:"):].strip()
# Handle YAML multiline indicators (>, |, >-, |-)
if value in (">", "|", ">-", "|-"):
continuation_lines: list[str] = []
i += 1
while i < len(frontmatter_lines) and (frontmatter_lines[i].startswith(" ") or frontmatter_lines[i].startswith("\t")):
continuation_lines.append(frontmatter_lines[i].strip())
i += 1
description = " ".join(continuation_lines)
continue
else:
description = value.strip('"').strip("'")
i += 1
return name, description, content
```
## See in GitHub
[See in GitHub](https://github.com/anthropics/skills/tree/main/skill-creator)
---
# Slack GIF Creator Skill - Custom GIFs with Claude
URL: http://www.claudeskills.org/docs/skills-cases/slack-gif-creator
Description: How the Slack GIF Creator skill generates reaction GIFs sized for Slack with animation presets - full skill walkthrough.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Knowledge and utilities for creating animated GIFs optimized for Slack. Provides constraints, validation tools, and animation concepts. Use when users request animated GIFs for Slack like 'make me a GIF of X doing Y for Slack.'"*
## How the skill works
The SKILL.md pairs Slack's hard requirements (dimensions, file size) with a small Python animation toolkit:
- **Core workflow** - draw graphics (from scratch or from user-uploaded images), compose frames, build the GIF, validate against Slack constraints
- **`core.gif_builder`** - GIFBuilder assembles frames into a compliant GIF
- **`core.validators`** - checks size and dimension limits before you ship
- **`core.easing` + `core.frame_composer`** - easing functions and frame helpers for smooth motion
- **Animation concepts** - named recipes like shake/vibrate and pulse/heartbeat that map user requests to concrete frame math
## What's inside the skill folder
- `core/gif_builder.py`, `core/validators.py`, `core/easing.py`, `core/frame_composer.py`
- `requirements.txt`, `SKILL.md`, `LICENSE.txt`
## Key takeaways for your own skills
- **Constraints first**: encoding the platform's limits as a validator means output is correct by construction, not by luck.
- Naming animation concepts ("pulse", "shake") gives users a vocabulary the skill can reliably map to code.
## See it on GitHub
[skills/slack-gif-creator](https://github.com/anthropics/skills/tree/main/skills/slack-gif-creator)
---
# Claude Skill Template - Structure & Boilerplate Explained
URL: http://www.claudeskills.org/docs/skills-cases/template-skill
Description: A reusable Claude skill template: SKILL.md structure, frontmatter, trigger description, and resources - copy it to build your own agent skill.
Source: Content adapted from anthropics/skills (MIT).
## See in GitHub
[See in GitHub](https://github.com/anthropics/skills/tree/main/template)
---
# Theme Factory - Claude Skill for Artifact Themes
URL: http://www.claudeskills.org/docs/skills-cases/theme-factory
Description: The Theme Factory skill applies polished visual themes to Claude artifacts: palettes, fonts, and styling presets - see how it works inside.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Toolkit for styling artifacts with a theme. These artifacts can be slides, docs, reports, HTML landing pages, etc. There are 10 pre-set themes with colors/fonts that you can apply to any artifact that has been created, or can generate a new theme on-the-fly."*
## How the skill works
The workflow is deliberately simple: pick (or generate) a theme, then apply its palette and type pairing to whatever artifact Claude just built. The SKILL.md covers usage instructions, the theme catalog, per-theme details, the application process, and how to create a custom theme when none of the presets fit.
## The 10 built-in themes
Each theme ships as its own markdown spec under `themes/`:
`arctic-frost`, `botanical-garden`, `desert-rose`, `forest-canopy`, `golden-hour`, `midnight-galaxy`, `modern-minimalist`, `ocean-depths`, `sunset-boulevard` - plus a showcase PDF (`theme-showcase.pdf`) that previews them side by side.
## What's inside the skill folder
- `SKILL.md` - selection and application logic
- `themes/*.md` - 10 theme specs (colors, fonts, styling notes)
- `theme-showcase.pdf` - visual preview of every preset
- `LICENSE.txt`
## Key takeaways for your own skills
- Shipping **data as files** (10 theme specs) instead of inlining everything keeps the skill's context footprint small - Claude loads only the theme it needs.
- A visual showcase asset lets users choose by looking rather than reading hex values.
## See it on GitHub
[skills/theme-factory](https://github.com/anthropics/skills/tree/main/skills/theme-factory)
---
# Webapp Testing Skill - Browser Testing with Claude
URL: http://www.claudeskills.org/docs/skills-cases/webapp-testing
Description: The Webapp Testing skill lets Claude drive a browser with Playwright: click flows, screenshots, and debugging - full SKILL.md explained.
Source: Content adapted from [anthropics/skills](https://github.com/anthropics/skills) (MIT). Last synced July 8, 2026, against the April 20, 2026 upstream update.
## Overview
The official description: *"Toolkit for interacting with and testing local web applications using Playwright. Supports verifying frontend functionality, debugging UI behavior, capturing browser screenshots, and viewing browser logs."*
## How the skill works
The SKILL.md is organized around a **decision tree**: Claude first chooses the right approach for the task (static HTML vs a running dev server vs an already-running app), then applies a **reconnaissance-then-action pattern** - discover elements and state first, act second. It also documents the most common pitfall (acting on elements before the page settles) and a set of best practices for stable automation.
The centerpiece utility is `scripts/with_server.py`, which starts your dev server, waits until it is ready, runs the Playwright interaction, and tears everything down cleanly.
## What's inside the skill folder
- `scripts/with_server.py` - server lifecycle wrapper for tests
- `examples/static_html_automation.py` - driving static pages
- `examples/element_discovery.py` - the reconnaissance pattern in code
- `examples/console_logging.py` - capturing browser logs
- `SKILL.md`, `LICENSE.txt`
## Key takeaways for your own skills
- Put **decision trees at the top**: routing Claude to the right sub-workflow early prevents most tool misuse.
- Worked examples (three runnable scripts) teach faster than API documentation.
## See it on GitHub
[skills/webapp-testing](https://github.com/anthropics/skills/tree/main/skills/webapp-testing)
---
# Xlsx Skill - Build & Analyze Spreadsheets with Claude
URL: http://www.claudeskills.org/docs/skills-cases/xlsx
Description: The Xlsx skill covers spreadsheet creation, formulas, formatting, and data analysis in Claude - see exactly how the skill is written and triggered.
Source: Content adapted from anthropics/skills (MIT).
## All Excel files
### Professional Font
- Use a consistent, professional font (e.g., Arial, Times New Roman) for all deliverables unless otherwise instructed by the user
### Zero Formula Errors
- Every Excel model MUST be delivered with ZERO formula errors (#REF!, #DIV/0!, #VALUE!, #N/A, #NAME?)
### Preserve Existing Templates (when updating templates)
- Study and EXACTLY match existing format, style, and conventions when modifying files
- Never impose standardized formatting on files with established patterns
- Existing template conventions ALWAYS override these guidelines
## Financial models
### Color Coding Standards
Unless otherwise stated by the user or existing template
#### Industry-Standard Color Conventions
- **Blue text (RGB: 0,0,255)**: Hardcoded inputs, and numbers users will change for scenarios
- **Black text (RGB: 0,0,0)**: ALL formulas and calculations
- **Green text (RGB: 0,128,0)**: Links pulling from other worksheets within same workbook
- **Red text (RGB: 255,0,0)**: External links to other files
- **Yellow background (RGB: 255,255,0)**: Key assumptions needing attention or cells that need to be updated
### Number Formatting Standards
#### Required Format Rules
- **Years**: Format as text strings (e.g., "2024" not "2,024")
- **Currency**: Use $#,##0 format; ALWAYS specify units in headers ("Revenue ($mm)")
- **Zeros**: Use number formatting to make all zeros "-", including percentages (e.g., "$#,##0;($#,##0);-")
- **Percentages**: Default to 0.0% format (one decimal)
- **Multiples**: Format as 0.0x for valuation multiples (EV/EBITDA, P/E)
- **Negative numbers**: Use parentheses (123) not minus -123
### Formula Construction Rules
#### Assumptions Placement
- Place ALL assumptions (growth rates, margins, multiples, etc.) in separate assumption cells
- Use cell references instead of hardcoded values in formulas
- Example: Use =B5*(1+$B$6) instead of =B5*1.05
#### Formula Error Prevention
- Verify all cell references are correct
- Check for off-by-one errors in ranges
- Ensure consistent formulas across all projection periods
- Test with edge cases (zero values, negative numbers)
- Verify no unintended circular references
#### Documentation Requirements for Hardcodes
- Comment or in cells beside (if end of table). Format: "Source: [System/Document], [Date], [Specific Reference], [URL if applicable]"
- Examples:
- "Source: Company 10-K, FY2024, Page 45, Revenue Note, [SEC EDGAR URL]"
- "Source: Company 10-Q, Q2 2025, Exhibit 99.1, [SEC EDGAR URL]"
- "Source: Bloomberg Terminal, 8/15/2025, AAPL US Equity"
- "Source: FactSet, 8/20/2025, Consensus Estimates Screen"
# XLSX creation, editing, and analysis
## Overview
A user may ask you to create, edit, or analyze the contents of an .xlsx file. You have different tools and workflows available for different tasks.
## Important Requirements
**LibreOffice Required for Formula Recalculation**: You can assume LibreOffice is installed for recalculating formula values using the `scripts/recalc.py` script. The script automatically configures LibreOffice on first run, including in sandboxed environments where Unix sockets are restricted (handled by `scripts/office/soffice.py`)
## Reading and analyzing data
### Data analysis with pandas
For data analysis, visualization, and basic operations, use **pandas** which provides powerful data manipulation capabilities:
```python
import pandas as pd
# Read Excel
df = pd.read_excel('file.xlsx') # Default: first sheet
all_sheets = pd.read_excel('file.xlsx', sheet_name=None) # All sheets as dict
# Analyze
df.head() # Preview data
df.info() # Column info
df.describe() # Statistics
# Write Excel
df.to_excel('output.xlsx', index=False)
```
## Excel File Workflows
## CRITICAL: Use Formulas, Not Hardcoded Values
**Always use Excel formulas instead of calculating values in Python and hardcoding them.** This ensures the spreadsheet remains dynamic and updateable.
### WRONG - Hardcoding Calculated Values
```python
# Bad: Calculating in Python and hardcoding result
total = df['Sales'].sum()
sheet['B10'] = total # Hardcodes 5000
# Bad: Computing growth rate in Python
growth = (df.iloc[-1]['Revenue'] - df.iloc[0]['Revenue']) / df.iloc[0]['Revenue']
sheet['C5'] = growth # Hardcodes 0.15
# Bad: Python calculation for average
avg = sum(values) / len(values)
sheet['D20'] = avg # Hardcodes 42.5
```
### CORRECT - Using Excel Formulas
```python
# Good: Let Excel calculate the sum
sheet['B10'] = '=SUM(B2:B9)'
# Good: Growth rate as Excel formula
sheet['C5'] = '=(C4-C2)/C2'
# Good: Average using Excel function
sheet['D20'] = '=AVERAGE(D2:D19)'
```
This applies to ALL calculations - totals, percentages, ratios, differences, etc. The spreadsheet should be able to recalculate when source data changes.
## Common Workflow
1. **Choose tool**: pandas for data, openpyxl for formulas/formatting
2. **Create/Load**: Create new workbook or load existing file
3. **Modify**: Add/edit data, formulas, and formatting
4. **Save**: Write to file
5. **Recalculate formulas (MANDATORY IF USING FORMULAS)**: Use the scripts/recalc.py script
```bash
python scripts/recalc.py output.xlsx
```
6. **Verify and fix any errors**:
- The script returns JSON with error details
- If `status` is `errors_found`, check `error_summary` for specific error types and locations
- Fix the identified errors and recalculate again
- Common errors to fix:
- `#REF!`: Invalid cell references
- `#DIV/0!`: Division by zero
- `#VALUE!`: Wrong data type in formula
- `#NAME?`: Unrecognized formula name
### Creating new Excel files
```python
# Using openpyxl for formulas and formatting
from openpyxl import Workbook
from openpyxl.styles import Font, PatternFill, Alignment
wb = Workbook()
sheet = wb.active
# Add data
sheet['A1'] = 'Hello'
sheet['B1'] = 'World'
sheet.append(['Row', 'of', 'data'])
# Add formula
sheet['B2'] = '=SUM(A1:A10)'
# Formatting
sheet['A1'].font = Font(bold=True, color='FF0000')
sheet['A1'].fill = PatternFill('solid', start_color='FFFF00')
sheet['A1'].alignment = Alignment(horizontal='center')
# Column width
sheet.column_dimensions['A'].width = 20
wb.save('output.xlsx')
```
### Editing existing Excel files
```python
# Using openpyxl to preserve formulas and formatting
from openpyxl import load_workbook
# Load existing file
wb = load_workbook('existing.xlsx')
sheet = wb.active # or wb['SheetName'] for specific sheet
# Working with multiple sheets
for sheet_name in wb.sheetnames:
sheet = wb[sheet_name]
print(f"Sheet: {sheet_name}")
# Modify cells
sheet['A1'] = 'New Value'
sheet.insert_rows(2) # Insert row at position 2
sheet.delete_cols(3) # Delete column 3
# Add new sheet
new_sheet = wb.create_sheet('NewSheet')
new_sheet['A1'] = 'Data'
wb.save('modified.xlsx')
```
## Recalculating formulas
Excel files created or modified by openpyxl contain formulas as strings but not calculated values. Use the provided `scripts/recalc.py` script to recalculate formulas:
```bash
python scripts/recalc.py [timeout_seconds]
```
Example:
```bash
python scripts/recalc.py output.xlsx 30
```
The script:
- Automatically sets up LibreOffice macro on first run
- Recalculates all formulas in all sheets
- Scans ALL cells for Excel errors (#REF!, #DIV/0!, etc.)
- Returns JSON with detailed error locations and counts
- Works on both Linux and macOS
## Formula Verification Checklist
Quick checks to ensure formulas work correctly:
### Essential Verification
- [ ] **Test 2-3 sample references**: Verify they pull correct values before building full model
- [ ] **Column mapping**: Confirm Excel columns match (e.g., column 64 = BL, not BK)
- [ ] **Row offset**: Remember Excel rows are 1-indexed (DataFrame row 5 = Excel row 6)
### Common Pitfalls
- [ ] **NaN handling**: Check for null values with `pd.notna()`
- [ ] **Far-right columns**: FY data often in columns 50+
- [ ] **Multiple matches**: Search all occurrences, not just first
- [ ] **Division by zero**: Check denominators before using `/` in formulas (#DIV/0!)
- [ ] **Wrong references**: Verify all cell references point to intended cells (#REF!)
- [ ] **Cross-sheet references**: Use correct format (Sheet1!A1) for linking sheets
### Formula Testing Strategy
- [ ] **Start small**: Test formulas on 2-3 cells before applying broadly
- [ ] **Verify dependencies**: Check all cells referenced in formulas exist
- [ ] **Test edge cases**: Include zero, negative, and very large values
### Interpreting scripts/recalc.py Output
The script returns JSON with error details:
```json
{
"status": "success", // or "errors_found"
"total_errors": 0, // Total error count
"total_formulas": 42, // Number of formulas in file
"error_summary": { // Only present if errors found
"#REF!": {
"count": 2,
"locations": ["Sheet1!B5", "Sheet1!C10"]
}
}
}
```
## Best Practices
### Library Selection
- **pandas**: Best for data analysis, bulk operations, and simple data export
- **openpyxl**: Best for complex formatting, formulas, and Excel-specific features
### Working with openpyxl
- Cell indices are 1-based (row=1, column=1 refers to cell A1)
- Use `data_only=True` to read calculated values: `load_workbook('file.xlsx', data_only=True)`
- **Warning**: If opened with `data_only=True` and saved, formulas are replaced with values and permanently lost
- For large files: Use `read_only=True` for reading or `write_only=True` for writing
- Formulas are preserved but not evaluated - use scripts/recalc.py to update values
### Working with pandas
- Specify data types to avoid inference issues: `pd.read_excel('file.xlsx', dtype={'id': str})`
- For large files, read specific columns: `pd.read_excel('file.xlsx', usecols=['A', 'C', 'E'])`
- Handle dates properly: `pd.read_excel('file.xlsx', parse_dates=['date_column'])`
## Code Style Guidelines
**IMPORTANT**: When generating Python code for Excel operations:
- Write minimal, concise Python code without unnecessary comments
- Avoid verbose variable names and redundant operations
- Avoid unnecessary print statements
**For Excel files themselves**:
- Add comments to cells with complex formulas or important assumptions
- Document data sources for hardcoded values
- Include notes for key calculations and model sections
## Resource Files
### LICENSE.txt
[Download LICENSE.txt](/skills/xlsx/LICENSE.txt)
_Binary resource_
### scripts/office/helpers/__init__.py
[Download scripts/office/helpers/__init__.py](/skills/xlsx/scripts/office/helpers/__init__.py)
_Binary resource_
### scripts/office/helpers/merge_runs.py
[Download scripts/office/helpers/merge_runs.py](/skills/xlsx/scripts/office/helpers/merge_runs.py)
```python
"""Merge adjacent runs with identical formatting in DOCX.
Merges adjacent elements that have identical properties.
Works on runs in paragraphs and inside tracked changes (, ).
Also:
- Removes rsid attributes from runs (revision metadata that doesn't affect rendering)
- Removes proofErr elements (spell/grammar markers that block merging)
"""
from pathlib import Path
import defusedxml.minidom
def merge_runs(input_dir: str) -> tuple[int, str]:
doc_xml = Path(input_dir) / "word" / "document.xml"
if not doc_xml.exists():
return 0, f"Error: {doc_xml} not found"
try:
dom = defusedxml.minidom.parseString(doc_xml.read_text(encoding="utf-8"))
root = dom.documentElement
_remove_elements(root, "proofErr")
_strip_run_rsid_attrs(root)
containers = {run.parentNode for run in _find_elements(root, "r")}
merge_count = 0
for container in containers:
merge_count += _merge_runs_in(container)
doc_xml.write_bytes(dom.toxml(encoding="UTF-8"))
return merge_count, f"Merged {merge_count} runs"
except Exception as e:
return 0, f"Error: {e}"
def _find_elements(root, tag: str) -> list:
results = []
def traverse(node):
if node.nodeType == node.ELEMENT_NODE:
name = node.localName or node.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(node)
for child in node.childNodes:
traverse(child)
traverse(root)
return results
def _get_child(parent, tag: str):
for child in parent.childNodes:
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name == tag or name.endswith(f":{tag}"):
return child
return None
def _get_children(parent, tag: str) -> list:
results = []
for child in parent.childNodes:
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(child)
return results
def _is_adjacent(elem1, elem2) -> bool:
node = elem1.nextSibling
while node:
if node == elem2:
return True
if node.nodeType == node.ELEMENT_NODE:
return False
if node.nodeType == node.TEXT_NODE and node.data.strip():
return False
node = node.nextSibling
return False
def _remove_elements(root, tag: str):
for elem in _find_elements(root, tag):
if elem.parentNode:
elem.parentNode.removeChild(elem)
def _strip_run_rsid_attrs(root):
for run in _find_elements(root, "r"):
for attr in list(run.attributes.values()):
if "rsid" in attr.name.lower():
run.removeAttribute(attr.name)
def _merge_runs_in(container) -> int:
merge_count = 0
run = _first_child_run(container)
while run:
while True:
next_elem = _next_element_sibling(run)
if next_elem and _is_run(next_elem) and _can_merge(run, next_elem):
_merge_run_content(run, next_elem)
container.removeChild(next_elem)
merge_count += 1
else:
break
_consolidate_text(run)
run = _next_sibling_run(run)
return merge_count
def _first_child_run(container):
for child in container.childNodes:
if child.nodeType == child.ELEMENT_NODE and _is_run(child):
return child
return None
def _next_element_sibling(node):
sibling = node.nextSibling
while sibling:
if sibling.nodeType == sibling.ELEMENT_NODE:
return sibling
sibling = sibling.nextSibling
return None
def _next_sibling_run(node):
sibling = node.nextSibling
while sibling:
if sibling.nodeType == sibling.ELEMENT_NODE:
if _is_run(sibling):
return sibling
sibling = sibling.nextSibling
return None
def _is_run(node) -> bool:
name = node.localName or node.tagName
return name == "r" or name.endswith(":r")
def _can_merge(run1, run2) -> bool:
rpr1 = _get_child(run1, "rPr")
rpr2 = _get_child(run2, "rPr")
if (rpr1 is None) != (rpr2 is None):
return False
if rpr1 is None:
return True
return rpr1.toxml() == rpr2.toxml()
def _merge_run_content(target, source):
for child in list(source.childNodes):
if child.nodeType == child.ELEMENT_NODE:
name = child.localName or child.tagName
if name != "rPr" and not name.endswith(":rPr"):
target.appendChild(child)
def _consolidate_text(run):
t_elements = _get_children(run, "t")
for i in range(len(t_elements) - 1, 0, -1):
curr, prev = t_elements[i], t_elements[i - 1]
if _is_adjacent(prev, curr):
prev_text = prev.firstChild.data if prev.firstChild else ""
curr_text = curr.firstChild.data if curr.firstChild else ""
merged = prev_text + curr_text
if prev.firstChild:
prev.firstChild.data = merged
else:
prev.appendChild(run.ownerDocument.createTextNode(merged))
if merged.startswith(" ") or merged.endswith(" "):
prev.setAttribute("xml:space", "preserve")
elif prev.hasAttribute("xml:space"):
prev.removeAttribute("xml:space")
run.removeChild(curr)
```
### scripts/office/helpers/simplify_redlines.py
[Download scripts/office/helpers/simplify_redlines.py](/skills/xlsx/scripts/office/helpers/simplify_redlines.py)
```python
"""Simplify tracked changes by merging adjacent w:ins or w:del elements.
Merges adjacent elements from the same author into a single element.
Same for elements. This makes heavily-redlined documents easier to
work with by reducing the number of tracked change wrappers.
Rules:
- Only merges w:ins with w:ins, w:del with w:del (same element type)
- Only merges if same author (ignores timestamp differences)
- Only merges if truly adjacent (only whitespace between them)
"""
import xml.etree.ElementTree as ET
import zipfile
from pathlib import Path
import defusedxml.minidom
WORD_NS = "http://schemas.openxmlformats.org/wordprocessingml/2006/main"
def simplify_redlines(input_dir: str) -> tuple[int, str]:
doc_xml = Path(input_dir) / "word" / "document.xml"
if not doc_xml.exists():
return 0, f"Error: {doc_xml} not found"
try:
dom = defusedxml.minidom.parseString(doc_xml.read_text(encoding="utf-8"))
root = dom.documentElement
merge_count = 0
containers = _find_elements(root, "p") + _find_elements(root, "tc")
for container in containers:
merge_count += _merge_tracked_changes_in(container, "ins")
merge_count += _merge_tracked_changes_in(container, "del")
doc_xml.write_bytes(dom.toxml(encoding="UTF-8"))
return merge_count, f"Simplified {merge_count} tracked changes"
except Exception as e:
return 0, f"Error: {e}"
def _merge_tracked_changes_in(container, tag: str) -> int:
merge_count = 0
tracked = [
child
for child in container.childNodes
if child.nodeType == child.ELEMENT_NODE and _is_element(child, tag)
]
if len(tracked) < 2:
return 0
i = 0
while i < len(tracked) - 1:
curr = tracked[i]
next_elem = tracked[i + 1]
if _can_merge_tracked(curr, next_elem):
_merge_tracked_content(curr, next_elem)
container.removeChild(next_elem)
tracked.pop(i + 1)
merge_count += 1
else:
i += 1
return merge_count
def _is_element(node, tag: str) -> bool:
name = node.localName or node.tagName
return name == tag or name.endswith(f":{tag}")
def _get_author(elem) -> str:
author = elem.getAttribute("w:author")
if not author:
for attr in elem.attributes.values():
if attr.localName == "author" or attr.name.endswith(":author"):
return attr.value
return author
def _can_merge_tracked(elem1, elem2) -> bool:
if _get_author(elem1) != _get_author(elem2):
return False
node = elem1.nextSibling
while node and node != elem2:
if node.nodeType == node.ELEMENT_NODE:
return False
if node.nodeType == node.TEXT_NODE and node.data.strip():
return False
node = node.nextSibling
return True
def _merge_tracked_content(target, source):
while source.firstChild:
child = source.firstChild
source.removeChild(child)
target.appendChild(child)
def _find_elements(root, tag: str) -> list:
results = []
def traverse(node):
if node.nodeType == node.ELEMENT_NODE:
name = node.localName or node.tagName
if name == tag or name.endswith(f":{tag}"):
results.append(node)
for child in node.childNodes:
traverse(child)
traverse(root)
return results
def get_tracked_change_authors(doc_xml_path: Path) -> dict[str, int]:
if not doc_xml_path.exists():
return {}
try:
tree = ET.parse(doc_xml_path)
root = tree.getroot()
except ET.ParseError:
return {}
namespaces = {"w": WORD_NS}
author_attr = f"{{{WORD_NS}}}author"
authors: dict[str, int] = {}
for tag in ["ins", "del"]:
for elem in root.findall(f".//w:{tag}", namespaces):
author = elem.get(author_attr)
if author:
authors[author] = authors.get(author, 0) + 1
return authors
def _get_authors_from_docx(docx_path: Path) -> dict[str, int]:
try:
with zipfile.ZipFile(docx_path, "r") as zf:
if "word/document.xml" not in zf.namelist():
return {}
with zf.open("word/document.xml") as f:
tree = ET.parse(f)
root = tree.getroot()
namespaces = {"w": WORD_NS}
author_attr = f"{{{WORD_NS}}}author"
authors: dict[str, int] = {}
for tag in ["ins", "del"]:
for elem in root.findall(f".//w:{tag}", namespaces):
author = elem.get(author_attr)
if author:
authors[author] = authors.get(author, 0) + 1
return authors
except (zipfile.BadZipFile, ET.ParseError):
return {}
def infer_author(modified_dir: Path, original_docx: Path, default: str = "Claude") -> str:
modified_xml = modified_dir / "word" / "document.xml"
modified_authors = get_tracked_change_authors(modified_xml)
if not modified_authors:
return default
original_authors = _get_authors_from_docx(original_docx)
new_changes: dict[str, int] = {}
for author, count in modified_authors.items():
original_count = original_authors.get(author, 0)
diff = count - original_count
if diff > 0:
new_changes[author] = diff
if not new_changes:
return default
if len(new_changes) == 1:
return next(iter(new_changes))
raise ValueError(
f"Multiple authors added new changes: {new_changes}. "
"Cannot infer which author to validate."
)
```
### scripts/office/pack.py
[Download scripts/office/pack.py](/skills/xlsx/scripts/office/pack.py)
```python
"""Pack a directory into a DOCX, PPTX, or XLSX file.
Validates with auto-repair, condenses XML formatting, and creates the Office file.
Usage:
python pack.py [--original ] [--validate true|false]
Examples:
python pack.py unpacked/ output.docx --original input.docx
python pack.py unpacked/ output.pptx --validate false
"""
import argparse
import sys
import shutil
import tempfile
import zipfile
from pathlib import Path
import defusedxml.minidom
from validators import DOCXSchemaValidator, PPTXSchemaValidator, RedliningValidator
def pack(
input_directory: str,
output_file: str,
original_file: str | None = None,
validate: bool = True,
infer_author_func=None,
) -> tuple[None, str]:
input_dir = Path(input_directory)
output_path = Path(output_file)
suffix = output_path.suffix.lower()
if not input_dir.is_dir():
return None, f"Error: {input_dir} is not a directory"
if suffix not in {".docx", ".pptx", ".xlsx"}:
return None, f"Error: {output_file} must be a .docx, .pptx, or .xlsx file"
if validate and original_file:
original_path = Path(original_file)
if original_path.exists():
success, output = _run_validation(
input_dir, original_path, suffix, infer_author_func
)
if output:
print(output)
if not success:
return None, f"Error: Validation failed for {input_dir}"
with tempfile.TemporaryDirectory() as temp_dir:
temp_content_dir = Path(temp_dir) / "content"
shutil.copytree(input_dir, temp_content_dir)
for pattern in ["*.xml", "*.rels"]:
for xml_file in temp_content_dir.rglob(pattern):
_condense_xml(xml_file)
output_path.parent.mkdir(parents=True, exist_ok=True)
with zipfile.ZipFile(output_path, "w", zipfile.ZIP_DEFLATED) as zf:
for f in temp_content_dir.rglob("*"):
if f.is_file():
zf.write(f, f.relative_to(temp_content_dir))
return None, f"Successfully packed {input_dir} to {output_file}"
def _run_validation(
unpacked_dir: Path,
original_file: Path,
suffix: str,
infer_author_func=None,
) -> tuple[bool, str | None]:
output_lines = []
validators = []
if suffix == ".docx":
author = "Claude"
if infer_author_func:
try:
author = infer_author_func(unpacked_dir, original_file)
except ValueError as e:
print(f"Warning: {e} Using default author 'Claude'.", file=sys.stderr)
validators = [
DOCXSchemaValidator(unpacked_dir, original_file),
RedliningValidator(unpacked_dir, original_file, author=author),
]
elif suffix == ".pptx":
validators = [PPTXSchemaValidator(unpacked_dir, original_file)]
if not validators:
return True, None
total_repairs = sum(v.repair() for v in validators)
if total_repairs:
output_lines.append(f"Auto-repaired {total_repairs} issue(s)")
success = all(v.validate() for v in validators)
if success:
output_lines.append("All validations PASSED!")
return success, "\n".join(output_lines) if output_lines else None
def _condense_xml(xml_file: Path) -> None:
try:
with open(xml_file, encoding="utf-8") as f:
dom = defusedxml.minidom.parse(f)
for element in dom.getElementsByTagName("*"):
if element.tagName.endswith(":t"):
continue
for child in list(element.childNodes):
if (
child.nodeType == child.TEXT_NODE
and child.nodeValue
and child.nodeValue.strip() == ""
) or child.nodeType == child.COMMENT_NODE:
element.removeChild(child)
xml_file.write_bytes(dom.toxml(encoding="UTF-8"))
except Exception as e:
print(f"ERROR: Failed to parse {xml_file.name}: {e}", file=sys.stderr)
raise
if __name__ == "__main__":
parser = argparse.ArgumentParser(
description="Pack a directory into a DOCX, PPTX, or XLSX file"
)
parser.add_argument("input_directory", help="Unpacked Office document directory")
parser.add_argument("output_file", help="Output Office file (.docx/.pptx/.xlsx)")
parser.add_argument(
"--original",
help="Original file for validation comparison",
)
parser.add_argument(
"--validate",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Run validation with auto-repair (default: true)",
)
args = parser.parse_args()
_, message = pack(
args.input_directory,
args.output_file,
original_file=args.original,
validate=args.validate,
)
print(message)
if "Error" in message:
sys.exit(1)
```
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-chart.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-chartDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-diagram.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-lockedCanvas.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-main.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-picture.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-spreadsheetDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/dml-wordprocessingDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/pml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-additionalCharacteristics.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-bibliography.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-commonSimpleTypes.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlDataProperties.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-customXmlSchemaProperties.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesCustom.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesExtended.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-documentPropertiesVariantTypes.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-math.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/shared-relationshipReference.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/sml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-main.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-officeDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-presentationDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-spreadsheetDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/vml-wordprocessingDrawing.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/wml.xsd)
_Binary resource_
### scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd
[Download scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd](/skills/xlsx/scripts/office/schemas/ISO-IEC29500-4_2016/xml.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd](/skills/xlsx/scripts/office/schemas/ecma/fouth-edition/opc-contentTypes.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd](/skills/xlsx/scripts/office/schemas/ecma/fouth-edition/opc-coreProperties.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd](/skills/xlsx/scripts/office/schemas/ecma/fouth-edition/opc-digSig.xsd)
_Binary resource_
### scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd
[Download scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd](/skills/xlsx/scripts/office/schemas/ecma/fouth-edition/opc-relationships.xsd)
_Binary resource_
### scripts/office/schemas/mce/mc.xsd
[Download scripts/office/schemas/mce/mc.xsd](/skills/xlsx/scripts/office/schemas/mce/mc.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2010.xsd
[Download scripts/office/schemas/microsoft/wml-2010.xsd](/skills/xlsx/scripts/office/schemas/microsoft/wml-2010.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2012.xsd
[Download scripts/office/schemas/microsoft/wml-2012.xsd](/skills/xlsx/scripts/office/schemas/microsoft/wml-2012.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-2018.xsd
[Download scripts/office/schemas/microsoft/wml-2018.xsd](/skills/xlsx/scripts/office/schemas/microsoft/wml-2018.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-cex-2018.xsd
[Download scripts/office/schemas/microsoft/wml-cex-2018.xsd](/skills/xlsx/scripts/office/schemas/microsoft/wml-cex-2018.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-cid-2016.xsd
[Download scripts/office/schemas/microsoft/wml-cid-2016.xsd](/skills/xlsx/scripts/office/schemas/microsoft/wml-cid-2016.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd
[Download scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd](/skills/xlsx/scripts/office/schemas/microsoft/wml-sdtdatahash-2020.xsd)
_Binary resource_
### scripts/office/schemas/microsoft/wml-symex-2015.xsd
[Download scripts/office/schemas/microsoft/wml-symex-2015.xsd](/skills/xlsx/scripts/office/schemas/microsoft/wml-symex-2015.xsd)
_Binary resource_
### scripts/office/soffice.py
[Download scripts/office/soffice.py](/skills/xlsx/scripts/office/soffice.py)
```python
"""
Helper for running LibreOffice (soffice) in environments where AF_UNIX
sockets may be blocked (e.g., sandboxed VMs). Detects the restriction
at runtime and applies an LD_PRELOAD shim if needed.
Usage:
from office.soffice import run_soffice, get_soffice_env
# Option 1 – run soffice directly
result = run_soffice(["--headless", "--convert-to", "pdf", "input.docx"])
# Option 2 – get env dict for your own subprocess calls
env = get_soffice_env()
subprocess.run(["soffice", ...], env=env)
"""
import os
import socket
import subprocess
import tempfile
from pathlib import Path
def get_soffice_env() -> dict:
env = os.environ.copy()
env["SAL_USE_VCLPLUGIN"] = "svp"
if _needs_shim():
shim = _ensure_shim()
env["LD_PRELOAD"] = str(shim)
return env
def run_soffice(args: list[str], **kwargs) -> subprocess.CompletedProcess:
env = get_soffice_env()
return subprocess.run(["soffice"] + args, env=env, **kwargs)
_SHIM_SO = Path(tempfile.gettempdir()) / "lo_socket_shim.so"
def _needs_shim() -> bool:
try:
s = socket.socket(socket.AF_UNIX, socket.SOCK_STREAM)
s.close()
return False
except OSError:
return True
def _ensure_shim() -> Path:
if _SHIM_SO.exists():
return _SHIM_SO
src = Path(tempfile.gettempdir()) / "lo_socket_shim.c"
src.write_text(_SHIM_SOURCE)
subprocess.run(
["gcc", "-shared", "-fPIC", "-o", str(_SHIM_SO), str(src), "-ldl"],
check=True,
capture_output=True,
)
src.unlink()
return _SHIM_SO
_SHIM_SOURCE = r"""
#define _GNU_SOURCE
#include
#include
#include
#include
#include
#include
#include
static int (*real_socket)(int, int, int);
static int (*real_socketpair)(int, int, int, int[2]);
static int (*real_listen)(int, int);
static int (*real_accept)(int, struct sockaddr *, socklen_t *);
static int (*real_close)(int);
static int (*real_read)(int, void *, size_t);
/* Per-FD bookkeeping (FDs >= 1024 are passed through unshimmed). */
static int is_shimmed[1024];
static int peer_of[1024];
static int wake_r[1024]; /* accept() blocks reading this */
static int wake_w[1024]; /* close() writes to this */
static int listener_fd = -1; /* FD that received listen() */
__attribute__((constructor))
static void init(void) {
real_socket = dlsym(RTLD_NEXT, "socket");
real_socketpair = dlsym(RTLD_NEXT, "socketpair");
real_listen = dlsym(RTLD_NEXT, "listen");
real_accept = dlsym(RTLD_NEXT, "accept");
real_close = dlsym(RTLD_NEXT, "close");
real_read = dlsym(RTLD_NEXT, "read");
for (int i = 0; i < 1024; i++) {
peer_of[i] = -1;
wake_r[i] = -1;
wake_w[i] = -1;
}
}
/* ---- socket ---------------------------------------------------------- */
int socket(int domain, int type, int protocol) {
if (domain == AF_UNIX) {
int fd = real_socket(domain, type, protocol);
if (fd >= 0) return fd;
/* socket(AF_UNIX) blocked – fall back to socketpair(). */
int sv[2];
if (real_socketpair(domain, type, protocol, sv) == 0) {
if (sv[0] >= 0 && sv[0] < 1024) {
is_shimmed[sv[0]] = 1;
peer_of[sv[0]] = sv[1];
int wp[2];
if (pipe(wp) == 0) {
wake_r[sv[0]] = wp[0];
wake_w[sv[0]] = wp[1];
}
}
return sv[0];
}
errno = EPERM;
return -1;
}
return real_socket(domain, type, protocol);
}
/* ---- listen ---------------------------------------------------------- */
int listen(int sockfd, int backlog) {
if (sockfd >= 0 && sockfd < 1024 && is_shimmed[sockfd]) {
listener_fd = sockfd;
return 0;
}
return real_listen(sockfd, backlog);
}
/* ---- accept ---------------------------------------------------------- */
int accept(int sockfd, struct sockaddr *addr, socklen_t *addrlen) {
if (sockfd >= 0 && sockfd < 1024 && is_shimmed[sockfd]) {
/* Block until close() writes to the wake pipe. */
if (wake_r[sockfd] >= 0) {
char buf;
real_read(wake_r[sockfd], &buf, 1);
}
errno = ECONNABORTED;
return -1;
}
return real_accept(sockfd, addr, addrlen);
}
/* ---- close ----------------------------------------------------------- */
int close(int fd) {
if (fd >= 0 && fd < 1024 && is_shimmed[fd]) {
int was_listener = (fd == listener_fd);
is_shimmed[fd] = 0;
if (wake_w[fd] >= 0) { /* unblock accept() */
char c = 0;
write(wake_w[fd], &c, 1);
real_close(wake_w[fd]);
wake_w[fd] = -1;
}
if (wake_r[fd] >= 0) { real_close(wake_r[fd]); wake_r[fd] = -1; }
if (peer_of[fd] >= 0) { real_close(peer_of[fd]); peer_of[fd] = -1; }
if (was_listener)
_exit(0); /* conversion done – exit */
}
return real_close(fd);
}
"""
if __name__ == "__main__":
import sys
result = run_soffice(sys.argv[1:])
sys.exit(result.returncode)
```
### scripts/office/unpack.py
[Download scripts/office/unpack.py](/skills/xlsx/scripts/office/unpack.py)
```python
"""Unpack Office files (DOCX, PPTX, XLSX) for editing.
Extracts the ZIP archive, pretty-prints XML files, and optionally:
- Merges adjacent runs with identical formatting (DOCX only)
- Simplifies adjacent tracked changes from same author (DOCX only)
Usage:
python unpack.py [options]
Examples:
python unpack.py document.docx unpacked/
python unpack.py presentation.pptx unpacked/
python unpack.py document.docx unpacked/ --merge-runs false
"""
import argparse
import sys
import zipfile
from pathlib import Path
import defusedxml.minidom
from helpers.merge_runs import merge_runs as do_merge_runs
from helpers.simplify_redlines import simplify_redlines as do_simplify_redlines
SMART_QUOTE_REPLACEMENTS = {
"\u201c": "“",
"\u201d": "”",
"\u2018": "‘",
"\u2019": "’",
}
def unpack(
input_file: str,
output_directory: str,
merge_runs: bool = True,
simplify_redlines: bool = True,
) -> tuple[None, str]:
input_path = Path(input_file)
output_path = Path(output_directory)
suffix = input_path.suffix.lower()
if not input_path.exists():
return None, f"Error: {input_file} does not exist"
if suffix not in {".docx", ".pptx", ".xlsx"}:
return None, f"Error: {input_file} must be a .docx, .pptx, or .xlsx file"
try:
output_path.mkdir(parents=True, exist_ok=True)
with zipfile.ZipFile(input_path, "r") as zf:
zf.extractall(output_path)
xml_files = list(output_path.rglob("*.xml")) + list(output_path.rglob("*.rels"))
for xml_file in xml_files:
_pretty_print_xml(xml_file)
message = f"Unpacked {input_file} ({len(xml_files)} XML files)"
if suffix == ".docx":
if simplify_redlines:
simplify_count, _ = do_simplify_redlines(str(output_path))
message += f", simplified {simplify_count} tracked changes"
if merge_runs:
merge_count, _ = do_merge_runs(str(output_path))
message += f", merged {merge_count} runs"
for xml_file in xml_files:
_escape_smart_quotes(xml_file)
return None, message
except zipfile.BadZipFile:
return None, f"Error: {input_file} is not a valid Office file"
except Exception as e:
return None, f"Error unpacking: {e}"
def _pretty_print_xml(xml_file: Path) -> None:
try:
content = xml_file.read_text(encoding="utf-8")
dom = defusedxml.minidom.parseString(content)
xml_file.write_bytes(dom.toprettyxml(indent=" ", encoding="utf-8"))
except Exception:
pass
def _escape_smart_quotes(xml_file: Path) -> None:
try:
content = xml_file.read_text(encoding="utf-8")
for char, entity in SMART_QUOTE_REPLACEMENTS.items():
content = content.replace(char, entity)
xml_file.write_text(content, encoding="utf-8")
except Exception:
pass
if __name__ == "__main__":
parser = argparse.ArgumentParser(
description="Unpack an Office file (DOCX, PPTX, XLSX) for editing"
)
parser.add_argument("input_file", help="Office file to unpack")
parser.add_argument("output_directory", help="Output directory")
parser.add_argument(
"--merge-runs",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Merge adjacent runs with identical formatting (DOCX only, default: true)",
)
parser.add_argument(
"--simplify-redlines",
type=lambda x: x.lower() == "true",
default=True,
metavar="true|false",
help="Merge adjacent tracked changes from same author (DOCX only, default: true)",
)
args = parser.parse_args()
_, message = unpack(
args.input_file,
args.output_directory,
merge_runs=args.merge_runs,
simplify_redlines=args.simplify_redlines,
)
print(message)
if "Error" in message:
sys.exit(1)
```
### scripts/office/validate.py
[Download scripts/office/validate.py](/skills/xlsx/scripts/office/validate.py)
```python
"""
Command line tool to validate Office document XML files against XSD schemas and tracked changes.
Usage:
python validate.py [--original ] [--auto-repair] [--author NAME]
The first argument can be either:
- An unpacked directory containing the Office document XML files
- A packed Office file (.docx/.pptx/.xlsx) which will be unpacked to a temp directory
Auto-repair fixes:
- paraId/durableId values that exceed OOXML limits
- Missing xml:space="preserve" on w:t elements with whitespace
"""
import argparse
import sys
import tempfile
import zipfile
from pathlib import Path
from validators import DOCXSchemaValidator, PPTXSchemaValidator, RedliningValidator
def main():
parser = argparse.ArgumentParser(description="Validate Office document XML files")
parser.add_argument(
"path",
help="Path to unpacked directory or packed Office file (.docx/.pptx/.xlsx)",
)
parser.add_argument(
"--original",
required=False,
default=None,
help="Path to original file (.docx/.pptx/.xlsx). If omitted, all XSD errors are reported and redlining validation is skipped.",
)
parser.add_argument(
"-v",
"--verbose",
action="store_true",
help="Enable verbose output",
)
parser.add_argument(
"--auto-repair",
action="store_true",
help="Automatically repair common issues (hex IDs, whitespace preservation)",
)
parser.add_argument(
"--author",
default="Claude",
help="Author name for redlining validation (default: Claude)",
)
args = parser.parse_args()
path = Path(args.path)
assert path.exists(), f"Error: {path} does not exist"
original_file = None
if args.original:
original_file = Path(args.original)
assert original_file.is_file(), f"Error: {original_file} is not a file"
assert original_file.suffix.lower() in [".docx", ".pptx", ".xlsx"], (
f"Error: {original_file} must be a .docx, .pptx, or .xlsx file"
)
file_extension = (original_file or path).suffix.lower()
assert file_extension in [".docx", ".pptx", ".xlsx"], (
f"Error: Cannot determine file type from {path}. Use --original or provide a .docx/.pptx/.xlsx file."
)
if path.is_file() and path.suffix.lower() in [".docx", ".pptx", ".xlsx"]:
temp_dir = tempfile.mkdtemp()
with zipfile.ZipFile(path, "r") as zf:
zf.extractall(temp_dir)
unpacked_dir = Path(temp_dir)
else:
assert path.is_dir(), f"Error: {path} is not a directory or Office file"
unpacked_dir = path
match file_extension:
case ".docx":
validators = [
DOCXSchemaValidator(unpacked_dir, original_file, verbose=args.verbose),
]
if original_file:
validators.append(
RedliningValidator(unpacked_dir, original_file, verbose=args.verbose, author=args.author)
)
case ".pptx":
validators = [
PPTXSchemaValidator(unpacked_dir, original_file, verbose=args.verbose),
]
case _:
print(f"Error: Validation not supported for file type {file_extension}")
sys.exit(1)
if args.auto_repair:
total_repairs = sum(v.repair() for v in validators)
if total_repairs:
print(f"Auto-repaired {total_repairs} issue(s)")
success = all(v.validate() for v in validators)
if success:
print("All validations PASSED!")
sys.exit(0 if success else 1)
if __name__ == "__main__":
main()
```
### scripts/office/validators/__init__.py
[Download scripts/office/validators/__init__.py](/skills/xlsx/scripts/office/validators/__init__.py)
```python
"""
Validation modules for Word document processing.
"""
from .base import BaseSchemaValidator
from .docx import DOCXSchemaValidator
from .pptx import PPTXSchemaValidator
from .redlining import RedliningValidator
__all__ = [
"BaseSchemaValidator",
"DOCXSchemaValidator",
"PPTXSchemaValidator",
"RedliningValidator",
]
```
### scripts/office/validators/base.py
[Download scripts/office/validators/base.py](/skills/xlsx/scripts/office/validators/base.py)
_Binary resource_
### scripts/office/validators/docx.py
[Download scripts/office/validators/docx.py](/skills/xlsx/scripts/office/validators/docx.py)
_Binary resource_
### scripts/office/validators/pptx.py
[Download scripts/office/validators/pptx.py](/skills/xlsx/scripts/office/validators/pptx.py)
_Binary resource_
### scripts/office/validators/redlining.py
[Download scripts/office/validators/redlining.py](/skills/xlsx/scripts/office/validators/redlining.py)
_Binary resource_
### scripts/recalc.py
[Download scripts/recalc.py](/skills/xlsx/scripts/recalc.py)
```python
"""
Excel Formula Recalculation Script
Recalculates all formulas in an Excel file using LibreOffice
"""
import json
import os
import platform
import subprocess
import sys
from pathlib import Path
from office.soffice import get_soffice_env
from openpyxl import load_workbook
MACRO_DIR_MACOS = "~/Library/Application Support/LibreOffice/4/user/basic/Standard"
MACRO_DIR_LINUX = "~/.config/libreoffice/4/user/basic/Standard"
MACRO_FILENAME = "Module1.xba"
RECALCULATE_MACRO = """
Sub RecalculateAndSave()
ThisComponent.calculateAll()
ThisComponent.store()
ThisComponent.close(True)
End Sub
"""
def has_gtimeout():
try:
subprocess.run(
["gtimeout", "--version"], capture_output=True, timeout=1, check=False
)
return True
except (FileNotFoundError, subprocess.TimeoutExpired):
return False
def setup_libreoffice_macro():
macro_dir = os.path.expanduser(
MACRO_DIR_MACOS if platform.system() == "Darwin" else MACRO_DIR_LINUX
)
macro_file = os.path.join(macro_dir, MACRO_FILENAME)
if (
os.path.exists(macro_file)
and "RecalculateAndSave" in Path(macro_file).read_text()
):
return True
if not os.path.exists(macro_dir):
subprocess.run(
["soffice", "--headless", "--terminate_after_init"],
capture_output=True,
timeout=10,
env=get_soffice_env(),
)
os.makedirs(macro_dir, exist_ok=True)
try:
Path(macro_file).write_text(RECALCULATE_MACRO)
return True
except Exception:
return False
def recalc(filename, timeout=30):
if not Path(filename).exists():
return {"error": f"File {filename} does not exist"}
abs_path = str(Path(filename).absolute())
if not setup_libreoffice_macro():
return {"error": "Failed to setup LibreOffice macro"}
cmd = [
"soffice",
"--headless",
"--norestore",
"vnd.sun.star.script:Standard.Module1.RecalculateAndSave?language=Basic&location=application",
abs_path,
]
if platform.system() == "Linux":
cmd = ["timeout", str(timeout)] + cmd
elif platform.system() == "Darwin" and has_gtimeout():
cmd = ["gtimeout", str(timeout)] + cmd
result = subprocess.run(cmd, capture_output=True, text=True, env=get_soffice_env())
if result.returncode != 0 and result.returncode != 124:
error_msg = result.stderr or "Unknown error during recalculation"
if "Module1" in error_msg or "RecalculateAndSave" not in error_msg:
return {"error": "LibreOffice macro not configured properly"}
return {"error": error_msg}
try:
wb = load_workbook(filename, data_only=True)
excel_errors = [
"#VALUE!",
"#DIV/0!",
"#REF!",
"#NAME?",
"#NULL!",
"#NUM!",
"#N/A",
]
error_details = {err: [] for err in excel_errors}
total_errors = 0
for sheet_name in wb.sheetnames:
ws = wb[sheet_name]
for row in ws.iter_rows():
for cell in row:
if cell.value is not None and isinstance(cell.value, str):
for err in excel_errors:
if err in cell.value:
location = f"{sheet_name}!{cell.coordinate}"
error_details[err].append(location)
total_errors += 1
break
wb.close()
result = {
"status": "success" if total_errors == 0 else "errors_found",
"total_errors": total_errors,
"error_summary": {},
}
for err_type, locations in error_details.items():
if locations:
result["error_summary"][err_type] = {
"count": len(locations),
"locations": locations[:20],
}
wb_formulas = load_workbook(filename, data_only=False)
formula_count = 0
for sheet_name in wb_formulas.sheetnames:
ws = wb_formulas[sheet_name]
for row in ws.iter_rows():
for cell in row:
if (
cell.value
and isinstance(cell.value, str)
and cell.value.startswith("=")
):
formula_count += 1
wb_formulas.close()
result["total_formulas"] = formula_count
return result
except Exception as e:
return {"error": str(e)}
def main():
if len(sys.argv) < 2:
print("Usage: python recalc.py [timeout_seconds]")
print("\nRecalculates all formulas in an Excel file using LibreOffice")
print("\nReturns JSON with error details:")
print(" - status: 'success' or 'errors_found'")
print(" - total_errors: Total number of Excel errors found")
print(" - total_formulas: Number of formulas in the file")
print(" - error_summary: Breakdown by error type with locations")
print(" - #VALUE!, #DIV/0!, #REF!, #NAME?, #NULL!, #NUM!, #N/A")
sys.exit(1)
filename = sys.argv[1]
timeout = int(sys.argv[2]) if len(sys.argv) > 2 else 30
result = recalc(filename, timeout)
print(json.dumps(result, indent=2))
if __name__ == "__main__":
main()
```
## See in GitHub
[See in GitHub](https://github.com/anthropics/skills/tree/main/xlsx)
---
# Static Export
URL: http://www.claudeskills.org/docs/static-export
Description: Enable static export with Fumadocs
## Overview
Fumadocs is fully compatible with Next.js static export, allowing you to export the app as a static HTML site without a Node.js server.
```js title="next.config.mjs"
/**
* @type {import('next').NextConfig}
*/
const nextConfig = {
output: 'export',
};
```
## Search
### Cloud Solutions
Since the search functionality is powered by remote servers, static export works without configuration.
### Built-in Search
The default search config of Orama Search uses route handlers, which is not supported by static export.
Instead, you can build the search indexes statically following the [Orama Search](/docs/headless/search/orama#static-export) guide.
And enable static mode on search client from Root Provider:
```tsx title="app/layout.tsx"
import { RootProvider } from 'fumadocs-ui/provider';
import type { ReactNode } from 'react';
export default function RootLayout({ children }: { children: ReactNode }) {
return (
{children}
);
}
```
This allows the route handler to be statically cached into a single file, and search will be computed on browser instead.
---
# Themes
URL: http://www.claudeskills.org/docs/theme
Description: Add Theme to Fumadocs UI
## Usage
Note only Tailwind CSS v4 is supported:
```css title="Tailwind CSS"
@import 'tailwindcss';
@import 'fumadocs-ui/css/neutral.css';
@import 'fumadocs-ui/css/preset.css';
/* path of `fumadocs-ui` relative to the CSS file */
@source '../node_modules/fumadocs-ui/dist/**/*.js';
```
### Preflight Changes
By using the Tailwind CSS plugin, or the pre-built stylesheet, your default border, text and background
colors will be changed.
### Light/Dark Modes
Fumadocs supports light/dark modes with [`next-themes`](https://github.com/pacocoursey/next-themes), it is included in Root Provider.
See [Root Provider](/docs/layouts/root-provider#theme-provider) to learn more.
### RTL Layout
RTL (Right-to-left) layout is supported.
To enable RTL, set the `dir` prop to `rtl` in body and root provider (required for Radix UI).
```tsx
import { RootProvider } from 'fumadocs-ui/provider';
import type { ReactNode } from 'react';
export default function RootLayout({ children }: { children: ReactNode }) {
return (
{children}
);
}
```
### Prefix
Fumadocs UI has its own colors, animations, and utilities.
By default, it adds a `fd-` prefix to avoid conflicts with Shadcn UI or your own CSS variables.
You can use them without the prefix by adding some aliases:
```css title="Tailwind CSS"
@theme {
--color-primary: var(--color-fd-primary);
}
```
> You can use it with CSS media queries for responsive design.
### Layout Width
Customise the max width of docs layout with CSS Variables.
```css
:root {
--fd-layout-width: 1400px;
}
```
{/* */}
## Tailwind CSS Preset
The Tailwind CSS preset introduces new colors and extra utilities including `fd-steps`.
### Themes
It comes with many themes out-of-the-box, you can pick one you prefer.
```css
@import 'fumadocs-ui/css/.css';
/* Example */
@import 'fumadocs-ui/css/black.css';
```
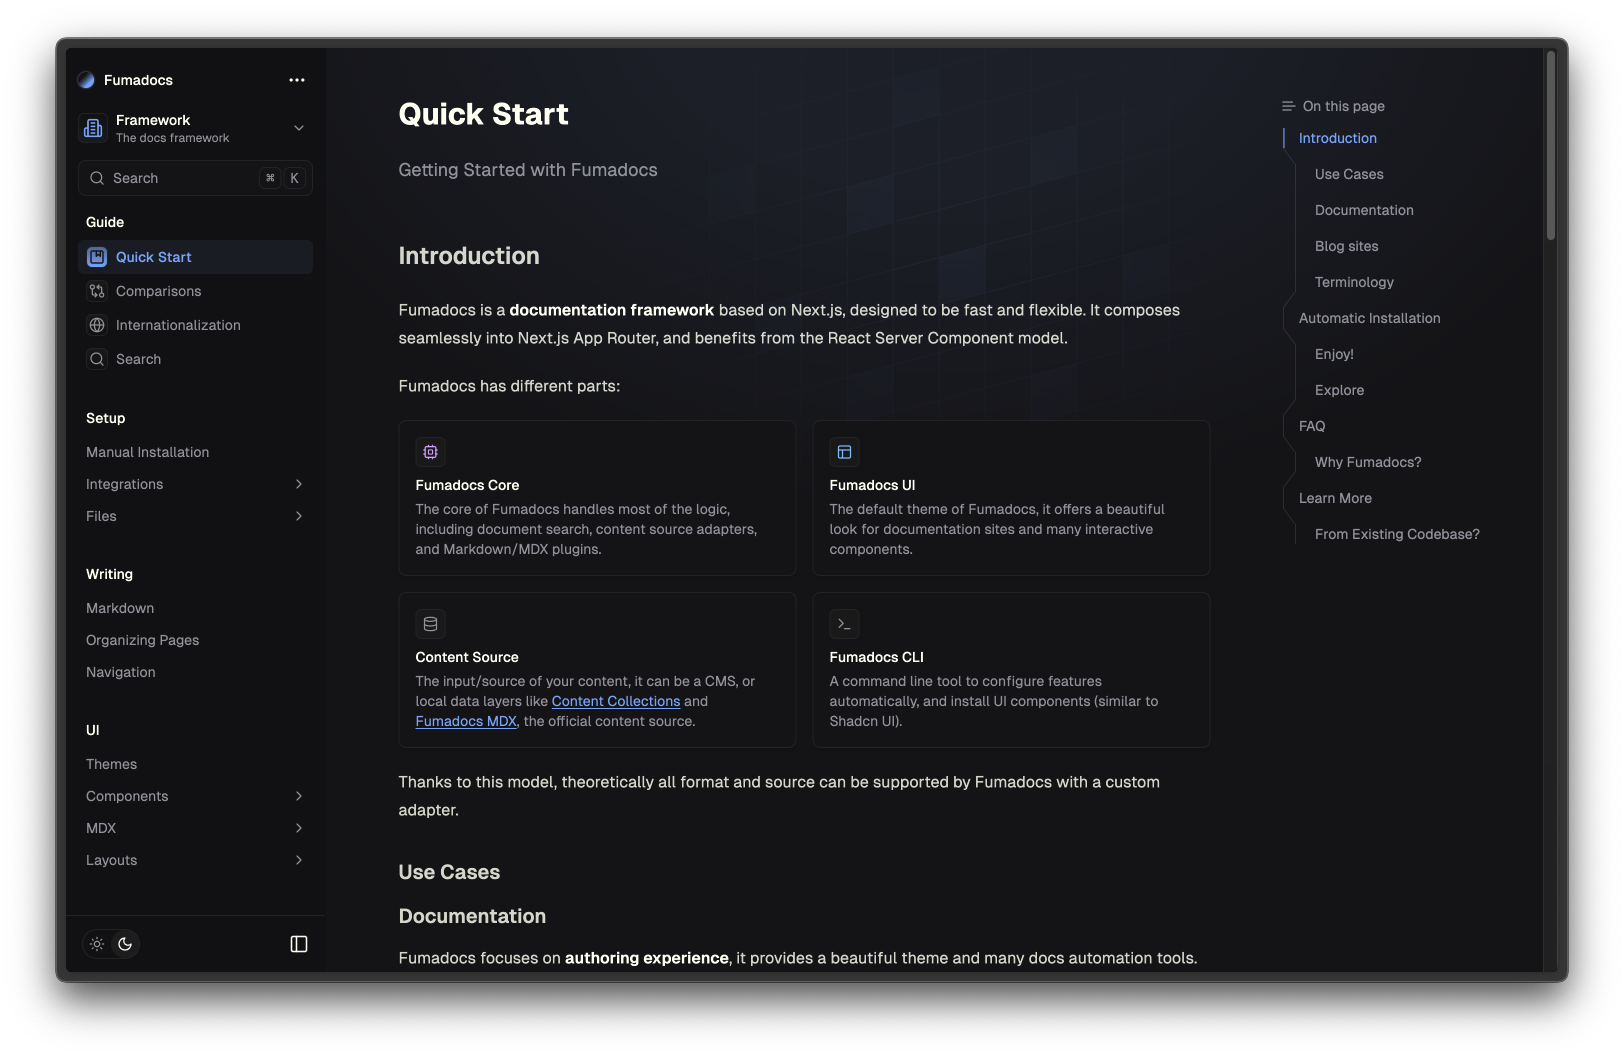
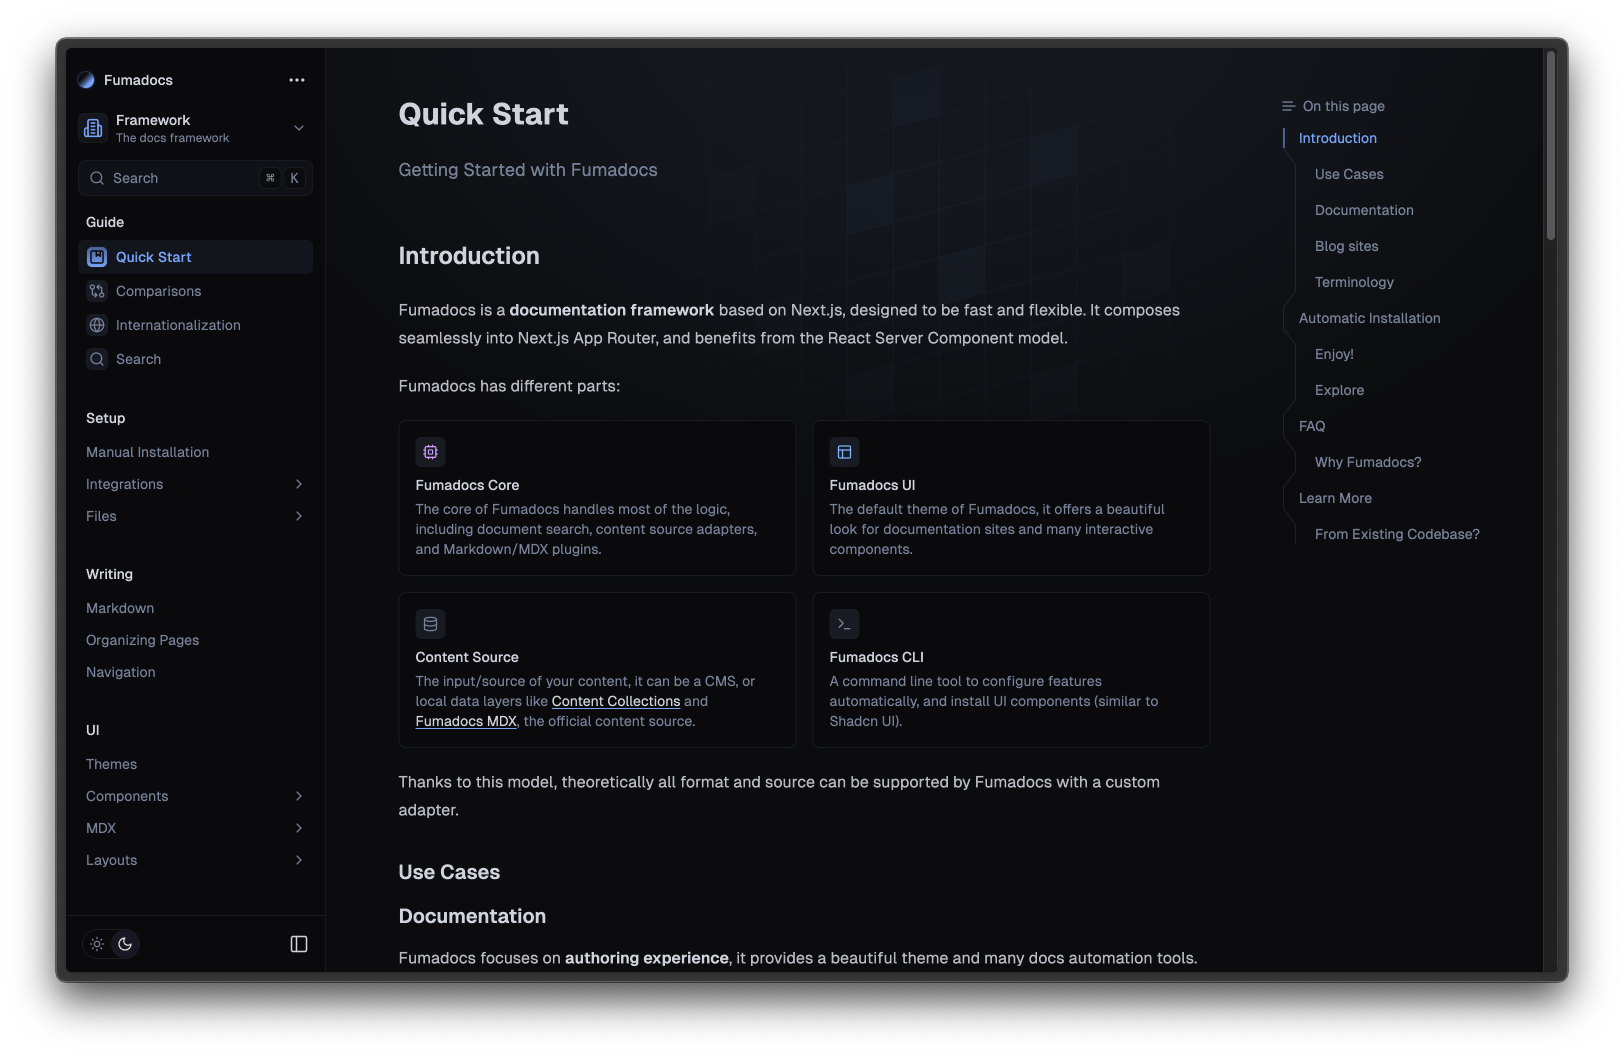
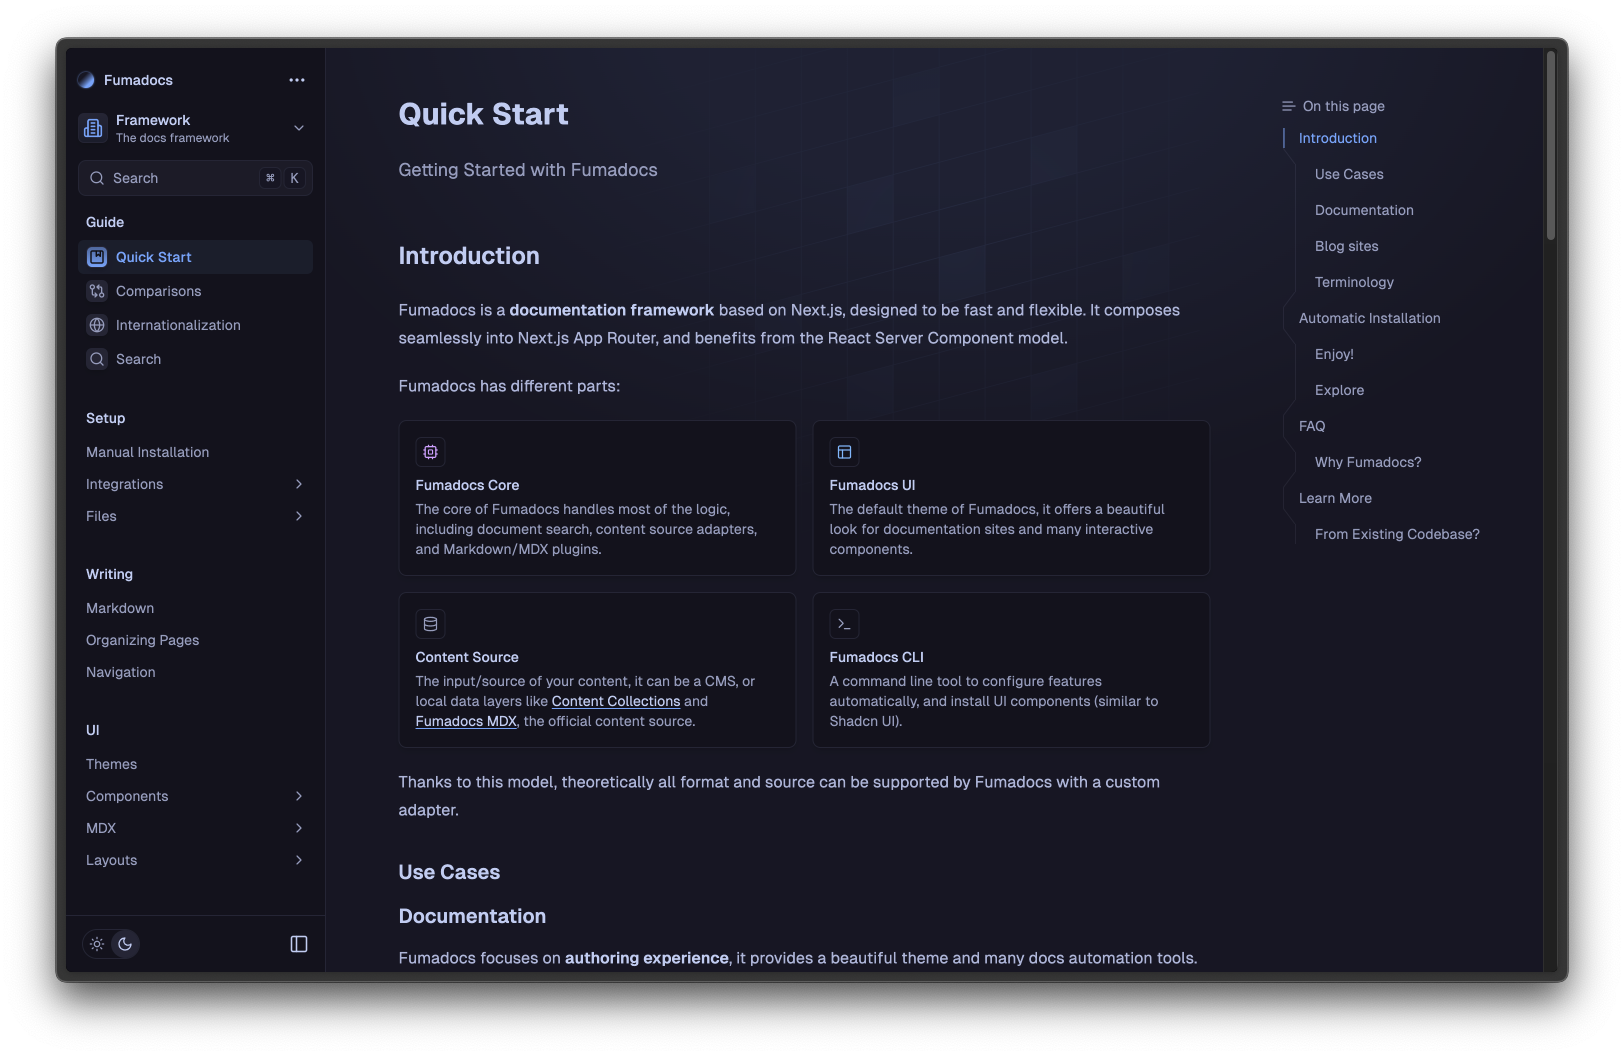
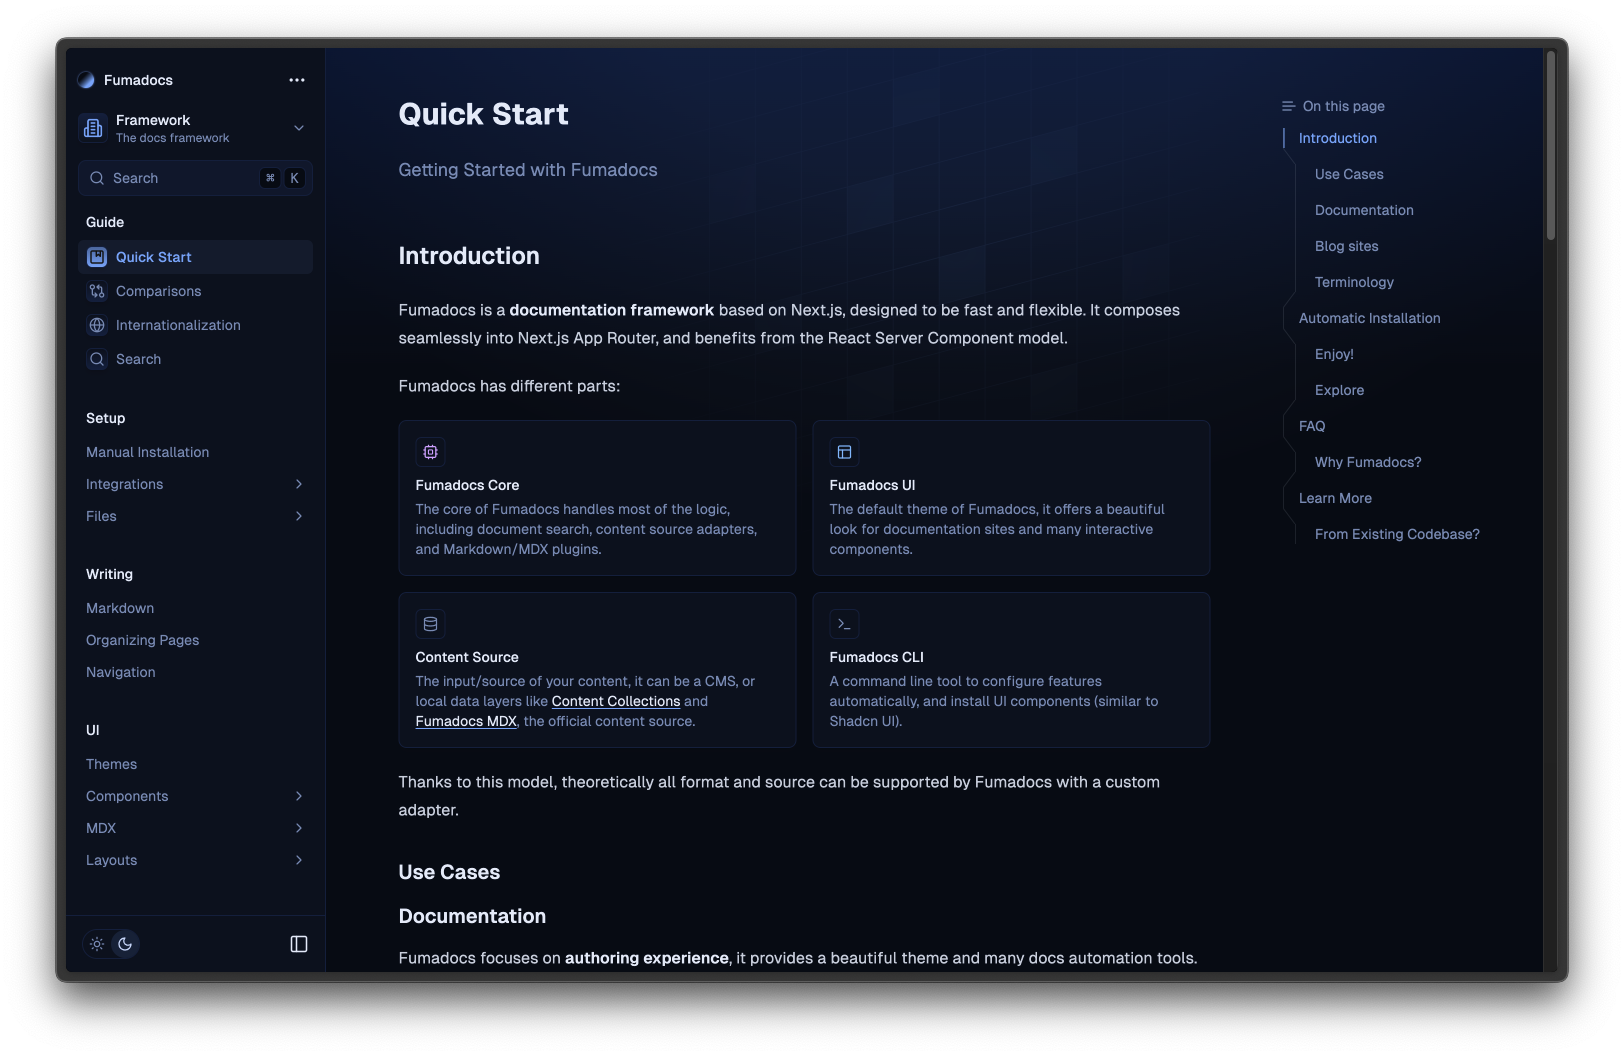
### Colors
The design system was inspired by [Shadcn UI](https://ui.shadcn.com), you can easily customize the colors using CSS variables.
```css title="global.css"
:root {
--color-fd-background: hsl(0, 0%, 100%);
}
.dark {
--color-fd-background: hsl(0, 0%, 0%);
}
```
### Typography
We have a built-in plugin forked from [Tailwind CSS Typography](https://tailwindcss.com/docs/typography-plugin).
The plugin adds a `prose` class and variants to customise it.
```tsx
Good Heading
```
> The plugin works with and only with Fumadocs UI's MDX components, it may conflict with `@tailwindcss/typography`.
> If you need to use `@tailwindcss/typography` over the default plugin, [set a class name option](https://github.com/tailwindlabs/tailwindcss-typography/blob/main/README.md#changing-the-default-class-name) to avoid conflicts.
---
# What is Fumadocs
URL: http://www.claudeskills.org/docs/what-is-fumadocs
Description: Introducing Fumadocs, a docs framework that you can break.
Fumadocs was created because I wanted a more customisable experience for building docs, to be a docs framework that is not opinionated, **a "framework" that you can break**.
## Philosophy
**Less Abstraction:** Fumadocs expects you to write code and cooperate with the rest of your software.
While most frameworks are configured with a configuration file, they usually lack flexibility when you hope to tune its details.
You can’t control how they render the page nor the internal logic. Fumadocs shows you how the app works, instead of a single configuration file.
**Next.js Fundamentals:** It gives you the utilities and a good-looking UI.
You are still using features of Next.js App Router, like **Static Site Generation**. There is nothing new for Next.js developers, so you can use it with confidence.
**Opinionated on UI:** The only thing Fumadocs UI (the default theme) offers is **User Interface**. The UI is opinionated for bringing better mobile responsiveness and user experience.
Instead, we use a much more flexible approach inspired by Shadcn UI — [Fumadocs CLI](/docs/cli), so we can iterate our design quick, and welcome for more feedback about the UI.
## Why Fumadocs
Fumadocs is designed with flexibility in mind.
You can use `fumadocs-core` as a headless UI library and bring your own styles.
Fumadocs MDX is also a useful library to handle MDX content in Next.js. It also includes:
- Many built-in components.
- Typescript Twoslash, OpenAPI, and Math (KaTeX) integrations.
- Fast and optimized by default, natively built on App Router.
- Tight integration with Next.js, you can add it to an existing Next.js project easily.
You can read [Comparisons](/docs/comparisons) if you're interested.
### Documentation
Fumadocs focuses on **authoring experience**, it provides a beautiful theme and many docs automation tools.
It helps you to iterate your codebase faster while never leaving your docs behind.
You can take this site as an example of docs site built with Fumadocs.
### Blog sites
Since Next.js is already a powerful framework, most features can be implemented with **just Next.js**.
Fumadocs provides additional tooling for Next.js, including syntax highlighting, document search, and a default theme (Fumadocs UI).
It helps you to avoid reinventing the wheels.
## When to use Fumadocs
For most of the web applications, vanilla React.js is no longer enough.
Nowadays, we also wish to have a blog, a showcase page, a FAQ page, etc. With a
fancy UI that's breathtaking, in these cases, Fumadocs can help you build the
docs easier, with less boilerplate.
Fumadocs is maintained by Fuma and many contributors, with care on the maintainability of codebase.
While we don't aim to offer every functionality people wanted, we're more focused on making basic features perfect and well-maintained.
You can also help Fumadocs to be more useful by contributing!
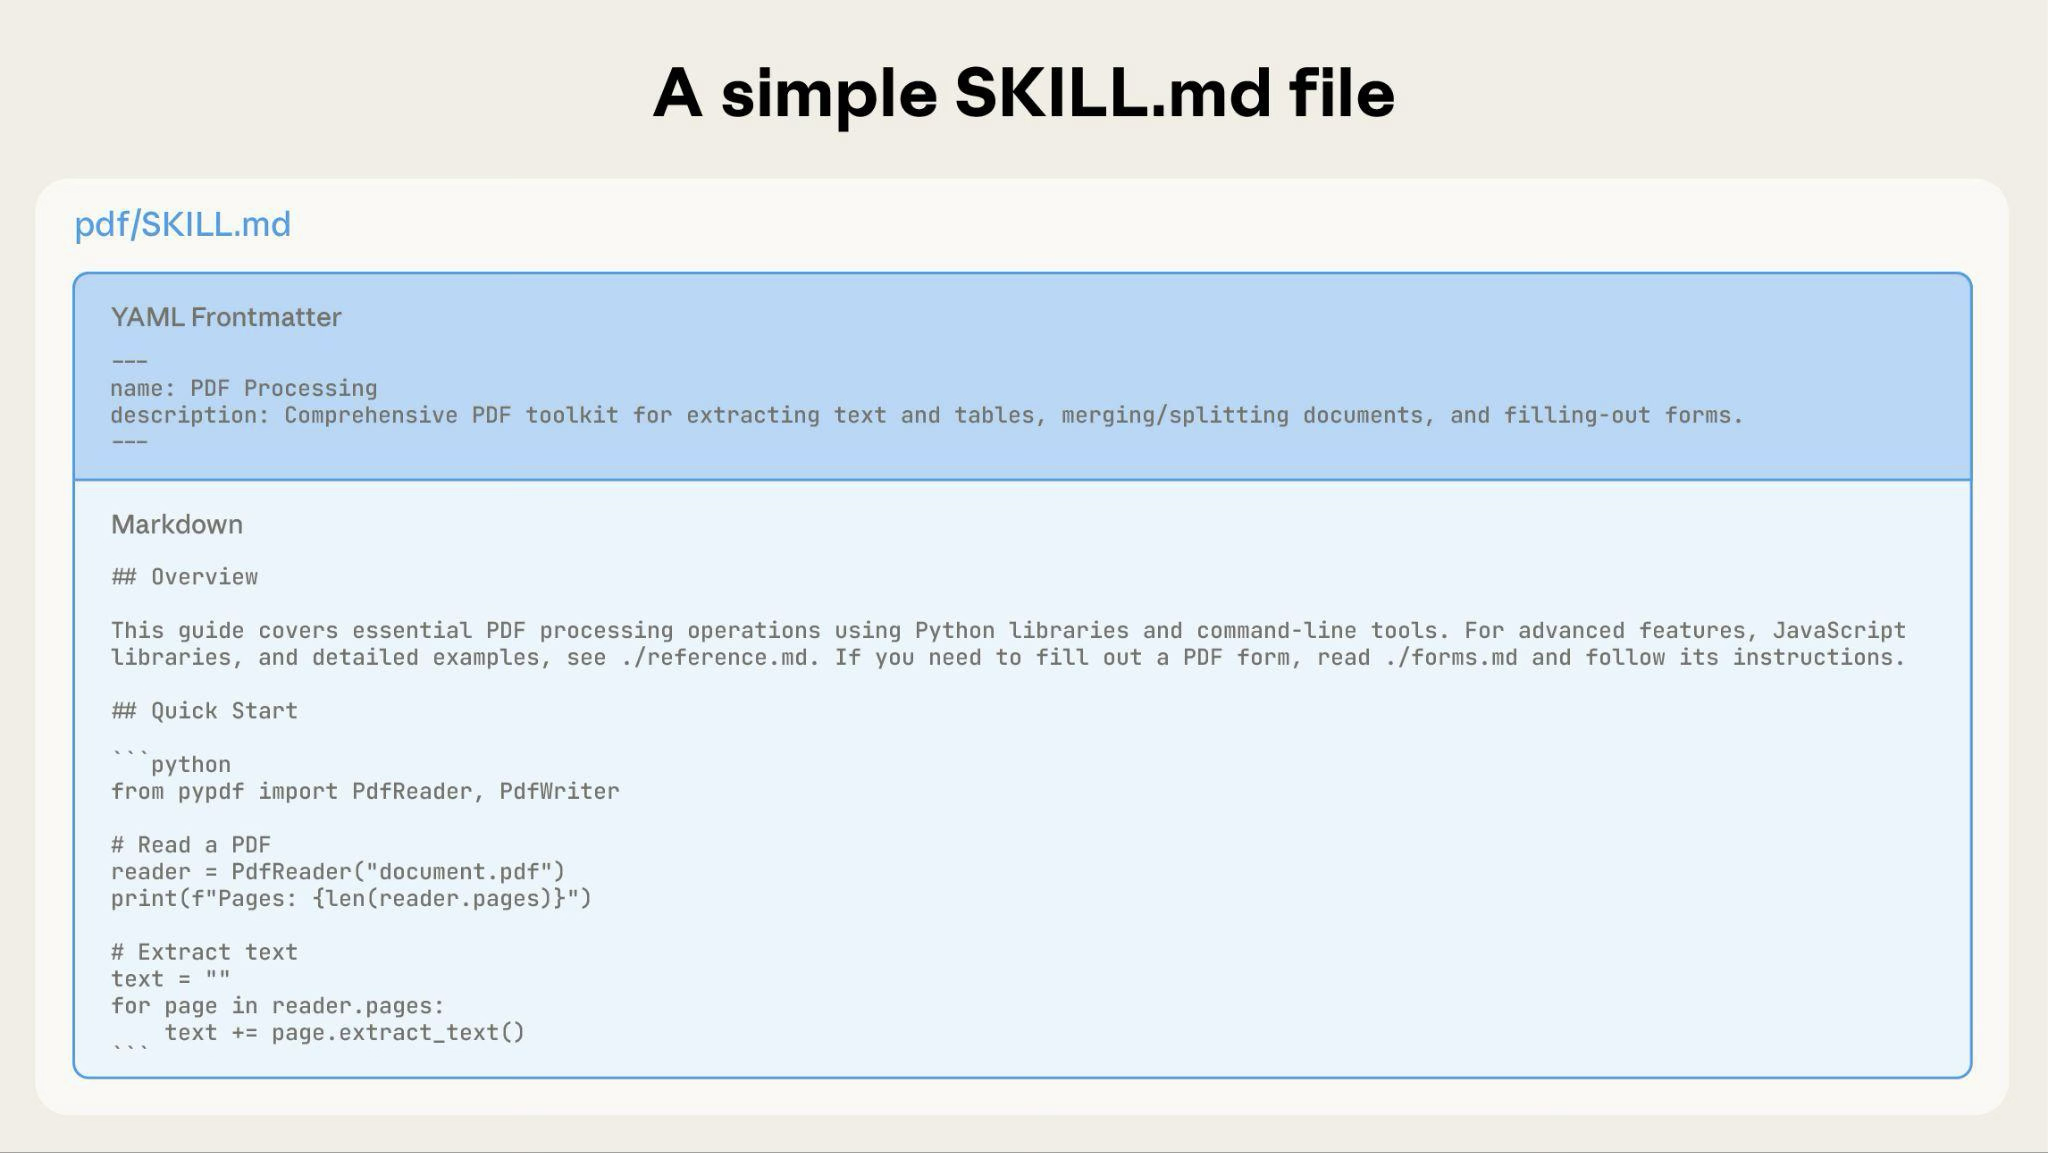 As your Skill grows, you can bundle additional content that Claude loads only when needed:
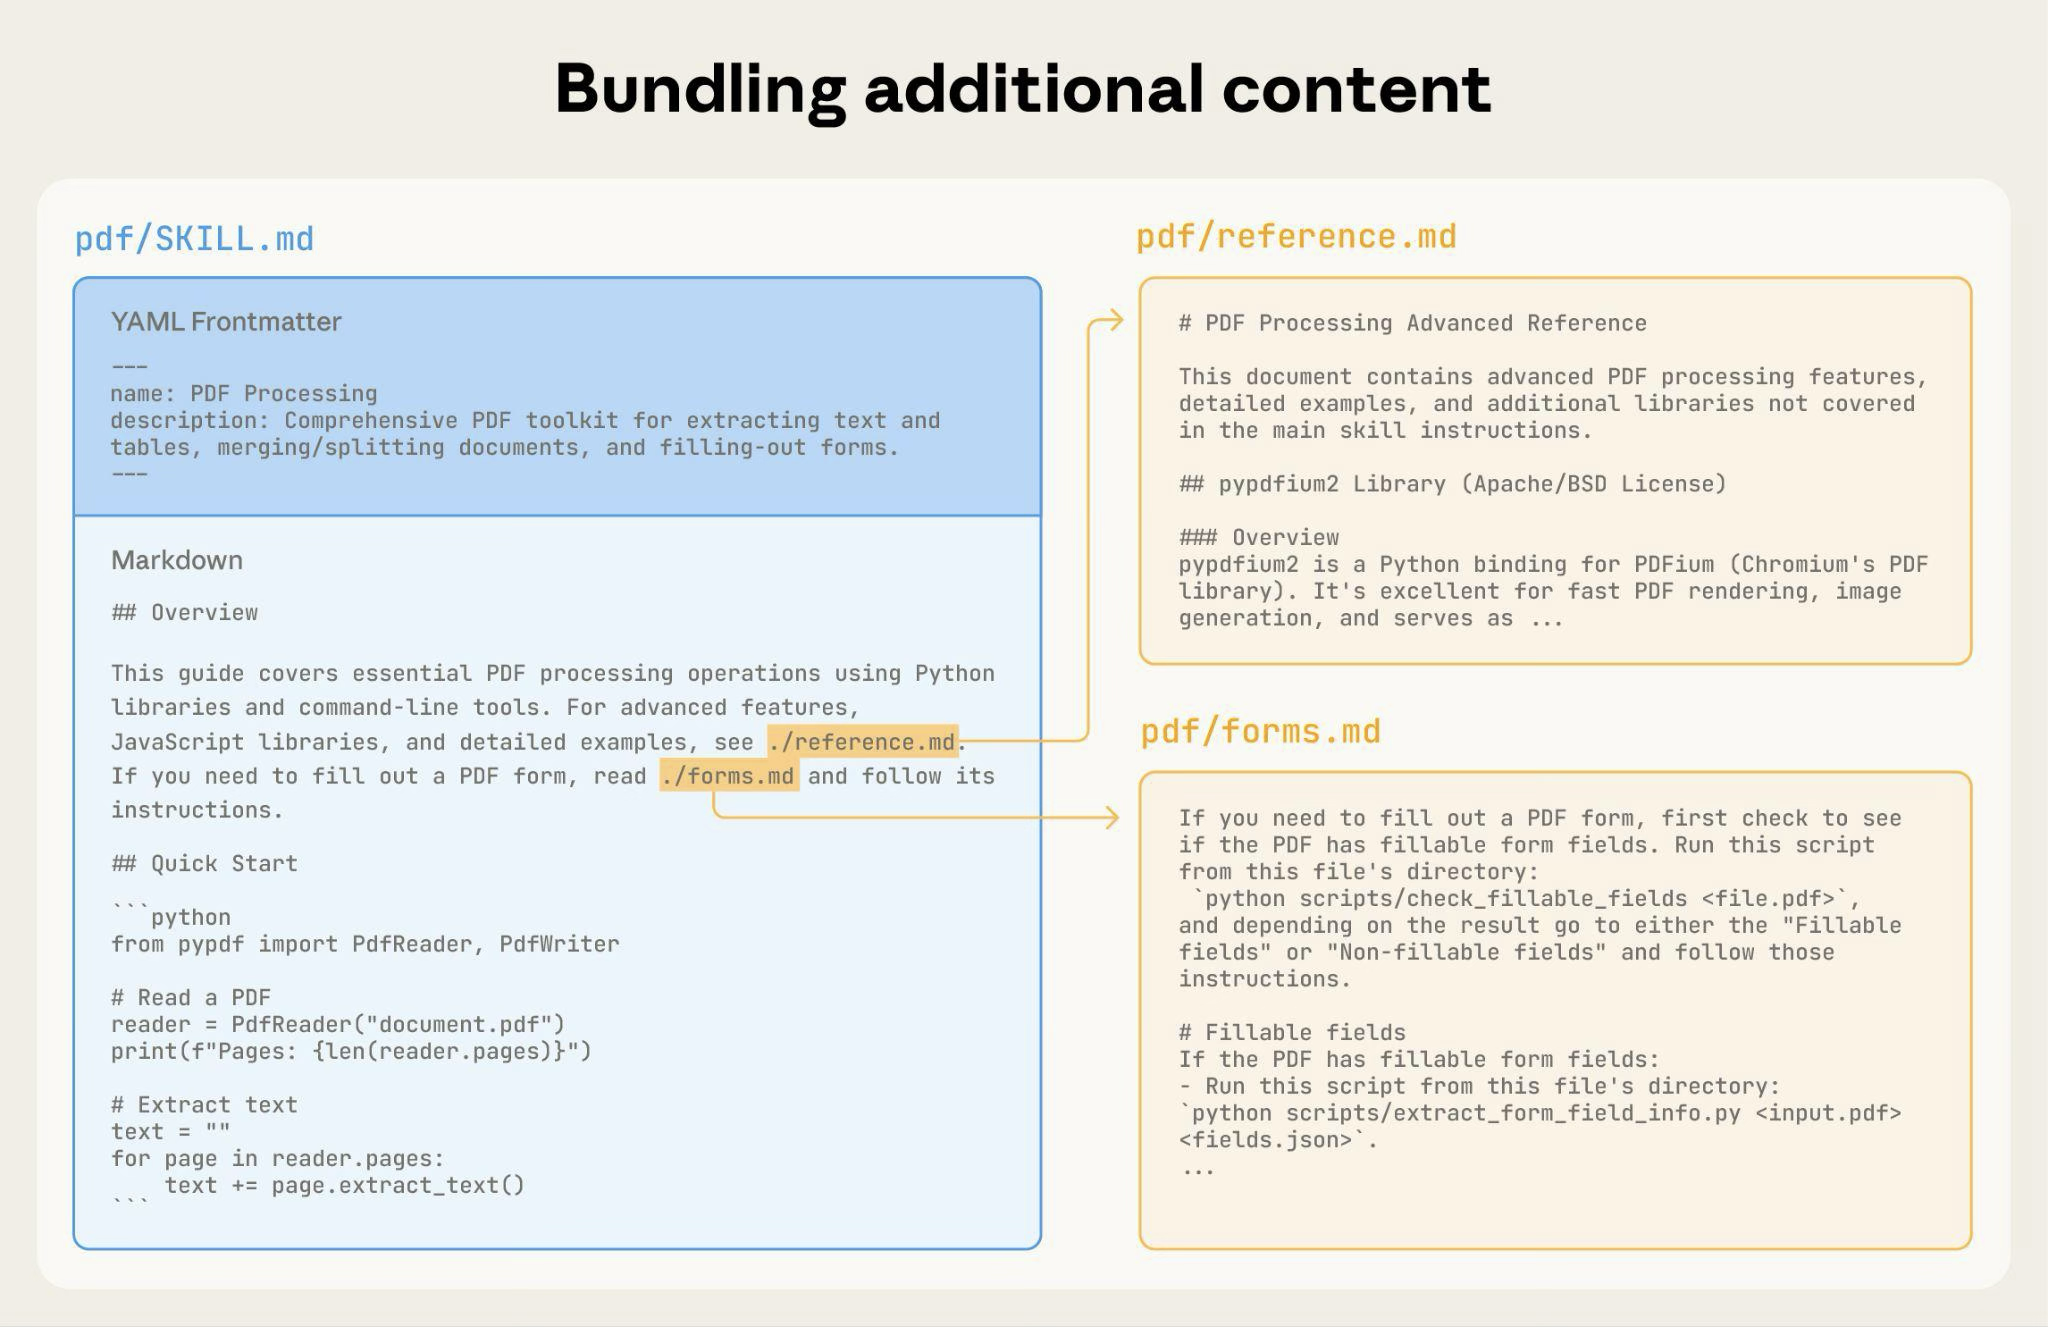 The complete Skill directory structure might look like this:
```
pdf/
|-- SKILL.md # Main instructions (loaded when triggered)
|-- FORMS.md # Form-filling guide (loaded as needed)
|-- reference.md # API reference (loaded as needed)
|-- examples.md # Usage examples (loaded as needed)
`-- scripts/
|-- analyze_form.py # Utility script (executed, not loaded)
|-- fill_form.py # Form filling script
`-- validate.py # Validation script
```
#### Pattern 1: High-level guide with references
````markdown
---
name: PDF Processing
description: Extracts text and tables from PDF files, fills forms, and merges documents. Use when working with PDF files or when the user mentions PDFs, forms, or document extraction.
---
# PDF Processing
## Quick start
Extract text with pdfplumber:
```python
import pdfplumber
with pdfplumber.open("file.pdf") as pdf:
text = pdf.pages[0].extract_text()
```
## Advanced features
**Form filling**: See [FORMS.md](FORMS.md) for complete guide
**API reference**: See [REFERENCE.md](REFERENCE.md) for all methods
**Examples**: See [EXAMPLES.md](EXAMPLES.md) for common patterns
````
Claude loads FORMS.md, REFERENCE.md, or EXAMPLES.md only when needed.
#### Pattern 2: Domain-specific organization
For Skills with multiple domains, organize content by domain to avoid loading irrelevant context. When a user asks about sales metrics, Claude only needs to read sales-related schemas, not finance or marketing data. This keeps token usage low and context focused.
```
bigquery-skill/
|-- SKILL.md (overview and navigation)
`-- reference/
|-- finance.md (revenue, billing metrics)
|-- sales.md (opportunities, pipeline)
|-- product.md (API usage, features)
`-- marketing.md (campaigns, attribution)
```
````markdown
# BigQuery Data Analysis
## Available datasets
**Finance**: Revenue, ARR, billing -> See [reference/finance.md](reference/finance.md)
**Sales**: Opportunities, pipeline, accounts -> See [reference/sales.md](reference/sales.md)
**Product**: API usage, features, adoption -> See [reference/product.md](reference/product.md)
**Marketing**: Campaigns, attribution, email -> See [reference/marketing.md](reference/marketing.md)
## Quick search
Find specific metrics using grep:
```bash
grep -i "revenue" reference/finance.md
grep -i "pipeline" reference/sales.md
grep -i "api usage" reference/product.md
```
````
#### Pattern 3: Conditional details
Show basic content, link to advanced content:
```markdown
# DOCX Processing
## Creating documents
Use docx-js for new documents. See [DOCX-JS.md](DOCX-JS.md).
## Editing documents
For simple edits, modify the XML directly.
**For tracked changes**: See [REDLINING.md](REDLINING.md)
**For OOXML details**: See [OOXML.md](OOXML.md)
```
Claude reads REDLINING.md or OOXML.md only when the user needs those features.
### Avoid deeply nested references
Claude may partially read files when they're referenced from other referenced files. When encountering nested references, Claude might use commands like `head -100` to preview content rather than reading entire files, resulting in incomplete information.
**Keep references one level deep from SKILL.md**. All reference files should link directly from SKILL.md to ensure Claude reads complete files when needed.
**Bad example: Too deep**:
```markdown
# SKILL.md
See [advanced.md](advanced.md)...
# advanced.md
See [details.md](details.md)...
# details.md
Here's the actual information...
```
**Good example: One level deep**:
```markdown
# SKILL.md
**Basic usage**: [instructions in SKILL.md]
**Advanced features**: See [advanced.md](advanced.md)
**API reference**: See [reference.md](reference.md)
**Examples**: See [examples.md](examples.md)
```
### Structure longer reference files with table of contents
For reference files longer than 100 lines, include a table of contents at the top. This ensures Claude can see the full scope of available information even when previewing with partial reads.
**Example**:
```markdown
# API Reference
## Contents
- Authentication and setup
- Core methods (create, read, update, delete)
- Advanced features (batch operations, webhooks)
- Error handling patterns
- Code examples
## Authentication and setup
...
## Core methods
...
```
Claude can then read the complete file or jump to specific sections as needed.
For details on how this filesystem-based architecture enables progressive disclosure, see the [Runtime environment](#runtime-environment) section in the Advanced section below.
## Workflows and feedback loops
### Use workflows for complex tasks
Break complex operations into clear, sequential steps. For particularly complex workflows, provide a checklist that Claude can copy into its response and check off as it progresses.
**Example 1: Research synthesis workflow** (for Skills without code):
````markdown
## Research synthesis workflow
Copy this checklist and track your progress:
```
Research Progress:
- [ ] Step 1: Read all source documents
- [ ] Step 2: Identify key themes
- [ ] Step 3: Cross-reference claims
- [ ] Step 4: Create structured summary
- [ ] Step 5: Verify citations
```
**Step 1: Read all source documents**
Review each document in the `sources/` directory. Note the main arguments and supporting evidence.
**Step 2: Identify key themes**
Look for patterns across sources. What themes appear repeatedly? Where do sources agree or disagree?
**Step 3: Cross-reference claims**
For each major claim, verify it appears in the source material. Note which source supports each point.
**Step 4: Create structured summary**
Organize findings by theme. Include:
- Main claim
- Supporting evidence from sources
- Conflicting viewpoints (if any)
**Step 5: Verify citations**
Check that every claim references the correct source document. If citations are incomplete, return to Step 3.
````
This example shows how workflows apply to analysis tasks that don't require code. The checklist pattern works for any complex, multi-step process.
**Example 2: PDF form filling workflow** (for Skills with code):
````markdown
## PDF form filling workflow
Copy this checklist and check off items as you complete them:
```
Task Progress:
- [ ] Step 1: Analyze the form (run analyze_form.py)
- [ ] Step 2: Create field mapping (edit fields.json)
- [ ] Step 3: Validate mapping (run validate_fields.py)
- [ ] Step 4: Fill the form (run fill_form.py)
- [ ] Step 5: Verify output (run verify_output.py)
```
**Step 1: Analyze the form**
Run: `python scripts/analyze_form.py input.pdf`
This extracts form fields and their locations, saving to `fields.json`.
**Step 2: Create field mapping**
Edit `fields.json` to add values for each field.
**Step 3: Validate mapping**
Run: `python scripts/validate_fields.py fields.json`
Fix any validation errors before continuing.
**Step 4: Fill the form**
Run: `python scripts/fill_form.py input.pdf fields.json output.pdf`
**Step 5: Verify output**
Run: `python scripts/verify_output.py output.pdf`
If verification fails, return to Step 2.
````
Clear steps prevent Claude from skipping critical validation. The checklist helps both Claude and you track progress through multi-step workflows.
### Implement feedback loops
**Common pattern**: Run validator -> fix errors -> repeat
This pattern greatly improves output quality.
**Example 1: Style guide compliance** (for Skills without code):
```markdown
## Content review process
1. Draft your content following the guidelines in STYLE_GUIDE.md
2. Review against the checklist:
- Check terminology consistency
- Verify examples follow the standard format
- Confirm all required sections are present
3. If issues found:
- Note each issue with specific section reference
- Revise the content
- Review the checklist again
4. Only proceed when all requirements are met
5. Finalize and save the document
```
This shows the validation loop pattern using reference documents instead of scripts. The "validator" is STYLE\_GUIDE.md, and Claude performs the check by reading and comparing.
**Example 2: Document editing process** (for Skills with code):
```markdown
## Document editing process
1. Make your edits to `word/document.xml`
2. **Validate immediately**: `python ooxml/scripts/validate.py unpacked_dir/`
3. If validation fails:
- Review the error message carefully
- Fix the issues in the XML
- Run validation again
4. **Only proceed when validation passes**
5. Rebuild: `python ooxml/scripts/pack.py unpacked_dir/ output.docx`
6. Test the output document
```
The validation loop catches errors early.
## Content guidelines
### Avoid time-sensitive information
Don't include information that will become outdated:
**Bad example: Time-sensitive** (will become wrong):
```markdown
If you're doing this before August 2025, use the old API.
After August 2025, use the new API.
```
**Good example** (use "old patterns" section):
```markdown
## Current method
Use the v2 API endpoint: `api.example.com/v2/messages`
## Old patterns
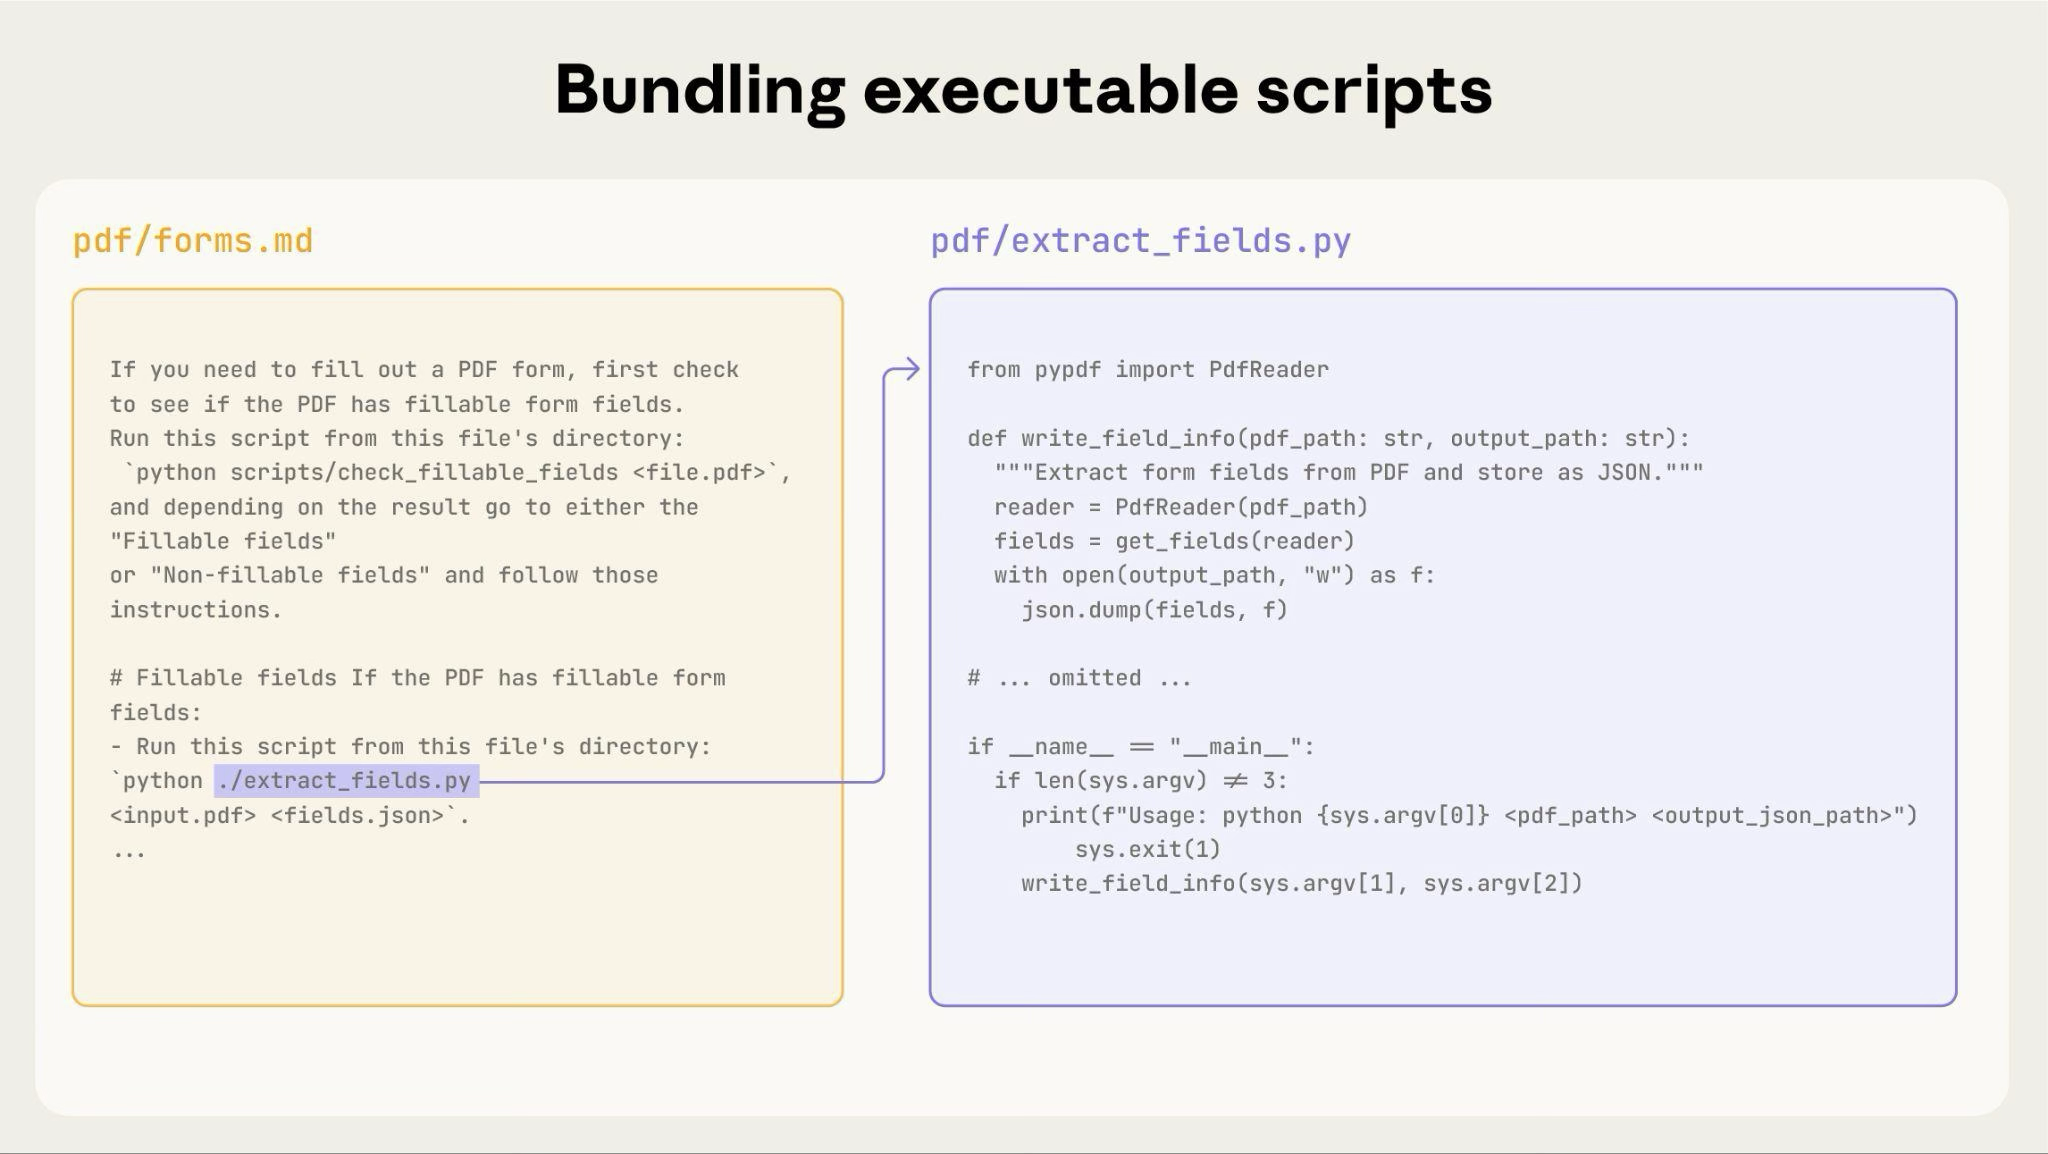 The diagram above shows how executable scripts work alongside instruction files. The instruction file (forms.md) references the script, and Claude can execute it without loading its contents into context.
**Important distinction**: Make clear in your instructions whether Claude should:
* **Execute the script** (most common): "Run `analyze_form.py` to extract fields"
* **Read it as reference** (for complex logic): "See `analyze_form.py` for the field extraction algorithm"
For most utility scripts, execution is preferred because it's more reliable and efficient. See the [Runtime environment](#runtime-environment) section below for details on how script execution works.
**Example**:
````markdown
## Utility scripts
**analyze_form.py**: Extract all form fields from PDF
```bash
python scripts/analyze_form.py input.pdf > fields.json
```
Output format:
```json
{
"field_name": {"type": "text", "x": 100, "y": 200},
"signature": {"type": "sig", "x": 150, "y": 500}
}
```
**validate_boxes.py**: Check for overlapping bounding boxes
```bash
python scripts/validate_boxes.py fields.json
# Returns: "OK" or lists conflicts
```
**fill_form.py**: Apply field values to PDF
```bash
python scripts/fill_form.py input.pdf fields.json output.pdf
```
````
### Use visual analysis
When inputs can be rendered as images, have Claude analyze them:
````markdown
## Form layout analysis
1. Convert PDF to images:
```bash
python scripts/pdf_to_images.py form.pdf
```
2. Analyze each page image to identify form fields
3. Claude can see field locations and types visually
````
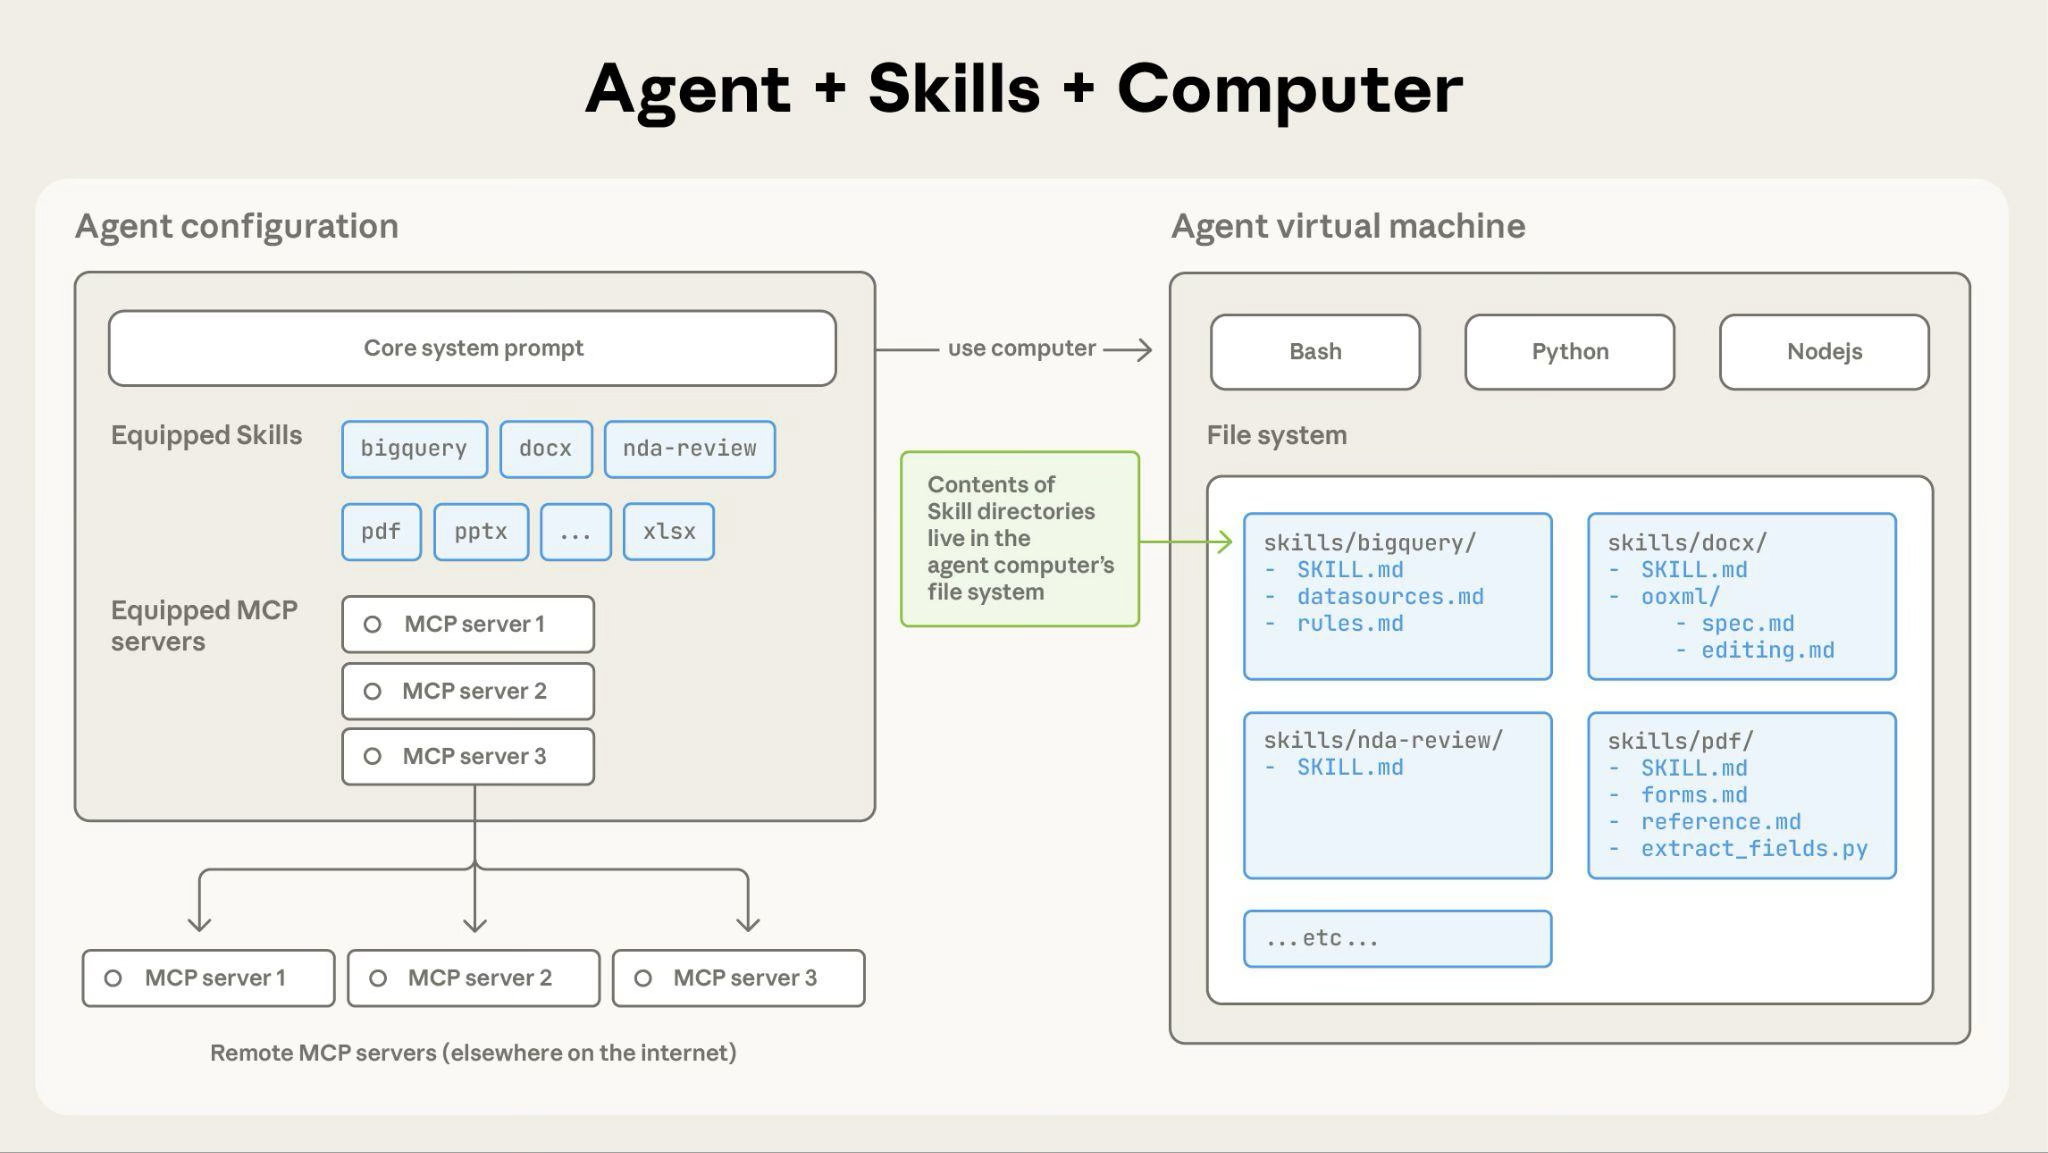 **How Claude accesses Skill content:**
When a Skill is triggered, Claude uses bash to read SKILL.md from the filesystem, bringing its instructions into the context window. If those instructions reference other files (like FORMS.md or a database schema), Claude reads those files too using additional bash commands. When instructions mention executable scripts, Claude runs them via bash and receives only the output (the script code itself never enters context).
**What this architecture enables:**
**On-demand file access**: Claude reads only the files needed for each specific task. A Skill can include dozens of reference files, but if your task only needs the sales schema, Claude loads just that one file. The rest remain on the filesystem consuming zero tokens.
**Efficient script execution**: When Claude runs `validate_form.py`, the script's code never loads into the context window. Only the script's output (like "Validation passed" or specific error messages) consumes tokens. This makes scripts far more efficient than having Claude generate equivalent code on the fly.
**No practical limit on bundled content**: Because files don't consume context until accessed, Skills can include comprehensive API documentation, large datasets, extensive examples, or any reference materials you need. There's no context penalty for bundled content that isn't used.
This filesystem-based model is what makes progressive disclosure work. Claude navigates your Skill like you'd reference specific sections of an onboarding guide, accessing exactly what each task requires.
### Example: Loading a PDF processing skill
Here's how Claude loads and uses a PDF processing skill:
1. **Startup**: System prompt includes: `PDF Processing - Extract text and tables from PDF files, fill forms, merge documents`
2. **User request**: "Extract the text from this PDF and summarize it"
3. **Claude invokes**: `bash: read pdf-skill/SKILL.md` -> Instructions loaded into context
4. **Claude determines**: Form filling is not needed, so FORMS.md is not read
5. **Claude executes**: Uses instructions from SKILL.md to complete the task
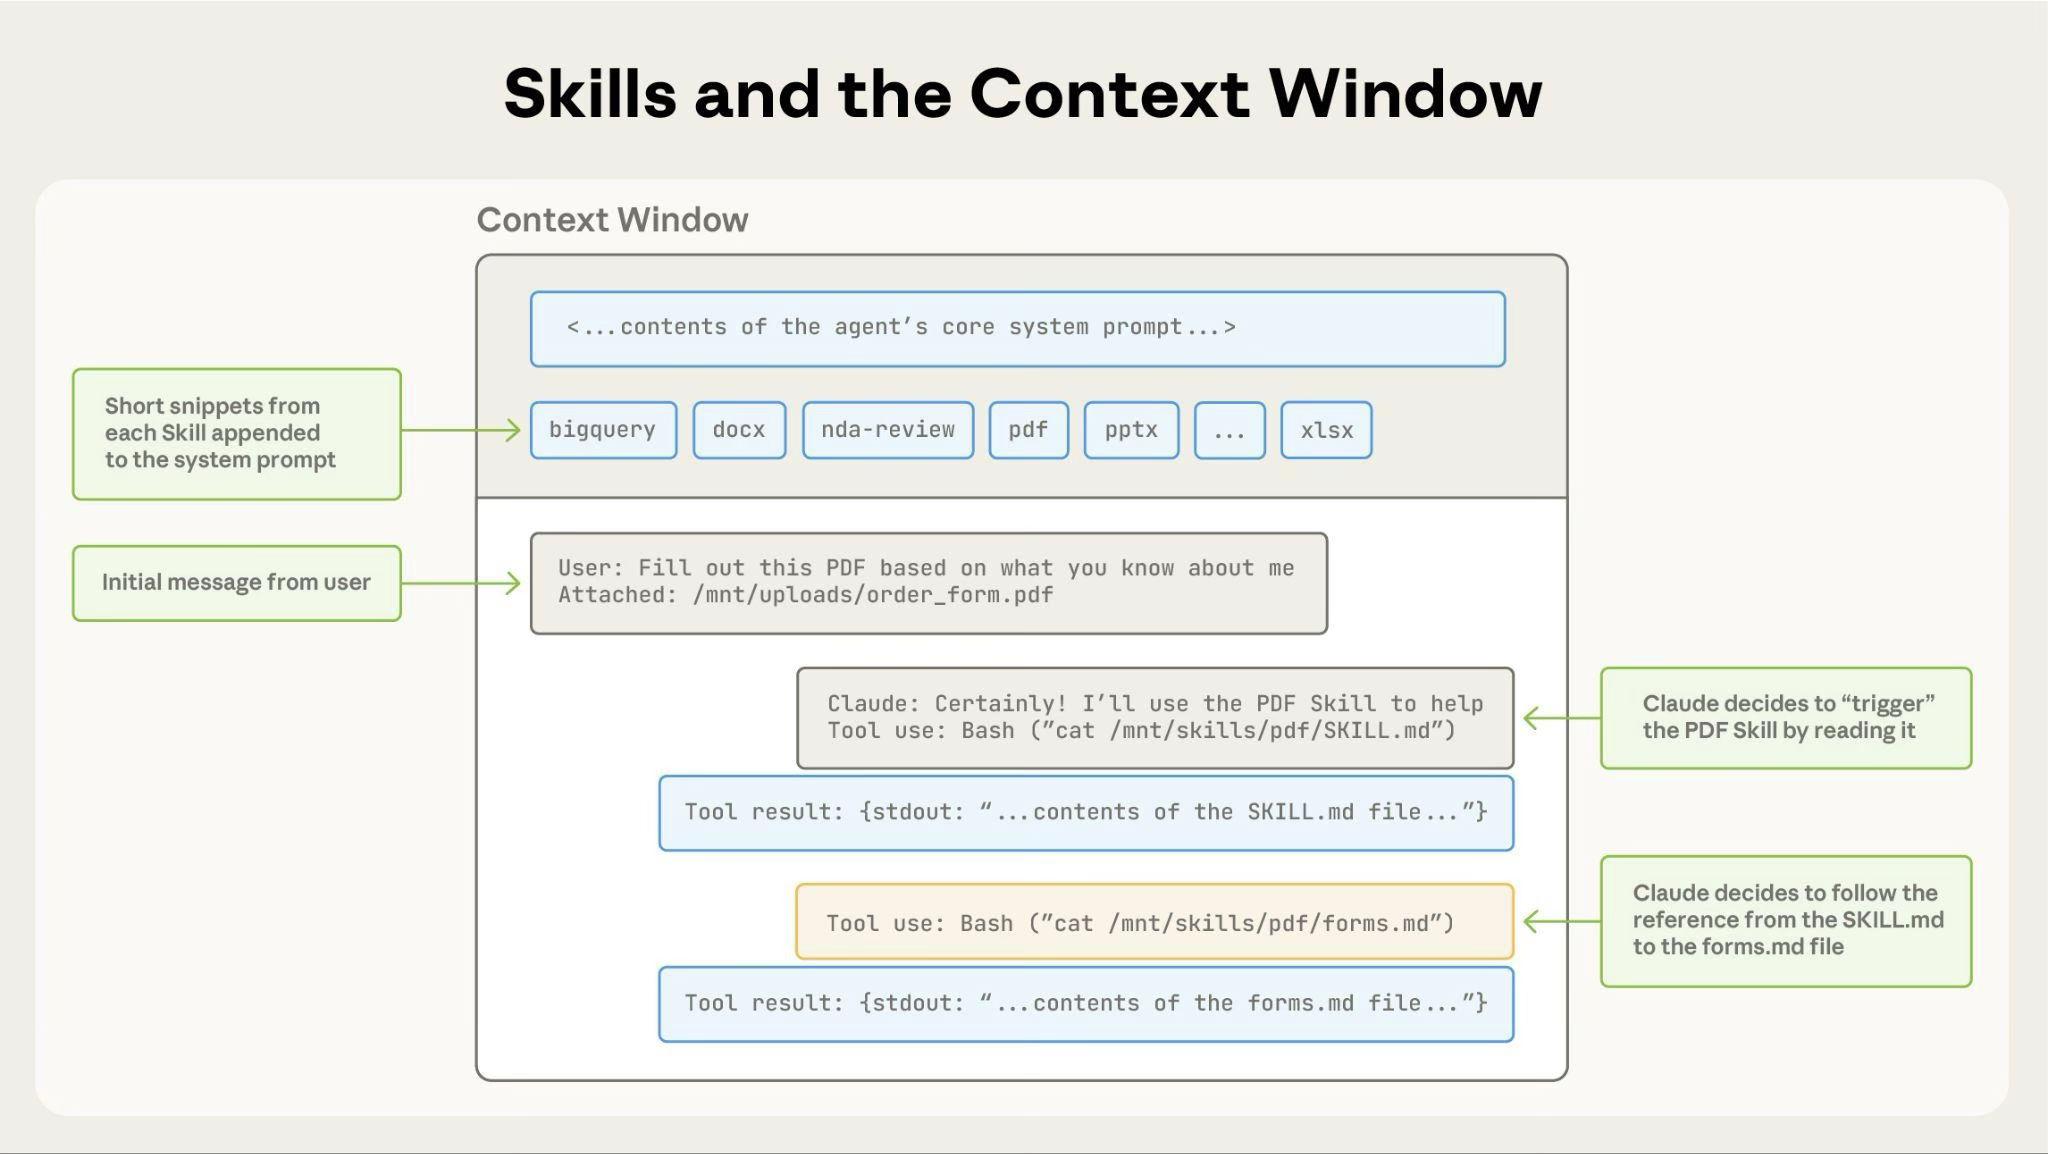 The diagram shows:
1. Default state with system prompt and skill metadata pre-loaded
2. Claude triggers the skill by reading SKILL.md via bash
3. Claude optionally reads additional bundled files like FORMS.md as needed
4. Claude proceeds with the task
This dynamic loading ensures only relevant skill content occupies the context window.
## Where Skills work
Skills are available across Claude's agent products:
### Claude API
The Claude API supports both pre-built Agent Skills and custom Skills. Both work identically: specify the relevant `skill_id` in the `container` parameter along with the code execution tool.
**Prerequisites**: Using Skills via the API requires three beta headers:
* `code-execution-2025-08-25` - Skills run in the code execution container
* `skills-2025-10-02` - Enables Skills functionality
* `files-api-2025-04-14` - Required for uploading/downloading files to/from the container
Use pre-built Agent Skills by referencing their `skill_id` (e.g., `pptx`, `xlsx`), or create and upload your own via the Skills API (`/v1/skills` endpoints). Custom Skills are shared organization-wide.
To learn more, see [Use Skills with the Claude API](/en/api/skills-guide).
### Claude Code
[Claude Code](/en/docs/claude-code/overview) supports only Custom Skills.
**Custom Skills**: Create Skills as directories with SKILL.md files. Claude discovers and uses them automatically.
Custom Skills in Claude Code are filesystem-based and don't require API uploads.
To learn more, see [Use Skills in Claude Code](/en/docs/claude-code/skills).
### Claude.ai
[Claude.ai](https://claude.ai) supports both pre-built Agent Skills and custom Skills.
**Pre-built Agent Skills**: These Skills are already working behind the scenes when you create documents. Claude uses them without requiring any setup.
**Custom Skills**: Upload your own Skills as zip files through Settings > Features. Available on Pro, Max, Team, and Enterprise plans with code execution enabled. Custom Skills are individual to each user; they are not shared organization-wide and cannot be centrally managed by admins.
To learn more about using Skills in Claude.ai, see the following resources in the Claude Help Center:
* [What are Skills?](https://support.claude.com/en/articles/12512176-what-are-skills)
* [Using Skills in Claude](https://support.claude.com/en/articles/12512180-using-skills-in-claude)
* [How to create custom Skills](https://support.claude.com/en/articles/12512198-creating-custom-skills)
* [Tech Claude your way of working using Skills](https://support.claude.com/en/articles/12580051-teach-claude-your-way-of-working-using-skills)
## Skill structure
Every Skill requires a `SKILL.md` file with YAML frontmatter:
```yaml
---
name: Your Skill Name
description: Brief description of what this Skill does and when to use it
---
# Your Skill Name
## Instructions
[Clear, step-by-step guidance for Claude to follow]
## Examples
[Concrete examples of using this Skill]
```
**Required fields**: `name` and `description`
These are the only two fields supported in YAML frontmatter.
**Frontmatter limits**:
* `name`: 64 characters maximum
* `description`: 1024 characters maximum
The `description` should include both what the Skill does and when Claude should use it. For complete authoring guidance, see the [best practices guide](/docs/agent-skills/best-practices).
## Security considerations
We strongly recommend using Skills only from trusted sources: those you created yourself or obtained from Anthropic. Skills provide Claude with new capabilities through instructions and code, and while this makes them powerful, it also means a malicious Skill can direct Claude to invoke tools or execute code in ways that don't match the Skill's stated purpose.